
Big Data Spark Lead at DataMetica · Pune, Hyderabad · 7 - 12 years · ₹7L - ₹20L / yr · Profitable · Posted 25 Aug 2021
 Scala
 Java
Ideal candidates should have technical experience in migrations and the ability to help customers get value from Datametica's tools and accelerators.
Job Description
Experience : 7+ years
Location : Pune / Hyderabad
Skills :
- Drive and participate in requirements gathering workshops, estimation discussions, design meetings and status review meetings
- Participate and contribute in Solution Design and Solution Architecture for implementing Big Data Projects on-premise and on cloud
- Technical Hands on experience in design, coding, development and managing Large Hadoop implementation
- Proficient in SQL, Hive, PIG, Spark SQL, Shell Scripting, Kafka, Flume, Scoop with large Big Data and Data Warehousing projects with either Java, Python or Scala based Hadoop programming background
- Proficient with various development methodologies like waterfall, agile/scrum and iterative
- Good Interpersonal skills and excellent communication skills for US and UK based clients
About Us!
A global Leader in the Data Warehouse Migration and Modernization to the Cloud, we empower businesses by migrating their Data/Workload/ETL/Analytics to the Cloud by leveraging Automation.
We have expertise in transforming legacy Teradata, Oracle, Hadoop, Netezza, Vertica, Greenplum along with ETLs like Informatica, Datastage, AbInitio & others, to cloud-based data warehousing with other capabilities in data engineering, advanced analytics solutions, data management, data lake and cloud optimization.
Datametica is a key partner of the major cloud service providers - Google, Microsoft, Amazon, Snowflake.
We have our own products!
Eagle – Data warehouse Assessment & Migration Planning Product
Raven – Automated Workload Conversion Product
Pelican - Automated Data Validation Product, which helps automate and accelerate data migration to the cloud.
Why join us!
Datametica is a place to innovate, bring new ideas to live and learn new things. We believe in building a culture of innovation, growth and belonging. Our people and their dedication over these years are the key factors in achieving our success.
Benefits we Provide!
Working with Highly Technical and Passionate, mission-driven people
Subsidized Meals & Snacks
Flexible Schedule
Approachable leadership
Access to various learning tools and programs
Pet Friendly
Certification Reimbursement Policy
Check out more about us on our website below!
www.datametica.com


Shubham Vishwakarma
Full Stack Developer - Averlon


About DataMetica
About
Company video

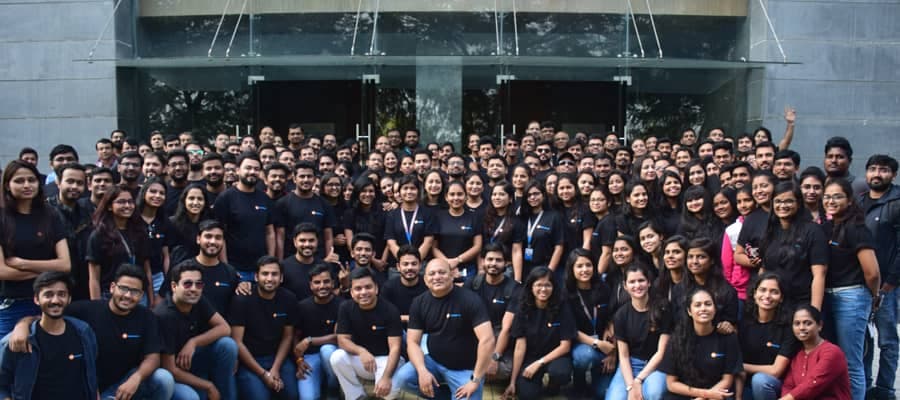
Photos


Company social profiles


Similar jobs (10)


 Python
Job Title : Senior Data Engineer – Databricks
Experience : 14 to 20 Years
Location : HSR Layout, Bangalore
Work Mode : Hybrid – 3 Days WFO
Shift : 11:30 AM – 07:30 PM IST
Positions : 2
Notice Period : Immediate Joiners Only
Interview : 1 Technical Round + 2 Client Rounds
Role Overview :
We are looking for a Senior Data Engineer to build and lead enterprise-scale data platforms for a Switzerland-based commodity client.
The role requires a strong hands-on Data Engineering professional with expertise in Databricks, PySpark, Python, SQL, and AWS, along with technical leadership and stakeholder management experience.
Must-Have Skills :
- 14 to 20 years of Data Engineering experience
- Databricks & Apache Spark / PySpark
- Python & SQL
- AWS Cloud
- Lakehouse Architecture
- ETL / ELT & Distributed Data Processing
- Batch & Streaming Pipelines
- Data Pipeline Optimization & Data Modeling
- CDC & Incremental Processing
- Git, CI/CD & Testing
- Data Quality, Monitoring & Observability
- Technical Leadership & Stakeholder Management
Key Responsibilities :
- Design and build scalable data pipelines using Databricks, PySpark, Python, SQL, and AWS.
- Own data products from design through production.
- Develop batch / streaming pipelines and reusable ETL / ELT frameworks.
- Optimize pipelines for performance, scalability, reliability, and cost.
- Design scalable data architectures and data models.
- Implement data quality, monitoring, lineage, and CI/CD practices.
- Lead technical discussions and mentor engineering teams.
- Collaborate with business stakeholders, architects, product owners, and engineering teams.
- Remain hands-on while providing technical leadership.
Ideal Candidate :
A 14 to 20 years experienced, hands-on Data Engineering leader with strong Databricks + PySpark + AWS expertise, excellent communication, stakeholder management, and experience delivering enterprise-scale data platforms.
🔴 Super Urgent : Only Bangalore-based immediate joiners.
 PythonScala
Job Description:
Position: Lead / Senior Data Engineer
Location: Chennai
Shift: US Eastern Time ( 5:00 PM – 2:00 AM )
Experience : 8+ years
Notice Period: Immediate Joiner only
Roles and Responsibilities:
Role Overview
The Lead Data Engineer will be responsible for designing, developing, and delivering high-quality software and data solutions while leading a team of engineers. The role involves hands-on technical work, architectural decision-making, mentoring junior developers, and collaborating with cross-functional teams to ensure successful delivery of scalable data platforms and analytical solutions.
Key Responsibilities:
Lead the end-to-end design, development, and delivery of software systems, data pipelines, and components.
Define technical strategy, architecture, and best practices for development and data engineering.
Design and build optimized data pipelines using cutting-edge technologies in a cloud environment.
Construct infrastructure for efficient ETL processes from various sources and storage systems.
Architect, design, and maintain database pipeline architectures, ensuring readiness for AI/ML transformations.
Lead the implementation of algorithms and prototypes to transform raw data into useful information.
Review code for quality, scalability, and performance.
Collaborate with Product Managers, Business Managers, Designers, and QA teams to translate business requirements into technical solutions.
Develop analytical tools, programs, and reporting mechanisms.
Create data validation methods and data analysis tools.
Interpret data trends and patterns to establish operational alerts.
Conduct complex data analysis and present results effectively.
Prepare data for prescriptive and predictive modeling.
Ensure compliance with data governance and security policies.
Troubleshoot, debug, and resolve complex technical issues.
Drive continuous improvement in software and data development processes, tools, and methodologies.
Mentor and guide engineers through code reviews, technical discussions, and training.
Ensure timely delivery of projects while maintaining high engineering standards.
Continuously explore opportunities to enhance data quality and reliability.
Apply strong programming and problem-solving skills to develop scalable solutions.
Demonstrate passion for testing strategy, problem-solving, and continuous learning.
Willingness to acquire new skills and knowledge.
Possess a product/engineering mindset to drive impactful data solutions.
Experience working in distributed environments with global teams.
Stay current with emerging technologies and industry trends to propose innovative solutions.
Technical Skills and Experience Requirements
Minimum 8+ years of hands-on experience designing, building, deploying, testing, maintaining, monitoring, and owning scalable, resilient, and distributed data pipelines.
High proficiency in Python, Scala, and Spark for applied large-scale data processing.
Expertise with big data technologies, including Spark, Data Lake, Delta Lake, and Hive.
Solid understanding of batch and streaming data processing techniques.
Proficient knowledge of the Data Lifecycle Management process, including data collection, access, use, storage, transfer, and deletion.
Expert-level ability to write complex, optimized SQL queries across extensive data volumes.
Experience with RDBMS and OLAP databases such as MySQL and Snowflake.
Familiarity with Agile methodologies.
Obsession for service observability, instrumentation, monitoring, and alerting.
Knowledge or experience in architectural best practices for building data lakes.
Qualifications - Bachelor’s degree in computer science, Engineering, Information Systems, or related field.
 Scala
Company Description
TECHSOPHY specializes in productizing solutions based on new technology, focusing on emerging platforms of BPM & ECM, Low Code, AI (ML/RPA/NLP). Founded in 2009, TECHSOPHY operates with headquarters in California, USA, and regional offices in Dubai, UAE, and an offshore innovation center in Hyderabad, India.
Qualifications
- Solid Fundamentals and exceptional problem-solving skills
- Solid and fluent understanding of algorithms and data structures
- Proficiency in Scala + Spark
- Proficiency in Scala + Play framework
- Experience Range: 4 to 7 Years
Requirement:
Some or all of them – because we believe intelligent people can pick up whatever they need in a short period of time. You just need to prove that you can:
- Excellent programming skills and knowledge of Java / Scala
- Excellent software design, problem-solving, and debugging skills
- Experience with modern Big Data technologies such as Spark, NoSQL, Cassandra, Kafka, MapReduce, and the Hadoop ecosystem is a must-have
- Experience with data analytics and the ability to mine data to obtain insights are much appreciated
PythonScalaDescription
We are looking for Senior Data Engineers to join our Data Platform team and build scalable, high-performance data platforms that power data processing, analytics, and downstream applications.
The ideal candidate will have strong experience in distributed data processing, ETL pipelines, and Big Data technologies, with hands-on expertise in Apache Spark and Python Scala.
You will be responsible for designing, developing, and optimizing large-scale data pipelines while collaborating closely with cross-functional engineering teams to build reliable, production-grade data solutions.
Key Responsibilities
- Design, develop, and maintain scalable ETL and data processing pipelines for large-scale datasets.
- Build and optimize distributed data applications using Apache Spark and Python Scala.
- Develop reliable, high-performance data pipelines for batch and streaming workloads.
- Design and manage data workflows using Apache Airflow.
- Build and operate data workloads on AWS, with strong usage of Amazon S3 for large-scale data storage.
- Work with large datasets to ensure data quality, consistency, reliability, and performance.
- Collaborate with engineering, product, analytics, and other platform teams to deliver robust data solutions.
- Optimize data workflows for scalability, reliability, performance, and cost efficiency.
- Troubleshoot production issues, identify bottlenecks, and continuously improve platform performance.
Requirements
Candidates who demonstrate:
- 5+ years of experience in Data Engineering, Big Data Engineering, or a similar role.
- Strong hands-on experience with Apache Spark and Scala.
- Experience designing, building, and maintaining large-scale ETL pipelines.
- Strong hands-on experience with AWS, particularly Amazon S3.
- Hands-on experience with Apache Airflow for workflow orchestration and scheduling.
- Strong SQL skills and a solid understanding of distributed data processing concepts.
- Experience working with batch and/or streaming data pipelines.
- Excellent debugging, problem-solving, and performance optimization skills.
- Strong communication and collaboration skills.
Good to Have
- Experience with Databricks and the broader Databricks data platform.
- Familiarity with streaming technologies such as Apache Kafka.
- Experience working on large-scale data platforms handling high-volume data workloads.
- Exposure to additional AWS data services and cloud-native data architectures.
 KubernetesScala
Description
We are looking for Senior Data Engineers to join our AdTech team and build scalable, high-performance data platforms that power advertising insights and analytics. The ideal candidate will have strong experience in distributed data processing, ETL pipelines, and Big Data technologies, with hands-on expertise in Spark and Scala.
You will work on designing, developing, and optimizing large-scale data pipelines while collaborating closely with cross-functional engineering teams to build reliable, production-grade data solutions.
Key Responsibilities
- Design, develop, and maintain scalable ETL pipelines for large-scale data processing.
- Build and optimize distributed data applications using Spark and Scala.
- Develop reliable, high-performance data pipelines for batch and streaming workloads.
- Work with large datasets to ensure data quality, consistency, and performance.
- Collaborate with engineering, product, and analytics teams to deliver robust data solutions.
- Optimize data workflows for scalability, reliability, and cost efficiency.
- Deploy and manage data workloads in cloud and containerized environments.
- Troubleshoot production issues and continuously improve platform performance.
Requirements
Candidates who demonstrate:
- 5+ years of experience in Data Engineering or Big Data Engineering.
- Strong hands-on experience with Apache Spark and Scala.
- Experience building and maintaining ETL pipelines.
- Familiarity with Google Cloud Storage (GCS).
- Experience with Kubernetes (K8s).
- Strong SQL skills and understanding of distributed data processing.
- Excellent debugging, problem-solving, and performance optimization skills.
- Strong communication and collaboration skills.
Good to Have
- Experience with AWS and cloud-native data services.
- Familiarity with streaming technologies such as Kafka.
- Experience working on large-scale data platforms or AdTech systems.
- Exposure to orchestration tools such as Airflow.
Benefits
- Best-in-class salary: We hire strong talent and compensate accordingly.
- Proximity Talks: Meet and learn from designers, engineers, product leaders, and AI practitioners.
- Continuous learning: Work with a world-class team and stay close to the latest in AI, engineering, and product development.
- High-impact work: Build AI-first systems and products used at scale by global clients.
About Us
Proximity is the trusted technology, design, and consulting partner for some of the biggest Sports, Media, and Entertainment companies in the world. We’re headquartered in San Francisco and have offices in Palo Alto, Dubai, Mumbai, and Bangalore.
Since 2019, Proximity has built high-impact, scalable products used by millions of users every day. Today, we are a global team of engineers, designers, product managers, and experts solving complex problems and building cutting-edge technology at scale.
Define and obtain source data required to deliver insights and use cases.
● Determine data mapping and join multiple data sets across various sources.
● Develop methods to highlight and report data inconsistencies for user review.
● Propose and assist with suitable data migration sets for stakeholders.
● Support teams in processing data migration sets and coordinating migration activities.
● Plan, track, and coordinate the data migration team and migration run-book.
● Collaborate with stakeholders to avoid negative customer and business impacts.
● Ensure robust communication and escalation mechanisms across project portfolios.
● Implement strategic solutions and avoid short-term workarounds.
● Maintain strong control and compliance standards in data handling.
Required Skills
● Minimum 7+ years of experience as a Data Analyst, preferably in financial services.
● Strong expertise in Pyspark, Python, and SQL.
● Experience with big data programs and data models in banking or financial markets.
● Ability to write SQL queries and navigate databases such as Hive, CMD, Putty, and Note++.
● Excellent analytical skills and commercial acumen.
● Strong verbal and written communication skills.
● Proven ability to manage multiple priorities and deliver within tight deadlines.
● Business analysis skills, including defining and understanding requirements.
● Familiarity with SDLC, Agile processes, and a bias towards TDD.
● Attention to detail and a proactive, problem-solving mindset.
Nice to Have
● Knowledge and experience in Data Quality & Governance.
● Working experience with Spark Scala or Java for Spark.
● Proven track record of managing small, delivery-focused data teams (for senior roles).
● Experience with market data vendors and domains such as Party/Client, Trade, Settlements, Payments, Instrument and Pricing, Market and/or Credit Risk.
 Java
 Amazon Web Services (AWS)
Key Responsibilities
Build and maintain data transformation pipelines using java Spark
Develop and optimize large-scale/CPU intensive data processing using Apache Spark
Orchestrate workflows using Airflow
Implement data quality checks, testing, and monitoring for pipeline. Good to have exposer into managing metadata, cataloguing, and lineage
Support schema evolution, backfills, and incremental processing
Ensure pipelines meet SLAs for freshness, reliability, and performance
Expertise/working knowledge in Spark and HBase(semantic layer, virtual datasets, Reflections)
Required Skills & Qualifications
Strong hands-on experience with Apache Spark
Experience with HBase/SQL or similar lakehouse query engines
Airflow
Understanding of data catalogs and lineage (e.g., OpenLineage, DataHub, Apache Polaris , openlineage)
Proficiency in Java
Experience with Git-based development and CI/CD
JavaCompany Name – Wissen Technology
Group of companies in India – Wissen Technology & Wissen Infotech
Work Location – Whitefield, Bangalore
Website and Company profile:
www.wissen.com
LinkedIn Page:
https://www.linkedin.com/company/wissen-technology/
While you may already know about Wissen and the company history, here is a quick rundown for you.
About Wissen Technology:
· The Wissen Group was founded in the year 2000. Wissen Technology, a part of Wissen Group, was established in the year 2015.
· Wissen Technology is a specialized technology company that delivers high-end consulting for organizations in the Banking & Finance, Telecom, and Healthcare domains. We help clients build world class products.
· Our workforce has highly skilled professionals, with leadership and senior management executives who have graduated from Ivy League Universities like Wharton, MIT, IITs, IIMs, and NITs and with rich work experience in some of the biggest companies in the world.
· Wissen Technology has grown its revenues by 400% in these five years without any external funding or investments.
· Globally present with offices US, India, UK, Australia, Mexico, and Canada.
· We offer an array of services including Application Development, Artificial Intelligence & Machine Learning, Big Data & Analytics, Visualization & Business Intelligence, Robotic Process Automation, Cloud, Mobility, Agile & DevOps, Quality Assurance & Test Automation.
· Wissen Technology has been certified as a Great Place to Work®.
· Wissen Technology has been voted as the Top 20 AI/ML vendor by CIO Insider in 2020.
· Over the years, Wissen Group has successfully delivered $650 million worth of projects for more than 20 of the Fortune 500 companies.
· We have served client across sectors like Banking, Telecom, Healthcare, Manufacturing, and Energy. They include likes of Morgan Stanley, Goldman Sachs, MSCI, StateStreet, Flipkart, Swiggy, Trafigura, GE to name a few.
About Role :
Key Responsibilities
- Build and maintain data transformation pipelines using java Spark
- Develop and optimize large-scale/CPU intensive data processing using Apache Spark
- Orchestrate workflows using Airflow
- Implement data quality checks, testing, and monitoring for pipeline. Good to have exposer into managing metadata, cataloguing, and lineage
- Support schema evolution, backfills, and incremental processing
- Ensure pipelines meet SLAs for freshness, reliability, and performance
- Expertise/working knowledge in Spark and HBase(semantic layer, virtual datasets, Reflections)
Required Skills & Qualifications
- Strong hands-on experience with
- HBase
- Apache Spark
- Experience with HBase or similar lakehouse query engines
- Airflow
- Understanding of data catalogs and lineage (e.g., OpenLineage, DataHub, Apache Polaris , openlineage)
- Proficiency in Java
- Experience with Git-based development and CI/CD
Nice-to-Have Skills
- OpenTable format/Iceberg ,Apache Arrow
- CDC-based analytics pipelines
- Cloud platforms (AWS)
- Kubernetes-based data platforms

The recruiter has not been active on this job recently. You may apply but please expect a delayed response.
JavaAmazon Web Services (AWS)Key Responsibilities
Build and maintain data transformation pipelines using java Spark
Develop and optimize large-scale/CPU intensive data processing using Apache Spark
Orchestrate workflows using Airflow
Implement data quality checks, testing, and monitoring for pipeline. Good to have exposer into managing metadata, cataloguing, and lineage
Support schema evolution, backfills, and incremental processing
Ensure pipelines meet SLAs for freshness, reliability, and performance
Expertise/working knowledge in Spark and HBase(semantic layer, virtual datasets, Reflections)
Required Skills & Qualifications
Strong hands-on experience with
HBase
Apache Spark
Experience with HBase or similar lakehouse query engines
Airflow
Understanding of data catalogs and lineage (e.g., OpenLineage, DataHub, Apache Polaris , openlineage)
Proficiency in Java
Experience with Git-based development and CI/CD
Nice-to-Have Skills
OpenTable format/Iceberg ,Apache Arrow
CDC-based analytics pipelines
Cloud platforms (AWS)
Kubernetes-based data platforms
PythonAbout the Role
We are looking for a Senior Data Engineer with strong hands-on expertise in Databricks, Python, PySpark, and SQL to build scalable, high-performance data engineering solutions. You’ll architect and develop large scale, high-performance data pipelines capable of handling massive real-time and batch data volumes across multiple business systems. Databricks is the core enterprise data and processing platform for this role. You will also use Apache Airflow for workflow orchestration and dbt for ELT transformations, and will contribute to designing reliable, secure, and governed data platforms that enable analytics, reporting, and AI-driven use cases.
Key Responsibilities
- Design and implement large-scale data pipelines using Python/PySpark, Databricks, and Microsoft Fabric.
- Develop and optimize data processing workloads in Databricks using PySpark and Spark SQL, with a strong focus on scalability, reliability, performance, and maintainability.
- Develop and maintain dbt models including layered architecture, incremental models, snapshots, macros, testing, and documentation.
- Design, develop, and maintain Apache Airflow DAGs for orchestrating reliable, scalable, and observable data pipelines.
- Design and implement data quality, observability, and governance frameworks, including automated testing, monitoring, lineage, access control, and data privacy standards.
- Partner with analytics, product, and business stakeholders to turn requirements into trustworthy datasets, and raise the engineering bar through design discussions, code reviews, and mentoring junior engineers.
Required Skills
- Strong expertise in Python for developing scalable, modular, and production-ready data engineering applications.
- Strong expertise in PySpark, including DataFrame API, Spark SQL, Structured Streaming, partitioning strategies, joins, caching, handling data skew, and Spark performance optimization.
- Strong hands-on experience with Databricks for data ingestion, transformation, processing, and optimization, including Delta Lake, Unity Catalog, Databricks Workflows, notebooks, jobs, and Databricks-native data engineering capabilities.
- Strong experience in Databricks/Spark performance tuning, including query and job optimization, partitioning, file sizing, caching, join optimization, handling data skew, and efficient use of compute resources.
- Hands-on experience with Delta Lake, including transactional data processing, schema management, incremental data processing, and reliable batch and streaming data pipelines.
- Hands-on experience in developing dbt projects using layered architecture, incremental models, snapshots, macros/Jinja, testing, documentation, and deployment best practices.
- Expertise in advanced SQL and data modelling — dimensional modeling, slowly changing dimensions, schema evolution, and query optimization.
- Hands-on experience in developing and managing Apache Airflow DAGs, scheduling workflows, dependency management, retries, backfills, and operational monitoring.
- Hands-on experience with at least one major cloud platform (AWS, Azure or GCP).
- Strong problem-solving skills and the ability to work independently with business and analytics stakeholders.
Nice to Have
- Hands-on exposure to Microsoft Fabric for data integration and analytics.
- Experience using AI coding assistants (e.g. Claude Code, GitHub Copilot) as part of a development workflow.
- Familiarity with modern DevOps practices, including CI/CD pipelines, Infrastructure as Code (IaC), and containerization (Docker/Kubernetes).
- Domain expertise in financial services.













 Follow Cutshort
Shubham Vishwakarma
Full Stack Developer - Averlon