
Big Data Engineer at Propellor.ai · Remote only · 1 - 4 years · ₹5L - ₹15L / yr · Raised funding · Remote only · Posted 21 Jul 2022

 Python
Big Data Engineer/Data Engineer
What we are solving
Welcome to today’s business data world where:
• Unification of all customer data into one platform is a challenge
• Extraction is expensive
• Business users do not have the time/skill to write queries
• High dependency on tech team for written queries
These facts may look scary but there are solutions with real-time self-serve analytics:
• Fully automated data integration from any kind of a data source into a universal schema
• Analytics database that streamlines data indexing, query and analysis into a single platform.
• Start generating value from Day 1 through deep dives, root cause analysis and micro segmentation
At Propellor.ai, this is what we do.
• We help our clients reduce effort and increase effectiveness quickly
• By clearly defining the scope of Projects
• Using Dependable, scalable, future proof technology solution like Big Data Solutions and Cloud Platforms
• Engaging with Data Scientists and Data Engineers to provide End to End Solutions leading to industrialisation of Data Science Model Development and Deployment
What we have achieved so far
Since we started in 2016,
• We have worked across 9 countries with 25+ global brands and 75+ projects
• We have 50+ clients, 100+ Data Sources and 20TB+ data processed daily
Work culture at Propellor.ai
We are a small, remote team that believes in
• Working with a few, but only with highest quality team members who want to become the very best in their fields.
• With each member's belief and faith in what we are solving, we collectively see the Big Picture
• No hierarchy leads us to believe in reaching the decision maker without any hesitation so that our actions can have fruitful and aligned outcomes.
• Each one is a CEO of their domain.So, the criteria while making a choice is so our employees and clients can succeed together!
To read more about us click here:
https://bit.ly/3idXzs0" target="_blank">https://bit.ly/3idXzs0
About the role
We are building an exceptional team of Data engineers who are passionate developers and wants to push the boundaries to solve complex business problems using the latest tech stack. As a Big Data Engineer, you will work with various Technology and Business teams to deliver our Data Engineering offerings to our clients across the globe.
Role Description
• The role would involve big data pre-processing & reporting workflows including collecting, parsing, managing, analysing, and visualizing large sets of data to turn information into business insights
• Develop the software and systems needed for end-to-end execution on large projects
• Work across all phases of SDLC, and use Software Engineering principles to build scalable solutions
• Build the knowledge base required to deliver increasingly complex technology projects
• The role would also involve testing various machine learning models on Big Data and deploying learned models for ongoing scoring and prediction.
Education & Experience
• B.Tech. or Equivalent degree in CS/CE/IT/ECE/EEE 3+ years of experience designing technological solutions to complex data problems, developing & testing modular, reusable, efficient and scalable code to implement those solutions.
Must have (hands-on) experience
• Python and SQL expertise
• Distributed computing frameworks (Hadoop Ecosystem & Spark components)
• Must be proficient in any Cloud computing platforms (AWS/Azure/GCP) • Experience in in any cloud platform would be preferred - GCP (Big Query/Bigtable, Pub sub, Data Flow, App engine )/ AWS/ Azure
• Linux environment, SQL and Shell scripting Desirable
• Statistical or machine learning DSL like R
• Distributed and low latency (streaming) application architecture
• Row store distributed DBMSs such as Cassandra, CouchDB, MongoDB, etc
. • Familiarity with API design
Hiring Process:
1. One phone screening round to gauge your interest and knowledge of fundamentals
2. An assignment to test your skills and ability to come up with solutions in a certain time
3. Interview 1 with our Data Engineer lead
4. Final Interview with our Data Engineer Lead and the Business Teams
Preferred Immediate Joiners


Shubham Vishwakarma
Full Stack Developer - Averlon


About Propellor.ai
About
Who we are
At Propellor, we are passionate about solving Data Unification challenges faced by our clients. We build solutions using the latest tech stack. We believe all solutions lie in the congruence of Business, Technology, and Data Science. Combining the 3, our team of young Data professionals solves some real-world problems. Here's what we live by:
Skin in the game
We believe that Individual and Collective success orientations both propel us ahead.
Cross Fertility
Borrowing from and building on one another’s varied perspectives means we are always viewing business problems with a fresh lens.
Sub 25's
A bunch of young turks, who keep our explorer mindset alive and kicking.
Future-proofing
Keeping an eye ahead, we are upskilling constantly, staying relevant at any given point in time.
Tech Agile
Tech changes quickly. Whatever your stack, we adapt speedily and easily.
If you are evaluating us to be your next employer, we urge you to read more about our team and culture here: https://bit.ly/3ExSNA2. We assure you, it's worth a read!
Tech stack
Python Machine Learning (ML)
Company video

Candid answers by the company
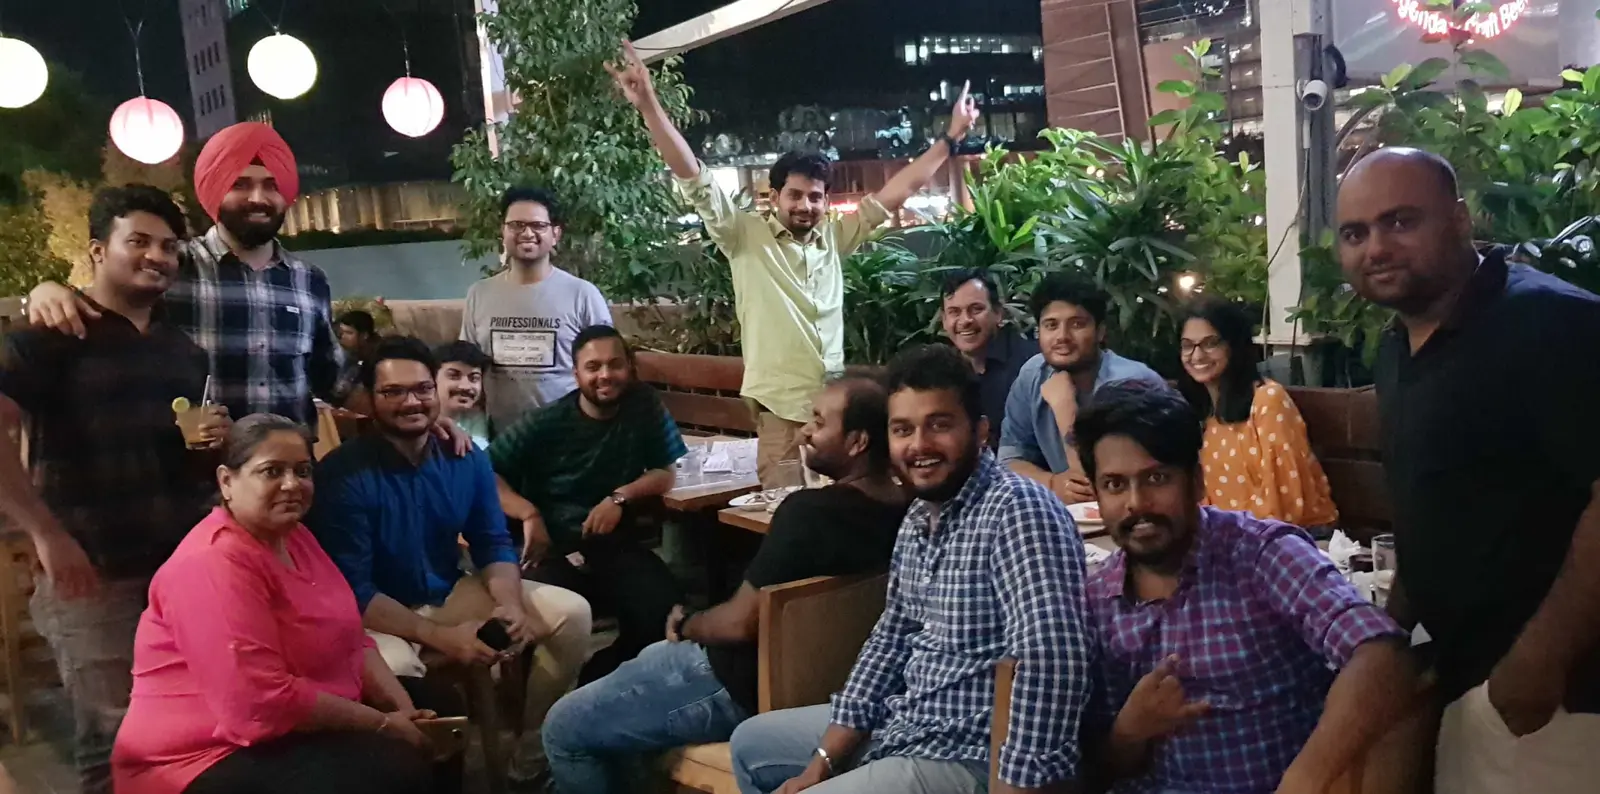
Photos



Company social profiles


Similar jobs (10)

 Python
Job Description – Data Engineer
Role: Data Engineer
Experience: 9+ Years
Location: Bangalore / Hyderabad
Notice Period: Immediate to 15 Days
Interview Process: 1st Round – Virtual | 2nd Round – F2F
Mandatory Skills
- Python
- PySpark
- SQL
- Azure Data Engineering
Job Description
We are looking for an experienced Azure Data Engineer with 9+ years of experience and strong hands-on expertise in Python, PySpark, SQL, and Azure Data Engineering.
Key Responsibilities
- Develop and maintain scalable data engineering solutions using Azure.
- Build and optimize data processing pipelines using PySpark and Python.
- Write complex SQL queries for data extraction and transformation.
- Work with Azure data services and cloud-based data platforms.
- Perform data processing, transformation, and integration.
- Troubleshoot data pipeline and production issues.
- Collaborate with technical and business teams to deliver data solutions.
Preferred: Immediate to 15 Days joiners.
 Python
1st virtual , 2nd round F2F
Python pyspark, SQL, data engineer
5+yrs
9+yrs
Bangalore/Hyderabad
immediate to 15days.

 Python
Job Summary
We are looking for a skilled and experienced Data Engineer to join our growing data team. The ideal candidate will have strong expertise in Python, PySpark, Data Modeling, and Power BI, with hands-on experience in designing, developing, and optimizing scalable data solutions. The role requires working closely with business stakeholders, data architects, and analytics teams to build robust data pipelines and semantic models that enable data-driven decision-making.
Technical Skills
- Strong hands-on experience in Python and PySpark development.
- Expertise in building and optimizing Data Engineering solutions and ETL pipelines.
- Strong understanding of Data Modeling concepts (Star Schema, Snowflake Schema, Dimensional Modeling).
- Experience with Power BI Data Modeling and Semantic Layer development.
- Proficiency in DAX (Data Analysis Expressions).
- Experience designing and managing Semantic Models in Power BI.
- Strong SQL skills and experience working with large datasets.
- Knowledge of data warehousing concepts and best practices.
Preferred Skills
- Experience with cloud platforms such as Azure, AWS, or GCP.
- Exposure to modern data platforms like Databricks.
- Understanding of data governance and data quality frameworks.
 Python
 Scala
Description
We are looking for Senior Data Engineers to join our Data Platform team and build scalable, high-performance data platforms that power data processing, analytics, and downstream applications.
The ideal candidate will have strong experience in distributed data processing, ETL pipelines, and Big Data technologies, with hands-on expertise in Apache Spark and Python Scala.
You will be responsible for designing, developing, and optimizing large-scale data pipelines while collaborating closely with cross-functional engineering teams to build reliable, production-grade data solutions.
Key Responsibilities
- Design, develop, and maintain scalable ETL and data processing pipelines for large-scale datasets.
- Build and optimize distributed data applications using Apache Spark and Python Scala.
- Develop reliable, high-performance data pipelines for batch and streaming workloads.
- Design and manage data workflows using Apache Airflow.
- Build and operate data workloads on AWS, with strong usage of Amazon S3 for large-scale data storage.
- Work with large datasets to ensure data quality, consistency, reliability, and performance.
- Collaborate with engineering, product, analytics, and other platform teams to deliver robust data solutions.
- Optimize data workflows for scalability, reliability, performance, and cost efficiency.
- Troubleshoot production issues, identify bottlenecks, and continuously improve platform performance.
Requirements
Candidates who demonstrate:
- 5+ years of experience in Data Engineering, Big Data Engineering, or a similar role.
- Strong hands-on experience with Apache Spark and Scala.
- Experience designing, building, and maintaining large-scale ETL pipelines.
- Strong hands-on experience with AWS, particularly Amazon S3.
- Hands-on experience with Apache Airflow for workflow orchestration and scheduling.
- Strong SQL skills and a solid understanding of distributed data processing concepts.
- Experience working with batch and/or streaming data pipelines.
- Excellent debugging, problem-solving, and performance optimization skills.
- Strong communication and collaboration skills.
Good to Have
- Experience with Databricks and the broader Databricks data platform.
- Familiarity with streaming technologies such as Apache Kafka.
- Experience working on large-scale data platforms handling high-volume data workloads.
- Exposure to additional AWS data services and cloud-native data architectures.

 JavaPython
We are hiring for a Data Engineer & Java scala for a full-time opportunity in Bangalore.
Experience: 4–10 Years
Must-Have Skills:
Java / Scala / Python, Data Engineering, Databricks / Snowflake, and Cloud (AWS / Azure / GCP).
We are looking for strong software engineers with hands-on experience in data platform development, scalable backend programming, data integration, and cloud technologies.
Experience in Banking, Capital Markets, Market Risk, or Regulatory Reporting will be an added advantage.
PythonScala🚨 HIRING | Data Engineer – Amazon EMR 🔥
We are looking for experienced Data Engineers with strong hands-on expertise in Amazon EMR, Python, and Scala.
📌 JOB DETAILS:
💼 Experience: 6+ Years
💰 CTC: Up to 30 LPA
📍 Location: Bangalore
🔑 MANDATORY SKILLS:
• Amazon EMR
• Python
• Scala
• Data Engineering
📋 KEY REQUIREMENTS:
• 6+ years of relevant experience in Data Engineering.
• Strong hands-on experience with Amazon EMR.
• Strong programming skills in Python and Scala.
• Experience with large-scale data processing and data engineering solutions.
• Strong problem-solving and communication skills.
📩 Interested candidates can share their updated resumes:
📧 pavithra.e @vysystems. com
📞 8 9 2 5 8 0 2 4 5 7
🔄 Know someone who would be a good fit? Tag them or share this post!
#Hiring #DataEngineer #DataEngineering #AmazonEMR #Python #Scala #AWSJobs #BangaloreJobs #ITJobs #TechHiring #HiringNow
 Python
1st virtual , 2nd round F2F
Python pyspark, SQL, data engineer
5+yrs
Bang/hyderabad
immediate to 15days.
 Python
About Solutionara
Solutionara is an AI-led IT Consulting and Technology Services organization delivering enterprise transformation through Cloud, Integration, Data Engineering, Digital Experience, AI, and Enterprise Applications.
Headquartered in the United States with a Global Delivery Center (GDC) in Noida, India, Solutionara partners with enterprise organizations across retail, manufacturing, distribution, consumer goods, and other industries to design, implement, and support scalable technology solutions.
As a rapidly growing consulting organization, we foster a culture of ownership, innovation, collaboration, and continuous improvement, empowering our teams to contribute beyond their immediate responsibilities while delivering exceptional value to our global clients.
Every team member is expected to think like a consultant and business problem solver—understanding client objectives, challenging assumptions when appropriate, leveraging AI responsibly, and continuously identifying opportunities to improve quality, productivity, and customer outcomes.
AI is embedded into how we work, but it is an enabler—not a replacement for expertise, critical thinking, or accountability.
Role Overview
Solutionara is seeking a Senior Data Engineer with strong data engineering and database expertise to design, build, optimize, and support enterprise-scale data solutions.
This is a hands-on engineering position requiring strong SQL, Python, ETL/ELT, database, cloud, and troubleshooting capabilities. The engineer will work closely with technical leads and client stakeholders while taking ownership of major engineering components.
Location: Noida, India – Onsite | Employment Type: Full-Time | Experience: 6–9 Years
Key Responsibilities
Data Engineering
- Design, develop, test, deploy, and support scalable ETL/ELT pipelines.
- Build ingestion and transformation solutions across databases, APIs, files, and enterprise applications.
- Develop high-quality SQL and Python-based data processing solutions.
- Implement batch and incremental data-processing patterns.
- Develop reusable engineering components and frameworks.
- Support complex data migration and transformation activities.
- Perform source-to-target mapping and technical data analysis.
- Implement pipeline logging, monitoring, exception handling, and recovery mechanisms.
Database & Platform Engineering
- Design and optimize relational database schemas and data structures.
- Analyze and improve SQL/query performance.
- Support indexing, partitioning, storage optimization, and database performance.
- Implement appropriate database security and access controls.
- Support database monitoring, availability, backup/recovery, and operational requirements in collaboration with infrastructure/platform teams.
- Troubleshoot database and pipeline performance issues.
- Contribute to cloud data-platform configuration and optimization.
Data Quality
- Implement automated validation and data-quality controls.
- Develop reconciliation processes between source and target systems.
- Identify duplicate, incomplete, inconsistent, and invalid data.
- Implement cleansing, standardization, validation, and exception-management logic.
- Work with technical and business stakeholders to understand and implement business data rules.
Technical Delivery
- Convert technical designs into reliable production solutions.
- Participate in technical design and code reviews.
- Mentor junior/mid-level engineers.
- Support estimation and technical planning.
- Troubleshoot complex production and integration issues.
- Collaborate with technical leads, application teams, DevOps, QA, BI, and client teams.
- Document technical designs, mappings, configurations, operational procedures, and engineering decisions.
Consulting & AI-Led Working
- Understand the business purpose behind assigned engineering requirements.
- Raise risks, assumptions, dependencies, and potential improvements proactively.
- Communicate effectively with client and internal stakeholders.
- Use AI-assisted tools to improve coding, testing, analysis, documentation, and troubleshooting productivity.
- Independently verify AI-generated code and recommendations before implementation.
- Identify opportunities for engineering automation and process improvement.
Required Qualifications
- 6–9 years of experience in data engineering, database engineering, data integration, or related areas.
- Advanced SQL skills.
- Strong hands-on Python experience.
- Strong ETL/ELT development experience.
- Strong relational database knowledge, such as SQL Server, PostgreSQL, Oracle, or equivalent.
- Experience with data modeling and database design.
- Experience with AWS, Azure, or another major cloud platform.
- Experience with modern data technologies such as Databricks, Snowflake, Redshift, Synapse, Glue, ADF, Airflow, dbt, or equivalent.
- Experience with performance tuning and optimization.
- Experience with data validation and reconciliation.
- Strong troubleshooting and analytical skills.
- Ability to take ownership of engineering deliverables with limited supervision.
Preferred Qualifications
- Experience working with enterprise ERP, CRM, PIM, PLM, MES, or related systems.
- Experience with manufacturing, retail, distribution, or consumer-goods data.
- Experience with CI/CD and infrastructure/platform engineering practices.
- Experience with API and event-driven integrations.
- Previous consulting or technology-services experience.
What Success Looks Like
- Pipelines and databases perform reliably at enterprise scale.
- Engineering solutions are maintainable, reusable, and well documented.
- Data issues are detected and addressed systematically.
- Junior engineers receive effective technical guidance.
- Problems are owned through resolution rather than simply escalated.
- Engineering decisions reflect both technical requirements and client business objectives.
 Python
Job Title : Data / AI / GenAI – Engineering & Analytics
Experience : 4+ Years
Location : Noida / Gurugram / Ahmedabad
Employment Type : Full-time | On-site at client location
Working Days : 5 days per week
Working Hours : Standard business hours
Position Overview : We are seeking professionals to deliver modern data engineering, business intelligence, cloud analytics and AI-powered applications, according to their specialization.
Mandatory Skills :
Python, SQL, ETL/ELT, Data Engineering, Power BI, Azure Data Factory, Databricks, PySpark, Data Modeling, GenAI/LLMs, RAG, Vector Databases, AI Agents (as per role specialization).
Key Roles / Specializations :
- Power BI Developers : Dashboards, DAX, Power Query, reporting and data modeling
- Azure Data Engineers : Azure Data Factory, Data Lake, Azure SQL and cloud pipelines
- Databricks Engineers : Apache Spark, PySpark, Delta Lake and scalable processing
- Data Engineers : ETL/ELT, SQL, Python, data warehousing and quality
- GenAI / RAG Engineers : LLMs, prompts, embeddings, vector databases and retrieval pipelines
- Agentic AI Engineers : AI agents, tool calling, orchestration and multi-agent workflows
Key Responsibilities :
- Design, develop and maintain data pipelines, analytics solutions or AI applications.
- Build and optimize data integration, transformation and processing workflows.
- Develop dashboards and analytical models for business decision-making.
- Use cloud data platforms and modern engineering frameworks.
- Develop and evaluate LLM applications, RAG solutions or AI agents as applicable.
- Ensure data quality, security, performance and reliability.
- Collaborate with engineering teams and stakeholders on testing, deployment and documentation.
Required Skills & Qualifications :
- Bachelor’s degree in Computer Science, IT, Data Science, Engineering or related discipline.
- 4–5 years of relevant experience in data, analytics, AI or software engineering.
- Hands-on expertise in at least one listed specialization; not all technologies are required.
- Relevant Python, SQL, DAX or other technical skills depending on the position.
- Understanding of cloud platforms, APIs, integration and software practices.
Preferred Qualifications :
- Azure, Databricks or Microsoft Fabric experience.
- For GenAI roles : Azure OpenAI, OpenAI APIs, LangChain, LlamaIndex or LangGraph.
- For relevant roles : vector databases, CI/CD, Docker, MLOps or LLMOps.
Note : Candidates are expected to have expertise in their relevant specialization, not in every listed technology or role.
Python1st virtual , 2nd round F2F -
Python pyspark, SQL, data engineer
5+yrs
Bang/hyderabad
immediate to 15days.













 Follow Cutshort
Shubham Vishwakarma
Full Stack Developer - Averlon