
Data Governance Architecture at Kanerika Software · Hyderabad · 15 - 25 years · ₹40L - ₹50L / yr · Profitable · Posted 14 Nov 2025

Data Governance Architect
About Kanerika
Who we are:
Kanerika Inc. is a premier global software products and services firm that specializes in providing innovative solutions and services for data-driven enterprises. Our focus is to empower businesses to achieve their digital transformation goals and maximize their business impact through the effective use of data and AI. We leverage cutting-edge technologies in data analytics, data governance, AI-ML, GenAI/ LLM and industry best practices to deliver custom solutions that help organizations optimize their operations, enhance customer experiences, and drive growth.
Awards and Recognitions
Kanerika has won several awards over the years, including:
CMMI Level 3 Appraised in 2024.
Best Place to Work 2022 & 2023 by Great Place to Work®.
Top 10 Most Recommended RPA Start-Ups in 2022 by RPA today.
NASSCOM Emerge 50 Award in 2014.
Frost & Sullivan India 2021 Technology Innovation Award for its Kompass composable solution architecture.
Recognized for ISO 27701, 27001, SOC2, and GDPR compliances.
Featured as Top Data Analytics Services Provider by GoodFirms.
Working for us
Kanerika is rated 4.6/5 on Glassdoor, for many good reasons. We truly value our employees' growth, well-being, and diversity, and people’s experiences bear this out. At Kanerika, we offer a host of enticing benefits that create an environment where you can thrive both personally and professionally. From our inclusive hiring practices and mandatory training on creating a safe work environment to our flexible working hours and generous parental leave, we prioritize the well-being and success of our employees. Our commitment to professional development is evident through our mentorship programs, job training initiatives, and support for professional certifications. Additionally, our company-sponsored outings and various time-off benefits ensure a healthy work-life balance. Join us at Kanerika and become part of a vibrant and diverse community where your talents are recognized, your growth is nurtured, and your contributions make a real impact. See the benefits section below for the perks you’ll get while working for Kanerika.
Locations
We are located in Austin (USA), Singapore, Hyderabad, Indore and Ahmedabad (India).
What You Will Do:
As a Data Governance Architect at Kanerika, you will play a pivotal role in shaping and executing the enterprise data governance strategy. Your responsibilities include:
1. Strategy, Framework, and Governance Operating Model
- Develop and maintain enterprise-wide data governance strategies, standards, and policies.
- Align governance practices with business goals like regulatory compliance and analytics readiness.
- Define roles and responsibilities within the governance operating model.
- Drive governance maturity assessments and lead change management initiatives.
2. Stakeholder Alignment & Organizational Enablement
- Collaborate across IT, legal, business, and compliance teams to align governance priorities.
- Define stewardship models and create enablement, training, and communication programs.
- Conduct onboarding sessions and workshops to promote governance awareness.
3. Architecture Design for Data Governance Platforms
- Design scalable and modular data governance architecture.
- Evaluate tools like Microsoft Purview, Collibra, Alation, BigID, Informatica.
- Ensure integration with metadata, privacy, quality, and policy systems.
4. Microsoft Purview Solution Architecture
- Lead end-to-end implementation and management of Microsoft Purview.
- Configure RBAC, collections, metadata scanning, business glossary, and classification rules.
- Implement sensitivity labels, insider risk controls, retention, data map, and audit dashboards.
5. Metadata, Lineage & Glossary Management
- Architect metadata repositories and ingestion workflows.
- Ensure end-to-end lineage (ADF → Synapse → Power BI).
- Define governance over business glossary and approval workflows.
6. Data Classification, Access & Policy Management
- Define and enforce rules for data classification, access, retention, and sharing.
- Align with GDPR, HIPAA, CCPA, SOX regulations.
- Use Microsoft Purview and MIP for policy enforcement automation.
7. Data Quality Governance
- Define KPIs, validation rules, and remediation workflows for enterprise data quality.
- Design scalable quality frameworks integrated into data pipelines.
8. Compliance, Risk, and Audit Oversight
- Identify risks and define standards for compliance reporting and audits.
- Configure usage analytics, alerts, and dashboards for policy enforcement.
9. Automation & Integration
- Automate governance processes using PowerShell, Azure Functions, Logic Apps, REST APIs.
- Integrate governance tools with Azure Monitor, Synapse Link, Power BI, and third-party platforms.
Required Qualifications:
- 15+ years in data governance and management.
- Expertise in Microsoft Purview, Informatica, and related platforms.
- Experience leading end-to-end governance initiatives.
- Strong understanding of metadata, lineage, policy management, and compliance regulations.
- Hands-on skills in Azure Data Factory, REST APIs, PowerShell, and governance architecture.
- Familiar with Agile methodologies and stakeholder communication.


Shubham Vishwakarma
Full Stack Developer - Averlon


About Kanerika Software
About
Since 2015, Kanerika has been helping businesses turn ideas into impactful software products. With over 75 years of collective expertise, our team brings together deep product engineering knowledge and a passion for solving complex challenges. We focus on building software that is not just functional but transformative—solutions that create lasting value for our clients.
At Kanerika, we believe great outcomes come from strong partnerships, proven experience, and creative thinking. That’s why we keep our team lean, our approach hands-on, and our commitment unwavering: to deliver products that exceed expectations every time.
Candid answers by the company
Kanerika designs and develops software products that transform business challenges into lasting value.
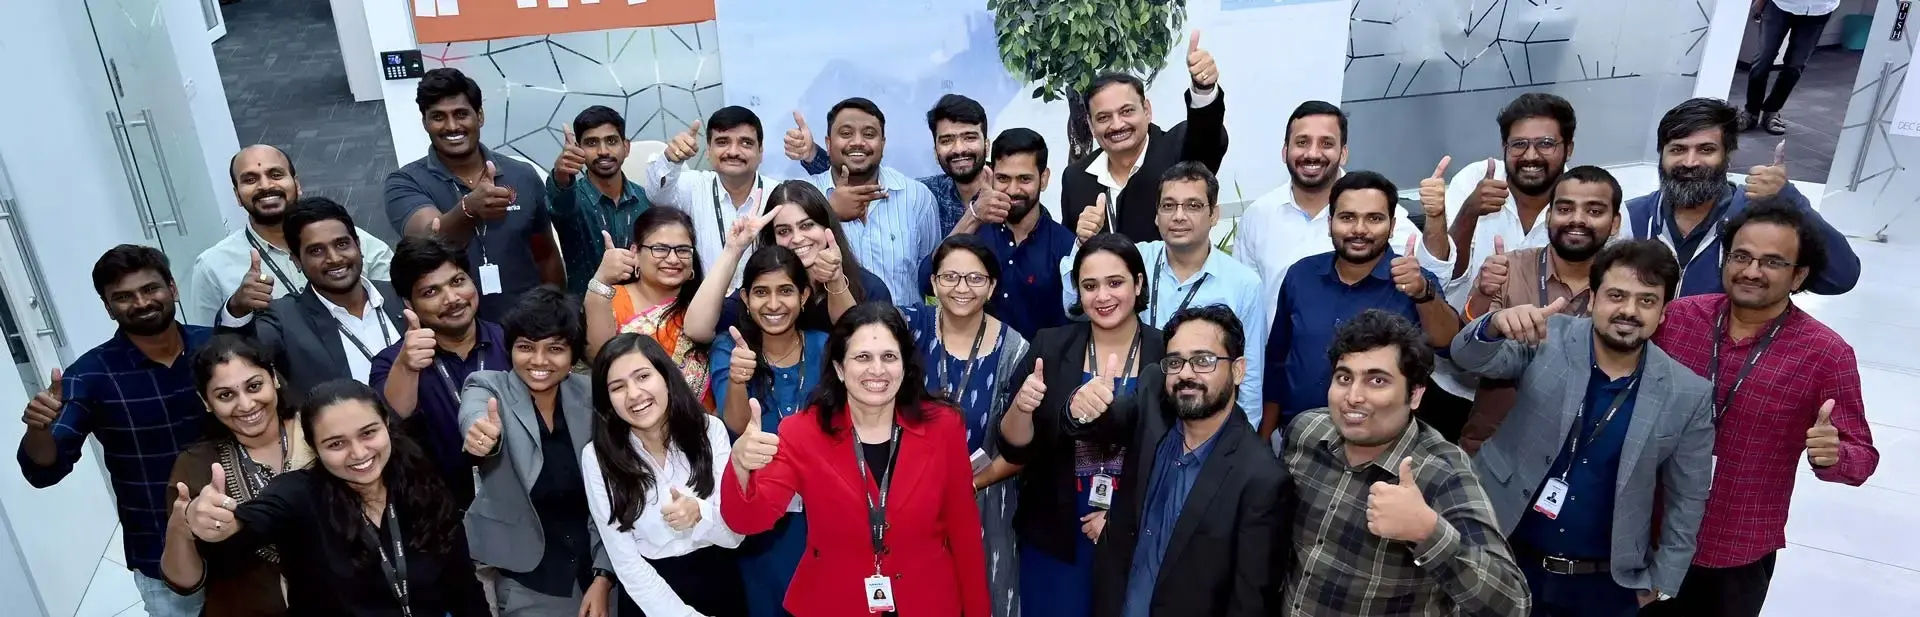
Photos

Company social profiles


Similar jobs (10)

Roles & Responsibilities:-
- Develop and maintain enterprise data governance strategies, policies, and standards aligned with business goals
- Manage Microsoft Purview accounts, collections, and RBAC; optimize for large-scale environments (50TB+)
- Design metadata repositories and maintain business glossaries and data dictionaries
- Implement ingestion workflows via ADF, REST APIs, PowerShell, Azure Functions
- Define classification rules and sensitivity labels (PII, PCI, PHI); integrate with MIP, DLP, Insider Risk Management
- Define KPIs and dashboards to monitor data quality across domains
- Maintain business glossary with domain owners and stewards; enforce approval workflows
- Automate governance processes using PowerShell, Azure Functions, Logic Apps
- Set up dashboards for audit logs, compliance reporting, and metadata coverage
- Collaborate across business, IT, legal, and compliance teams for role alignment
Ideal Candidate:-
- Strong Data Governance Lead Profile with deep Microsoft Purview and enterprise governance expertise
- Mandatory (Experience 1): Must have 7+ years of experience in data governance and data management with at least the recent 3+ years of exposure in Microsoft Purview
- Mandatory (Experience 2): Must have experience defining, leading, and operationalizing an enterprise data governance framework — strategy, policies, and standards aligned to business goals and regulatory compliance.
- Mandatory (Tech skill 1): Must be proficient in Microsoft Purview — accounts, collections, RBAC, classification/labelling, DLP, Unified Catalog, Data Map, eDiscovery, Compliance Manager, and lifecycle/records management (ideally at large scale, 50TB+).
- Mandatory (Tech skill 2): Must be strong in metadata management, lineage mapping (e.g. ADF → Synapse → Power BI), data classification, and security governance (PII/PCI/PHI, sensitivity labels, MIP/DLP)
- Mandatory (Tech skill 3): Must have experience with data governance tools such as Informatica (Axon), Collibra, Atlan, or IBM IG Catalog.
- Mandatory (Tech skill 4): Must have experience integrating governance with the Azure data stack (Data Lake, Synapse, SQL DB, Power BI) and Snowflake, and automating via ADF, REST APIs, PowerShell, Azure Functions / Logic Apps.
- Mandatory (Tech skill 5): Must have experience defining data quality KPIs/dashboards, remediation workflows, and business glossary/stewardship (domain owners, approval workflows, metadata audits)
- Mandatory (Compliance): Must have strong knowledge of GDPR, CCPA, HIPAA, and SOX compliance requirements.
- Mandatory (Skill): Must be able to bridge technical governance with business and compliance goals, collaborating across business, IT, legal, and compliance teams, and driving governance training and change management
- Mandatory (Company): B2B Tech/Consulting/B2B Software


About the Role
We are looking for an experienced Power BI Architect to lead enterprise-wide BI initiatives. This role will be responsible for designing, implementing, and governing scalable Power BI solutions across the organization. The ideal candidate will play a key role in establishing best practices, driving adoption, and owning the overall BI architecture within the Center of Excellence (CoE).
Key Responsibilities
- Lead end-to-end implementation of Power BI solutions across the enterprise
- Design scalable, secure, and high-performance BI architecture
- Act as the Power BI Architect, providing technical leadership and direction
- Own and drive BI governance, standards, and best practices within the CoE
- Collaborate with business and technology teams to translate requirements into robust BI solutions
- Define data modeling strategies, reporting frameworks, and dashboard standards
- Ensure data accuracy, consistency, and performance optimization across reports
- Support and guide development teams in Power BI implementation
- Enable enterprise-wide adoption of Power BI through training, documentation, and mentorship
- Work closely with IT/technology teams to integrate Power BI with data platforms and enterprise systems
Required Skills & Qualifications
- 10+ years of experience in BI/Data Analytics, with strong focus on Power BI
- Proven experience in enterprise-wide Power BI implementation
- Strong expertise in:
- Power BI (Desktop, Service, Gateway, Dataflows)
- Data Modeling (Star Schema, Snowflake Schema)
- DAX, Power Query (M language)
- Experience in designing and implementing BI architecture at scale
- Strong understanding of data warehousing concepts and ETL processes
- Experience working within a Center of Excellence (CoE) model
- Excellent stakeholder management and communication skills
Preferred Skills
- Experience with Azure (Azure Synapse, Data Factory, Data Lake)
- Knowledge of DevOps practices for Power BI (CI/CD pipelines)
- Exposure to governance tools and security frameworks
- Certification in Power BI / Microsoft Data Platform

IMMEDIATE JOINERS ONLY
Key Responsibilities:
1 Data Flow Mapping & Lineage
2 Design and produce end-to-end data flow maps for critical data items – from market source/core systems, through Data Lake staging, zone 2 and consumption zone 3, to downstream reporting, dashboards and analytics use cases.
3 Document data lineage and transformations for critical data elements identified in the Master Data Requirements exercise, ensuring traceability that is audit-defensible and supports regulatory, governance and AI-readiness needs.
4 Map data availability by country/Data Lake against the Product Hierarchy (to profit-centre level), building the consolidated Commercial Data Landscape view of what exists, where it sits (source only, staging, or consumption) and what is not captured at all.
5 Document cross-system dependencies and cross-border data flows, flagging data residency, privacy and regulatory considerations to the appropriate governance forums.
6 Data Inventory, Data Model Alignment & Gap Analysis
• Own and mature the data asset inventory, catalogue and data dictionary aligned to the consolidated Master Data Requirements Template – resolving “Not Specified”, “TBD” and “validation required” availability statuses through structured validation with Market IT and Data Engineering.
• Align business data requirements to the conceptual and logical data model of the target Data Lakehouse, ensuring the dependency between data model design and lineage tracking of critical data items is explicitly documented.
• Perform gap and hydration analysis by market and product, quantifying the scale of data that must be brought into the Data Lakes and providing sizing input to the Data Foundation Lead, DAE architects and Data Engineering delivery plans.
• Contribute to the Data Consolidation Plan towards a single source of truth, including recommended sequencing based on business priority (Top 200 fields, Horizon 1–3 priorities).
• Stakeholder Engagement & Workshops
• Work hand-in-hand with the Data Foundation Lead, Data & Analytics Programme Manager, Data Engineers, DAE/infrastructure architects, Local Market IT and Business stakeholders (Regional and Market) as the connective tissue between business data needs and technical implementation.
• Plan and facilitate structured interviews and cross-functional validation workshops with business, technology and data stakeholders to corroborate actual operating data flows against documented processes – establishing a fact-based, evidence-backed view rather than relying on documentation alone.
• Translate ambiguous business asks into clear data definitions, mapping rules and acceptance criteria that Data Engineering can build against, and play back findings to senior stakeholders in clear, visual, decision-oriented formats.
• Manage competing priorities across multiple markets with tact, keeping momentum in an environment of constrained capacity and differing local system landscapes.
• Governance, Ownership & Documentation
• Produce and maintain the Data Ownership & Accountability Matrix – mapping data owners, stewards and custodians per data asset and highlighting ownership gaps for remediation.
• Classify data assets by sensitivity and business function, aligning to Data Protection Policy, PDPA and applicable regulatory expectations (e.g. MAS guidelines) in partnership with Risk & Compliance.
• Ensure all data flow maps, lineage records and inventory artefacts are version-controlled, audit-ready and handed over cleanly into BAU data governance processes.
• Produce source to Datalake mapping document and data catalogue for missing data elements to complete Datalake hydration
Key Skills
• Data flow mapping and lineage documentation – proven ability to draw clear, accurate source-to-consumption data flow maps across complex multi-system, multi-market landscapes.
• Data architecture and modelling – strong grasp of conceptual/logical data models, data lake/lakehouse zone architectures (staging, conformed, consumption), data marts and MDM concepts.
• Data inventory, catalogue, dictionary and metadata management; familiarity with lineage/catalogue tooling (e.g. Purview, Collibra) and diagramming tools (e.g. Visio, ErWin, Lucidchart).
• Hands-on data profiling and validation skills (SQL essential) to verify what actually exists in source systems and lake zones.
• Strong stakeholder management – this is critical: able to build trust and drive outcomes across regional leadership, market business teams, Market IT and engineering, and to facilitate effective cross-functional workshops.
• Insurance domain knowledge – ideally commercial and specialty lines, with an understanding of policy, claims, reinsurance and underwriting data.
• Data quality, governance and privacy concepts, including cross-border data considerations.
• Clear written and visual communication – able to make complex data landscapes understandable to executives.
Experience & Qualification Requirements:
• 8+ years’ experience in data architecture, data business analysis or information architecture roles, with at least:
• 3+ years documenting data flows, lineage or data landscapes across multi-system / multi-market environments.
• Experience in Insurance or Financial Services, ideally within data foundation, data lake or data governance programmes.
• Demonstrated delivery of data inventory / data mapping / current-state data landscape assessments involving both business and IT stakeholders.
• Relevant certification (e.g. DAMA CDMP, TOGAF, cloud data platform certifications) preferred.


Solution Architect – AZURE Data Engineering
Job Overview
We are looking for an experienced Solution Architect – Data Engineering with strong expertise in designing data solutions and hands-on experience with Azure, Synapse, PySpark, Data Warehousing, and Data Lakes. The ideal candidate should have strong architectural and data engineering knowledge.
Key Responsibilities
- Design and implement scalable data architecture and solutions.
- Develop and manage Data Warehouse and Data Lake architectures.
- Design data platforms using Medallion Architecture.
- Lead Data Engineering and ETL activities.
- Work with Azure Synapse Analytics for data processing and analytics.
- Develop data solutions using PySpark / Apache Spark.
- Define and implement data validation and data quality processes.
- Collaborate with business, data, and technology teams to deliver effective data solutions.
Required Skills
- Strong experience in Solution Architecture / Data Architecture.
- Strong knowledge of Data Warehouse and Data Lake architecture.
- Good understanding of Medallion Architecture.
- Strong experience in Data Engineering and ETL.
- Hands-on experience with Microsoft Azure and Azure Synapse Analytics.
- Strong knowledge of PySpark / Apache Spark.
- Experience with Data Validation and Data Quality.
- Good communication and stakeholder management skills.
Experience
8+ Years

 Python
Job Description:
Experience: 10+ Years
Job Summary
We are looking for an experienced Azure Fabric Data Architect to lead the design and implementation of an enterprise data platform on Microsoft Fabric. The role involves architecting scalable data solutions, defining data governance, and enabling AI-driven analytics for a global financial services client.
Key Responsibilities
- Design end-to-end data architecture using Microsoft Fabric.
- Build enterprise Lakehouse, Data Warehouse, and OneLake solutions.
- Define data ingestion, ETL/ELT, governance, security, and performance strategies.
- Lead architecture for AI-powered analytics, AI Agents, and enterprise chatbots using Azure AI services.
- Work with business stakeholders to translate requirements into technical solutions.
- Mentor engineering teams and provide technical leadership.
Required Skills
- Microsoft Fabric (Data Factory, Lakehouse, Data Warehouse, OneLake)
- Azure Data Engineering
- Power BI
- Azure AI Services / Azure OpenAI
- Data Architecture & Data Modeling
- SQL, Python
- Azure DevOps, CI/CD
- Strong stakeholder management and solution design experience
Preferred: Experience in Capital Markets or Financial Services and Microsoft Azure/Fabric certifications.
NOTE: One technical round is mandatory to be taken F2F from office.

Technical Lead
Job Description
Role Overview
We are seeking a highly skilled Data Engineering Lead with minimum of 5 years of hands-on experience in Azure data engineering, data warehousing, and automation-driven integration. The ideal candidate should be a proven technical lead, capable of driving end-to-end
project delivery and working closely with customer teams. This is a Work from Office / Customer Site role.
Roles and Responsibilities
• Lead the design, development, and delivery of data engineering and automation projects.
• Architect and implement ETL/ELT pipelines using Azure Data Factory.
• Design and manage enterprise data warehouses including dimensional modeling and
schema optimization.
• Manage Azure components including Storage Accounts, Data Lakes, Azure SQL, and Synapse.
• Drive automation initiatives across data ingestion and transformation workflows.
• Collaborate with business and technical stakeholders to translate requirements into scalable solutions.
• Mentor team members and enforce engineering best practices.
• Serve as the technical anchor responsible for ensuring high-quality, on-time delivery.
Skills and Qualification
• Strong hands-on experience with Azure Data Factory, Azure Storage, Azure SQL/Synapse.
• Deep understanding of data warehousing concepts: star/snowflake schemas, fact/dimension modeling.
• Experience with automation-led data engineering solutions.
• Strong troubleshooting, optimization, and analytical skills.
• Excellent communication and stakeholder management abilities.
• Proven experience as a Technical Lead leading teams and delivery.
Must Have
• Min of 5 years of relevant data engineering experience.
• Strong Azure Data Engineering and Data Warehousing expertise.
• Proven Technical Lead experience.
• Ability to work from office and customer site.
• Strong ownership mindset with a focus on quality and delivery excellence.
Years of Exp: 5 to 8 Years (Relevant 5+ Years)
Location: Hyderabad
Notice Period: Immediate to 20 days
Offshore: Data Governance Analyst
Position Summary
Execute day-to-day Data Governance activities for RTB initiatives under the direction of the Onshore Lead. The role will focus on producing accurate, complete, and traceable governance artifacts that support enterprise standards, control requirements, and audit readiness.
Key Responsibilities
Register and maintain data assets, reports, and data products in Collibra and Data Marketplace.
Capture and validate business, technical, and operational metadata.
Document end-to-end data lineage, including sources, targets, transformations, and data movement.
Support business glossary, data classification, ownership, stewardship, and authoritative source documentation.
Assist with data quality rule documentation, issue tracking, and remediation follow-up.
Coordinate with data owners, engineers, architects, and application teams to resolve documentation gaps.
Maintain governance evidence, decisions, status reports, and action items.
Track work through Jira and escalate blockers promptly to the Onshore Lead.
Support multiple RTB workstreams while meeting established quality and delivery expectations.
Required Qualifications
Experience in Data Governance, Data Management, metadata management, lineage, or data quality.
Working knowledge of Collibra or a comparable governance platform.
Understanding of data warehousing, data modeling, ETL/data pipelines, and system-to-system data flows.
SQL proficiency and familiarity with cloud data platforms, preferably Snowflake.
Strong analytical, documentation, communication, and organizational skills.
Ability to work effectively in an onshore-offshore delivery model.
Preferred Qualifications
Experience with Collibra or similar Data Governance Platforms, Jira, Confluence, Cloud Data Solutions, Excel
Financial-services or regulated-industry experience.
Familiarity with Agile delivery and audit or regulatory documentation.
 Amazon Web Services (AWS)
Position: Technical Architect – Data Engineering
Job Summary:
- We are looking for an experienced Technical Architect to lead the design and implementation of modern cloud-based data platforms.
- The ideal candidate should have strong expertise in Azure and/or AWS, Databricks, Snowflake, modern data architecture, and large-scale data engineering.
- The candidate will work closely with business stakeholders, architects, and engineering teams to deliver scalable, secure, and high-performance data solutions.
Key Responsibilities
• Design enterprise-scale data lakehouse and data warehouse architectures.
• Define data ingestion, transformation, and serving architecture.
• Lead architecture discussions and technical governance.
• Design scalable ETL/ELT frameworks using Databricks and Snowflake.
• Define best practices for security, performance, CI/CD, and DevOps.
• Guide engineering teams on implementation.
• Collaborate with business, product, and data governance teams.
Must Have Skills :
• Azure or AWS
• Databricks
• Snowflake
• Data Lakehouse Architecture
• PySpark
• SQL
• Data Modelling
• ETL/ELT Architecture
• Performance Optimization
• CI/CD
• Terraform or Infrastructure as Code (preferred)
Preferred
• Insurance domain
• dbt
• Unity Catalog
• Delta Lake
• Iceberg
• Azure Data Factory / AWS Glue
 Python
Mandatory Skills (Must Have)
• SQL and Database Design (5+ years in enterprise data platforms)
• Python development for automation and platform services (5+ years)
• Linux administration and Shell Scripting in production environments
• Metadata-driven systems and data management platform experience
• Technical leadership of offshore or distributed development teams Wissen Technology
• System analysis, troubleshooting, and production support expertise
• Metadata onboarding, integration, and governance processes
• Stakeholder management and delivery ownership across multiple teams
Key Responsibilities
• Lead developers supporting the Pantheon Metadata platform and related services
• Own end-to-end delivery of metadata onboarding and enhancement initiatives
• Design scalable metadata management solutions and automation capabilities
• Collaborate with architecture, infrastructure, and application teams for enterprise integration
• Participate in solution design reviews and establish development best practices
• Prioritize enhancements with business stakeholders and manage delivery commitments
• Provide production support, troubleshooting, and platform stability improvements Wissen Technology
• Drive modernization initiatives related to metadata lifecycle management
PythonAmazon Web Services (AWS)Sr. Data Engineer
Location: Pune
Responsibilities
· Lead the end-to-end design and development of scalable, high-performance data pipelines and ETL/ELT frameworks aligned with modern data engineering best practices.
· Architect complex data integration workflows that bring together structured, semi-structured, and unstructured data from both cloud and on-premise sources.
· Build robust real-time, batch, and on-demand pipelines with built-in observability—monitoring, alerting, and automated error handling.
· Partner with analysts, data scientists, and business leaders to define and deliver reliable data models, quality frameworks, and SLAs that power key business insights.
· Ensure optimal pipeline performance and throughput, with clearly defined SLAs and proactive alerting for data delivery or quality issues.
· Collaborate with platform, DevOps, and architecture teams to build secure, reusable, and CI/CD-enabled data workflows that align with enterprise architecture standards.
· Establish and enforce the best practices in source control, code reviews, testing automation, and continuous delivery for all data engineering components.
· Lead root cause analysis (RCA) and preventive maintenance for critical data failures, ensuring minimal business impact and continuous service improvement.
· Guide the team in establishing standards for data modeling, transformation logic, and governance, ensuring long-term maintainability and scalability.
· Design and execute comprehensive testing strategies—unit, integration, and system testing—ensuring high data reliability and pipeline resilience.
· Monitor and fine-tune data pipeline and query performance, optimizing for reliability, scalability, and cost-efficiency.
· Create and maintain detailed technical documentation, including data architecture diagrams, process flows, and integration specifications for internal and external stakeholders.
· Facilitate and lead discussions with business and operational teams to understand data requirements, prioritize initiatives, and drive data strategy forward.
Qualifications
· 7 to 10 years of hands-on experience in data engineering roles with a proven record of building scalable and secure data platforms.
· Over 5 years of experience in scripting languages such as Python for data processing, automation, and ETL development.
· 4+ years of experience with Snowflake, including performance tuning, security model design, and advanced SQL development.
· 5+ years of experience with data integration tools such as Azure Data Factory, Fivetran, or Matillion.
· 5+ years of experience in writing complex, highly optimized SQL queries on large datasets.
· Proven experience integrating and managing APIs, JSON, XML, and webhooks for data acquisition.
· Hands-on experience with cloud platforms (Azure/AWS) and orchestration tools like Apache Airflow or equivalent.
· Experience with CI/CD pipelines, automated testing, and code versioning tools (e.g., Git).
· Familiarity with dbt or similar transformation tools and best practices for modular transformation development.
· Exposure to data visualization tools like Power BI for supporting downstream analytics is a plus.
· Strong interpersonal and communication skills with the ability to lead discussions with technical and business stakeholders.
Education
Bachelor’s or Master’s degree in Computer Science/Information technology or related field.
Equivalent academic and work experience can be considered.













 Follow Cutshort
Shubham Vishwakarma
Full Stack Developer - Averlon