
Site Reliability Engineer - Devops at CodeCraft Technologies Private Limited · Bengaluru (Bangalore), Mangalore · 7 - 12 years · Profitable · Posted 9 Feb 2024

Site Reliability Engineer - Devops
 GitHub
Position: SRE/ DevOps
Experience: 6-10 Years
Location: Bengaluru/Mangalore
CodeCraft Technologies is a multi-award-winning creative engineering company offering design and technology solutions on mobile, web and cloud platforms.
We are seeking a highly skilled and motivated Site Reliability Engineer (SRE) to join our dynamic team. As an SRE, you will play a crucial role in ensuring the reliability, availability, and performance of our systems and applications. You will work closely with the development team to build and maintain scalable infrastructure, implement best practices in CI/CD, and contribute to the overall stability of our technology stack.
Roles and Responsibilities:
· CI/CD and DevOps:
o Implement and maintain robust Continuous Integration/Continuous Deployment (CI/CD) pipelines to ensure efficient and reliable software delivery.
o Collaborate with development teams to integrate DevOps principles into the software development lifecycle.
o Experience with pipelines such as Github actions, GitLab, Azure DevOps,CircleCI is a plus.
· Test Automation:
o Develop and maintain automated testing frameworks to validate system functionality, performance, and reliability.
o Collaborate with QA teams to enhance test coverage and improve overall testing efficiency.
· Logging/Monitoring:
o Design, implement, and manage logging and monitoring solutions to proactively identify and address potential issues.
o Respond to incidents and alerts to ensure system uptime and performance.
· Infrastructure as Code (IaC):
o Utilize Terraform (or other tools) to define and manage infrastructure as code, ensuring scalability, security, and consistency across environments.
· Elastic Stack:
o Implement and manage Elastic Stack (ELK) for log and data analysis to gain insights into system performance and troubleshoot issues effectively.
· Cloud Platforms:
o Work with cloud platforms such as AWS, GCP, and Azure to deploy and manage scalable and resilient infrastructure.
o Optimize cloud resources for cost efficiency and performance.
· Vulnerability Management:
o Conduct regular vulnerability assessments and implement measures to address and remediate identified vulnerabilities.
o Collaborate with security teams to ensure a robust security posture.
· Security Assessment:
o Perform security assessments and audits to identify and address potential security risks.
o Implement security best practices and stay current with industry trends and emerging threats.
o Experience with tools such as GCP Security Command Center, and AWS Security Hub is a plus.
· Third-Party Hardware Providers:
o Collaborate with third-party hardware providers to integrate and support hardware components within the infrastructure.
Desired Profile:
· The candidate should be willing to work in the EST time zone, i.e. from 6 PM to 2 AM.
· Excellent communication and interpersonal skills
· Bachelor’s Degree
· Certifications related to this field shall be an added advantage.


Shubham Vishwakarma
Full Stack Developer - Averlon


About CodeCraft Technologies Private Limited
About
CodeCraft Technologies is a digital transformation company offering mobility & cloud solutions along with design and consultancy services
With Codecraft you get a chance to work on cutting edge Technololgies.
You will be working on challenging projects into Cyber Security, IOT and Energy Domains
We have open and transparent work culture.
You will be working with one of the finest design teams
Company video

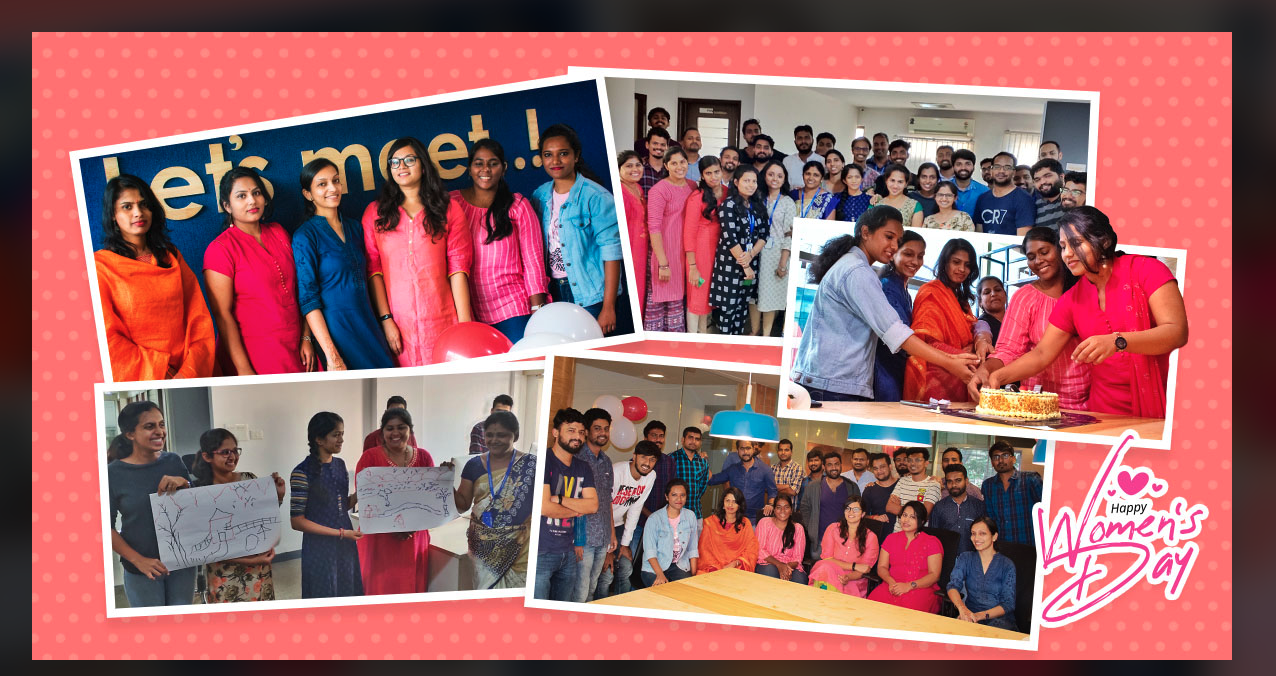
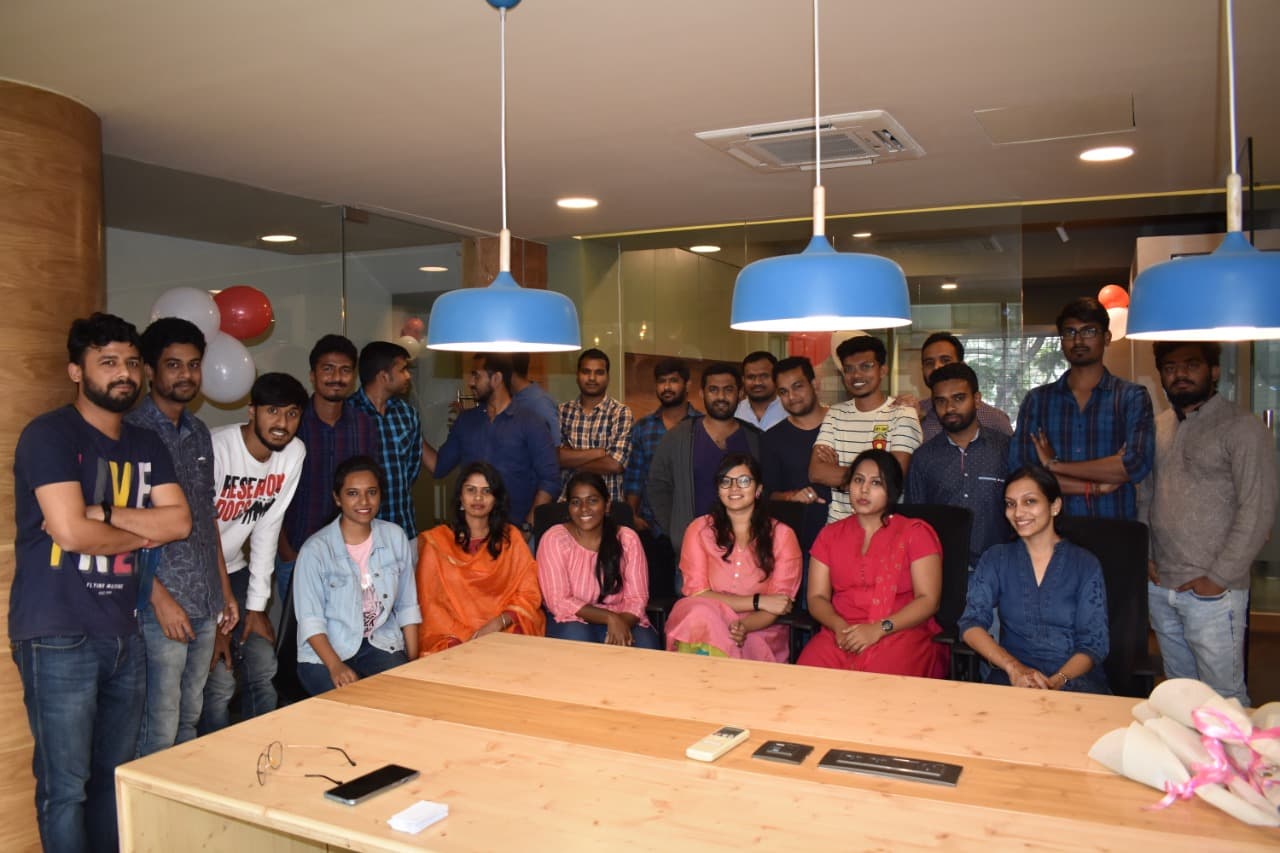
Photos

Company social profiles


Similar jobs (10)

 Docker
 Kubernetes
Key Responsibilities
- Automate application deployments from Bitbucket to servers using CI/CD pipelines.
- Design and manage scalable, highly available AWS infrastructure.
- Implement Auto Scaling, ELB, and Route 53 for traffic management and high availability.
- Work with AWS services including IAM, RDS, DynamoDB, EC2, and other cloud services.
- Build and manage Docker containers and server images.
- Deploy and manage applications using Kubernetes.
- Implement Infrastructure as Code using Terraform, CloudFormation, or Ansible.
- Develop automation scripts using Python and Bash.
- Implement monitoring and logging using tools such as Prometheus, Grafana, and ELK.
- Integrate security and compliance practices into CI/CD pipelines.
- Optimize infrastructure for security, scalability, performance, and cost.
Required Skills
- 3+ years of experience in DevOps or a similar role.
- Strong knowledge of AWS beyond EC2.
- Hands-on experience with Jenkins or similar CI/CD tools.
- Experience with Docker and Kubernetes.
- Good understanding of Terraform/IaC and automation.
- Proficiency in Python and/or Bash scripting.
- Knowledge of DevSecOps, security, and compliance best practices.
- Strong troubleshooting and problem-solving skills.


Job Title : DevOps Engineer – Linux, AWS & Infrastructure
Experience : 3+ Years
Location : Sector 48, Gurgaon
Work Mode : 6 Days WFO – Monday to Saturday
Week Off : 01st & 03rd Saturday Off
Employment Type : Full-Time
Job Summary :
We are looking for a DevOps Engineer with strong hands-on experience in Linux, Networking, Server Administration, AWS, CI/CD, Containers, Kubernetes, and Infrastructure Automation. The ideal candidate should have strong troubleshooting skills, production ownership, and the ability to manage and automate infrastructure reliably.
Key Responsibilities :
- Manage and troubleshoot Linux servers, bare-metal infrastructure, and server environments.
- Perform system administration, networking, performance monitoring, and production troubleshooting.
- Design, maintain, and optimize Jenkins-based CI/CD pipelines and deployment workflows.
- Manage Docker containers and Kubernetes environments.
- Work with AWS Cloud services, infrastructure, security, and deployment environments.
- Monitor system health, application performance, logs, and infrastructure using appropriate monitoring and logging tools.
- Implement and maintain Infrastructure as Code (IaC) using tools such as Terraform or CloudFormation.
- Automate repetitive operational tasks using Python, Bash, Shell scripting, or similar technologies.
- Implement infrastructure and application security, access controls, patching, and hardening.
- Investigate production incidents, perform root-cause analysis (RCA), and drive issues to resolution.
- Take end-to-end ownership of infrastructure reliability, availability, and operational issues.
- Collaborate with development and other engineering teams to improve deployment, scalability, and system reliability.
Mandatory Skills :
Linux & Networking | Bare Metal / Server Administration | Jenkins / CI-CD | Docker / Containers | AWS Cloud | Kubernetes | Git | Monitoring & Logging | Security | Infrastructure as Code (IaC) | Automation / Scripting | Production Troubleshooting & Ownership
Preferred Skills :
- Strong understanding of TCP/IP, DNS, HTTP/HTTPS, SSH, load balancing, and networking fundamentals.
- Hands-on experience with Terraform / CloudFormation.
- Experience with Prometheus, Grafana, ELK / EFK, CloudWatch, or similar monitoring / logging tools.
- Good understanding of Linux performance troubleshooting, processes, memory, disk, networking, and file systems.
- Experience handling production incidents, RCA, deployments, and system reliability.
- Exposure to cloud security, IAM, secrets management, and server hardening.
What We’re Looking For :
- 3+ years of hands-on experience in DevOps / SRE / Infrastructure Engineering.
- Strong practical knowledge rather than certification-based/theoretical understanding.
- Good troubleshooting and analytical skills.
- Strong sense of ownership and accountability for production systems.
- Comfortable working in a 6-day work-from-office environment.

 DockerKubernetes
 Amazon Web Services (AWS)
We are seeking a highly skilled and experienced DevOps Engineer to join our development team.
Years of experience needed: 8+ Yrs
Required Skills
Strong experience with GitLab, TeamCity, Terraform, Kubernetes and Docker
Proficiency in various deployment strategies and CI/CD pipeline setups
Solid understanding of Linux administration and Windows IIS.
Advanced scripting skills in bash and PowerShell
Hands-on experience with Google Cloud Platform (GCP) services, particularly GKE, GCS, GCE, Cloud SQL, and load balancers
Familiarity with Autosys for job scheduling and automation
Excellent problem-solving and troubleshooting skills
Ability to work independently and collaboratively in a fast-paced environment
- • Strong communication and interpersonal skills.

The recruiter has not been active on this job recently. You may apply but please expect a delayed response.
Amazon Web Services (AWS)Job Title: DevOps Manager
Experience: 8+ Years
Location: Pune
Employment Type: Full-time
About the Role
We are looking for an experienced DevOps Manager with strong hands-on technical expertise and leadership capabilities to manage cloud infrastructure, automation, CI/CD, deployments, and platform reliability. The ideal candidate should have strong experience in Shell Scripting, cloud platforms, Kubernetes, Terraform, and production DevOps environments.
Key Responsibilities
• Lead and mentor the DevOps engineering team.
• Design, implement, and optimize CI/CD pipelines and deployment processes.
• Manage scalable and highly available cloud infrastructure across AWS / Azure / GCP.
• Drive Infrastructure as Code (IaC) using Terraform and configuration automation using Ansible.
• Manage Docker and Kubernetes based environments.
• Develop and maintain automation scripts using Shell/Bash Scripting and Python.
• Implement monitoring, logging, alerting, and observability.
• Handle production incidents, troubleshooting, root cause analysis, and preventive actions.
• Drive infrastructure security, performance, scalability, and cloud cost optimization.
• Collaborate with Development, QA, Security, Architecture, and Delivery teams.
Required Skills & Qualifications
• 8+ years of experience in DevOps, Cloud Engineering, Platform Engineering, or related roles.
• Strong hands-on experience in Shell / Bash Scripting.
• Experience with AWS / Azure / GCP cloud platforms.
• Strong knowledge of CI/CD tools such as Jenkins, GitHub Actions, GitLab CI/CD, or Azure DevOps.
• Hands-on experience with Docker, Kubernetes, and Helm.
• Strong experience with Terraform and Ansible.
• Experience with Linux administration, Git, networking, IAM, and cloud security.
• Experience with monitoring tools such as Prometheus, Grafana, ELK, or equivalent.
• Strong troubleshooting, communication, stakeholder management, and team leadership skills.
Preferred Skills (Nice to Have)
• Python scripting experience.
• Cloud / Kubernetes / Terraform certifications.
• Experience with SRE, observability, high-availability architecture, and cloud cost optimization.
Amazon Web Services (AWS)Job Title : DevOps Engineer / Site Reliability Engineer (SRE)
Experience : 5+ Years
Location : Gurugram, Haryana
Work Mode : On-site (Full-time)
About the Role :
We are looking for a skilled DevOps Engineer with 5+ years of experience in cloud infrastructure, CI/CD, automation, Kubernetes, and Site Reliability Engineering (SRE). The ideal candidate will be responsible for building scalable cloud infrastructure, automating deployments, improving system reliability, and ensuring high availability across production environments.
Mandatory Skills :
AWS, Terraform, Ansible, CloudFormation, Jenkins, GitLab CI, GitHub Actions, Docker, Kubernetes, Helm, Python, Bash, Grafana, Prometheus, ELK Stack, CloudWatch, New Relic, SRE, CI/CD, Infrastructure as Code (IaC), Linux
Key Responsibilities :
- Design, deploy, and manage cloud infrastructure primarily on AWS (EC2, VPC, IAM, S3, RDS, Route53, ALB, Auto Scaling, Lambda).
- Build and maintain Infrastructure as Code (IaC) using Terraform, Ansible, and CloudFormation.
- Develop and optimize CI/CD pipelines using Jenkins, GitLab CI, and GitHub Actions.
- Deploy and manage containerized applications using Docker, Kubernetes, and Helm.
- Implement monitoring and observability using Grafana, Prometheus, ELK Stack, CloudWatch, and New Relic.
- Drive SRE practices by defining SLIs, SLOs, SLAs, handling production incidents, conducting RCA, and improving system reliability.
- Automate operational tasks using Python, Bash, and Groovy scripting.
- Collaborate with Development, QA, Security, and Operations teams to ensure reliable and secure software delivery.
Required Skills & Qualifications :
- Bachelor's degree in Computer Science, IT, Electronics, or a related field.
- 5+ years of experience in DevOps, SRE, or Cloud Infrastructure.
- Strong expertise in AWS, with exposure to Azure/GCP.
- Hands-on experience with Terraform, Ansible, CloudFormation, Docker, Kubernetes, Helm, Jenkins, GitLab CI, GitHub Actions, and Git.
- Strong scripting skills in Python and Bash.
- Experience with monitoring tools such as Grafana, Prometheus, ELK Stack, CloudWatch, and New Relic.
- Good understanding of Linux, networking, SQL, and cloud security best practices.
Preferred Skills :
- Experience with multi-cloud environments and DevSecOps practices.
- Knowledge of disaster recovery, automation, and microservices architecture.
- Strong troubleshooting, communication, and problem-solving skills.
 Amazon Web Services (AWS)Docker
 Python
Company Overview:
Planview is hiring a DevOps Engineer in Bengaluru, India to support Planview SaaS applications across the product line. You will work in a global, collaborative team — owning CI/CD pipelines, cloud infrastructure, and automation to keep deployments fast and systems reliable.
Responsibilities
- Build and maintain CI/CD pipelines in Jenkins for reliable, fast delivery.
- Manage containerized workloads on Docker and ECS — task definitions, services, and clusters.
- Provision and manage AWS infrastructure using Terraform (CloudFormation a plus).
- Automate configuration and deployment tasks using Python (Ansible a plus).
- Set up and maintain monitoring and alerting via New Relic (CloudWatch, Datadog, or Prometheus/Grafana a plus).
- Write Shell and Python scripts to automate operations and reduce manual work.
- Manage Git workflows — branching, merge strategies, and pull request reviews.
- Administer and support MSSQL databases underpinning the product line — backups, restores, and basic performance troubleshooting.
- Troubleshoot deployment, performance, and infrastructure issues with development teams.
- Participate in on-call rotations and drive incident response.
- Continuously improve infrastructure resilience and deployment speed.
- Apply AI-assisted engineering tools (e.g., GitHub Copilot, Claude Code) to speed up IaC authoring, pipeline debugging, and day-to-day scripting.
Qualifications
Must-Have Skills
- Experience: 4–6 years of experience in DevOps, SRE, or Infrastructure Engineering.
- OS: Windows administration (systemd, package management, log analysis).
- Cloud: AWS (Active Directory, ECS, EC2, CloudFront, S3, VPC, IAM, RDS, Lambda basics).
- Source Control: Git — branching, merge/rebase, PR reviews.
- CI/CD (Jenkins): Pipeline creation and basic Groovy scripting.
- Containerization (Docker + ECS): Task definitions, services, and clusters.
- IaC: Terraform.
- Monitoring: New Relic.
- Scripting: Bash and Python scripting for automation.
- Networking Basics: DNS, load balancers, security groups, VPNs.
- Logging: ELK stack / CloudWatch Logs.
- Database: MSSQL administration — backups, restores, basic performance troubleshooting.
- Infrastructure Automation: Hands-on experience automating infrastructure provisioning, configuration, and deployment end-to-end.
- AI-Assisted Engineering: Comfortable working with AI coding/DevOps assistants (e.g., GitHub Copilot, Claude Code) for IaC generation, scripting, and troubleshooting — verified via a mandatory AI proficiency assessment during interviews.
Nice-to-Have Skills
• Configuration Management: Ansible.
• Additional IaC: CloudFormation.
• Architecture: Knowledge of microservices architecture.
• Cloudflare: DNS, CDN, WAF.
• Artifact Repositories: Nexus, JFrog Artifactory, ECR.
• Other CI/CD Tools: GitHub Actions.
• AWS cost optimization / FinOps awareness.
• Datadog, CloudWatch, or Prometheus/Grafana.
• AIOps: Exposure to AI-driven anomaly detection, root-cause analysis, or incident triage (e.g., Dynatrace Davis AI, Datadog Bits AI, Harness AIDA).
• Database Basics: RDS backups, restores, performance tuning.
KubernetesJob Title : DevOps Engineer
Experience : 7+ Years
Working Hours : 3:30 AM – 11:30 AM ET
Duration : 12–18 Months
Engagement : Contract
Freelance : Not Applicable
BGV : Required
Role Overview :
We are looking for an experienced DevOps Engineer to design, implement, and optimize DevOps practices, CI/CD pipelines, deployment automation, and cloud-native delivery platforms. The role will focus on enabling secure, reliable, and efficient software delivery while improving infrastructure automation, release processes, platform reliability, and operational resilience.
Mandatory Skills :
DevOps, CI/CD, Azure DevOps / GitHub Actions, Kubernetes, Docker, PowerShell / Python / Bash, Automation, Monitoring & Observability, DevSecOps, IaC, Troubleshooting, and Production Support.
Key Responsibilities :
- Design, build, and maintain CI/CD pipelines for enterprise application delivery and release management.
- Develop deployment automation frameworks to improve release quality, consistency, scalability, and efficiency.
- Administer Kubernetes and containerized environments and supporting orchestration platforms.
- Improve build, test, deployment, and release workflows for development teams.
- Integrate automated testing, security scanning, validation, and compliance controls into CI/CD pipelines.
- Implement monitoring, logging, alerting, and observability solutions for platform and application environments.
- Troubleshoot deployment failures, production issues, and platform incidents; perform root cause analysis.
- Develop automation scripts and tools using PowerShell, Python, Bash, or similar technologies.
- Implement Infrastructure as Code and automation practices to reduce manual effort and operational risk.
- Collaborate with Cloud, Infrastructure, Security, and Application teams to deliver scalable and resilient solutions.
- Maintain deployment standards, release procedures, technical documentation, and operational runbooks.
- Apply DevOps, DevSecOps, and SRE best practices to improve delivery speed and platform reliability.
- Evaluate emerging DevOps technologies and recommend improvements.
- Mentor team members on DevOps methodologies, automation, and platform engineering practices.
- Act as an escalation point for critical deployment, infrastructure, and platform issues.
Required Technical Skills :
1. DevOps & CI/CD :
- 7+ years of experience in DevOps, Platform Engineering, Infrastructure Engineering, or Software Engineering.
- Strong experience designing and supporting CI/CD pipelines and release management.
- Hands-on experience with Azure DevOps, GitHub, GitHub Actions, or equivalent platforms.
- Strong understanding of Git, branching strategies, release management, and deployment methodologies.
2. Containers & Cloud :
- Strong hands-on experience with Kubernetes and Docker/containerization.
- Understanding of cloud-native application architectures and distributed systems.
- Experience supporting production-grade containerized environments.
3. Automation & IaC :
- Strong proficiency in PowerShell, Python, Bash, or similar scripting languages.
- Experience developing automation frameworks and deployment tooling.
- Knowledge of Infrastructure as Code (IaC) concepts.
- Experience with Terraform, Bicep, or similar tools is preferred.
4. Monitoring & Reliability :
- Experience with monitoring, logging, observability, and alerting.
- Strong troubleshooting and root cause analysis skills.
- Experience supporting highly available and resilient production systems.
- Knowledge of SRE practices is preferred.
5. Security & DevSecOps :
- Understanding of DevSecOps and secure software delivery practices.
- Experience integrating vulnerability scanning, security controls, and compliance checks into CI/CD pipelines.
- Knowledge of IAM, secrets management, and access control within DevOps environments.
Preferred Qualifications :
- Hands-on experience with Microsoft Azure.
- Experience with Terraform/Bicep or other IaC tools.
- Knowledge of SRE and platform engineering practices.
- Relevant Azure, Kubernetes, Cloud, or DevOps certifications.
Amazon Web Services (AWS)DockerKubernetesJob Title : DevOps Engineer / Site Reliability Engineer (SRE)
Experience : 4+ Years
Location : Gurugram, Sector 48, Haryana (On-site)
Employment Type : Full-Time
Working Days : Monday to Saturday (1st & 3rd Saturday Off)
About the Role :
We are looking for a hands-on DevOps Engineer / Site Reliability Engineer (SRE) with strong experience in Linux, AWS, Kubernetes, Docker, CI/CD, Infrastructure as Code, and production application deployments.
The ideal candidate should have real-world production experience, excellent troubleshooting skills, and the ability to manage both infrastructure and application-level issues.
Mandatory Skills :
Linux, AWS, Docker, Kubernetes, Terraform, Ansible, Jenkins, GitHub Actions, GitLab CI/CD, CI/CD, Infrastructure as Code (IaC), Python, Bash, Git, Grafana, Prometheus, ELK, CloudWatch, New Relic, SRE (SLI/SLO/SLA), Networking (DNS, HTTP/HTTPS, TCP/IP, Load Balancer), Production Application Deployment & Troubleshooting
Key Responsibilities :
- Manage and maintain AWS cloud infrastructure.
- Build and optimize CI/CD pipelines using Jenkins, GitHub Actions, or GitLab CI.
- Deploy, monitor, and troubleshoot applications across production environments.
- Automate infrastructure using Terraform and Ansible.
- Manage Docker containers and Kubernetes clusters.
- Monitor systems using Grafana, Prometheus, ELK, CloudWatch, and New Relic.
- Perform Linux server administration and troubleshooting.
- Handle production incidents, Root Cause Analysis (RCA), and improve system reliability.
- Collaborate with development teams to support application releases and automation.
Required Qualifications :
- Bachelor's degree in Computer Science or related field.
- 4+ years of hands-on experience in DevOps / SRE.
- Strong Linux administration and production troubleshooting skills.
- Experience with AWS and modern DevOps toolchains.
- Hands-on experience with application deployment and production support.
What We're Looking For :
- Strong practical Linux and cloud knowledge.
- Real production experience with application deployments.
- Ability to troubleshoot both infrastructure and application issues.
- Experience handling live production incidents.
- Excellent communication and problem-solving skills.
- Candidates should be comfortable with scenario-based technical discussions and demonstrate genuine hands-on expertise.
Interview Process :
- HR Screening
- Technical Round
- Client Technical Round
- Final Discussion
Note : The interview will focus on practical hands-on experience in Linux, AWS, Kubernetes, Docker, CI/CD, Infrastructure as Code, application deployment, production troubleshooting, and real-world DevOps scenarios.
Amazon Web Services (AWS) Jenkins
As a DevOps Engineer at YOYO, you'll own the infrastructure and delivery backbone that keeps our platform running as we grow. You'll build the CI/CD, cloud infrastructure, and observability that let a small, fast-moving team ship confidently and you'll keep our AI and data workloads reliable and affordable at scale. This is a hands-on role with real ownership: you won't be maintaining someone else's setup, you'll be shaping ours. You'll work closely with the backend, AI/ML, and data teams to make deployment boring, incidents rare, and scaling a non-event.
If you are Interested DM me on LinkedIn - Saquib Mundagnur
What You'll Own
CI/CD & developer experience - Build and maintain fast, reliable CI/CD pipelines so engineers ship multiple times a day with confidence. - Make the path from commit to production simple, safe, and repeatable, with sensible automated testing, rollbacks, and release controls.Cloud infrastructure & IaC - Own our cloud infrastructure (AWS/GCP) end to end, managed as code (Terraform or similar) — no click-ops. - Design for scale and cost-efficiency as store and conversation volumes grow.
Containers & orchestration - Run our services on containers/Kubernetes: deployments, autoscaling, networking, and resource management. - Support the specific needs of AI/ML workloads, including GPU-backed inference and batch processing for the speech pipeline.
Reliability & observability (SRE) - Own uptime, performance, and incident response — monitoring, logging, tracing, alerting, on-call, and blameless postmortems. - Define and defend SLOs; keep the platform dependable as it scales across clients.
Data & pipeline infrastructure - Support the infrastructure behind large-scale, edge-to-cloud data movement and processing (audio ingestion, ASR/AI pipelines, analytics). - Keep data workloads reliable, performant, and cost-aware.
Security & compliance - Bake security into the platform: secrets management, IAM/least-privilege, encryption in transit and at rest, network hardening, and vulnerability management. - Support compliance readiness (including India's DPDP Act and enterprise-client security requirements) for a product that handles sensitive customer conversations.
Cost & scale - Own cloud cost visibility and optimization; make scaling decisions that balance reliability and spend.
What You'll Bring - 6+ years in DevOps, SRE, platform, or infrastructure engineering, running production systems at meaningful scale.
- Strong hands-on experience with a major cloud provider (**AWS or Azure or GCP**) and Infrastructure-as-Code (**Terraform** or equivalent).
- Solid experience with **containers and Kubernetes** in production. - Experience building and owning **CI/CD** pipelines (e.g. GitHub Actions, GitLab CI, Jenkins, Argo, or similar).
- Comfort with a scripting/automation language (Python, Go, or Bash) and a strong automation-first mindset.
- Real experience with **observability** (Prometheus/Grafana, ELK, Datadog, OpenTelemetry, or similar) and running incident response / on-call.
- A security-conscious approach — secrets, IAM, encryption, and least-privilege as defaults. - Startup temperament: ownership, pragmatism, and a bias to automate and ship. - Based in or willing to relocate to Bangalore, and up for an onsite/hybrid, in-person team
 Amazon Web Services (AWS)Kubernetes
Job Summary :
We are looking for a proactive and skilled DevOps Engineer to join our team and play a key role in building, managing, and scaling infrastructure for high-performance systems. The ideal candidate will have hands-on experience with Kubernetes, Docker, Python scripting, cloud platforms, and DevOps practices around CI/CD, monitoring, and incident response.
Key Responsibilities :
- Design, build, and maintain scalable, reliable, and secure infrastructure on cloud platforms such as AWS.
- Implement Infrastructure as Code (IaC) using tools like Terraform, Cloud Formation, or similar.
- Manage Kubernetes clusters, configure namespaces, services, deployments, and auto scaling. CI/CD & Release Management
- Build and optimize CI/CD pipelines for automated testing, building, and deployment of services.
- Collaborate with developers to ensure smooth and frequent deployments to production.
- Manage versioning and rollback strategies for critical deployments.
- Containerization & Orchestration using Kubernetes.
- Containerize applications using Docker, and manage them using Kubernetes.
- Write automation scripts using Python or Shell for infrastructure tasks, monitoring, and deployment flows.
- Develop utilities and tools to enhance operational efficiency and reliability.
- Monitoring & Incident Management
- Analyze system performance and implement infrastructure scaling strategies based on load and usage trends.
- Optimize application and system performance through proactive monitoring and configuration tuning.
Desired Skills and Experience :
- Experience Required - 6+ yrs.
- Hands-on experience on cloud services like AWS, EKS etc.
- Ability to design a good cloud solution.
- Strong Linux troubleshooting, Shell Scripting, Kubernetes, Docker, Ansible, Jenkins Skills.
- Design and implement the CI/CD pipeline following the best industry practices using open-source tools.
- Use knowledge and research to constantly modernize our applications and infrastructure stacks.
- Be a team player and strong problem-solver to work with a diverse team.
- Having good communication skills.













 Follow Cutshort
Shubham Vishwakarma
Full Stack Developer - Averlon