
Data Scientist at Propellor.ai · Remote only · 2 - 5 years · ₹5L - ₹15L / yr · Raised funding · Remote only · Posted 19 Apr 2023

 Python
 Data Science
 Machine Learning (ML)
Job Description: Data Scientist
At Propellor.ai, we derive insights that allow our clients to make scientific decisions. We believe in demanding more from the fields of Mathematics, Computer Science, and Business Logic. Combine these and we show our clients a 360-degree view of their business. In this role, the Data Scientist will be expected to work on Procurement problems along with a team-based across the globe.
We are a Remote-First Company.
Read more about us here: https://www.propellor.ai/consulting" target="_blank">https://www.propellor.ai/consulting
What will help you be successful in this role
- Articulate
- High Energy
- Passion to learn
- High sense of ownership
- Ability to work in a fast-paced and deadline-driven environment
- Loves technology
- Highly skilled at Data Interpretation
- Problem solver
- Ability to narrate the story to the business stakeholders
- Generate insights and the ability to turn them into actions and decisions
Skills to work in a challenging, complex project environment
- Need you to be naturally curious and have a passion for understanding consumer behavior
- A high level of motivation, passion, and high sense of ownership
- Excellent communication skills needed to manage an incredibly diverse slate of work, clients, and team personalities
- Flexibility to work on multiple projects and deadline-driven fast-paced environment
- Ability to work in ambiguity and manage the chaos
Key Responsibilities
- Analyze data to unlock insights: Ability to identify relevant insights and actions from data. Use regression, cluster analysis, time series, etc. to explore relationships and trends in response to stakeholder questions and business challenges.
- Bring in experience for AI and ML: Bring in Industry experience and apply the same to build efficient and optimal Machine Learning solutions.
- Exploratory Data Analysis (EDA) and Generate Insights: Analyse internal and external datasets using analytical techniques, tools, and visualization methods. Ensure pre-processing/cleansing of data and evaluate data points across the enterprise landscape and/or external data points that can be leveraged in machine learning models to generate insights.
- DS and ML Model Identification and Training: Identity, test, and train machine learning models that need to be leveraged for business use cases. Evaluate models based on interpretability, performance, and accuracy as required. Experiment and identify features from datasets that will help influence model outputs. Determine what models will need to be deployed, data points that need to be fed into models, and aid in the deployment and maintenance of models.
Technical Skills
An enthusiastic individual with the following skills. Please do not hesitate to apply if you do not match all of them. We are open to promising candidates who are passionate about their work, fast learners and are team players.
- Strong experience with machine learning and AI including regression, forecasting, time series, cluster analysis, classification, Image recognition, NLP, Text Analytics and Computer Vision.
- Strong experience with advanced analytics tools for Object-oriented/object function scripting using languages such as Python, or similar.
- Strong experience with popular database programming languages including SQL.
- Strong experience in Spark/Pyspark
- Experience in working in Databricks
What are the company benefits you get, when you join us as?
- Permanent Work from Home Opportunity
- Opportunity to work with Business Decision Makers and an internationally based team
- The work environment that offers limitless learning
- A culture void of any bureaucracy, hierarchy
- A culture of being open, direct, and with mutual respect
- A fun, high-caliber team that trusts you and provides the support and mentorship to help you grow
- The opportunity to work on high-impact business problems that are already defining the future of Marketing and improving real lives
To know more about how we work: https://bit.ly/3Oy6WlE" target="_blank">https://bit.ly/3Oy6WlE
Whom will you work with?
You will closely work with other Senior Data Scientists and Data Engineers.
Immediate to 15-day Joiners will be preferred.


Shubham Vishwakarma
Full Stack Developer - Averlon


About Propellor.ai
About
Who we are
At Propellor, we are passionate about solving Data Unification challenges faced by our clients. We build solutions using the latest tech stack. We believe all solutions lie in the congruence of Business, Technology, and Data Science. Combining the 3, our team of young Data professionals solves some real-world problems. Here's what we live by:
Skin in the game
We believe that Individual and Collective success orientations both propel us ahead.
Cross Fertility
Borrowing from and building on one another’s varied perspectives means we are always viewing business problems with a fresh lens.
Sub 25's
A bunch of young turks, who keep our explorer mindset alive and kicking.
Future-proofing
Keeping an eye ahead, we are upskilling constantly, staying relevant at any given point in time.
Tech Agile
Tech changes quickly. Whatever your stack, we adapt speedily and easily.
If you are evaluating us to be your next employer, we urge you to read more about our team and culture here: https://bit.ly/3ExSNA2. We assure you, it's worth a read!
Tech stack
PythonMachine Learning (ML)Company video

Candid answers by the company
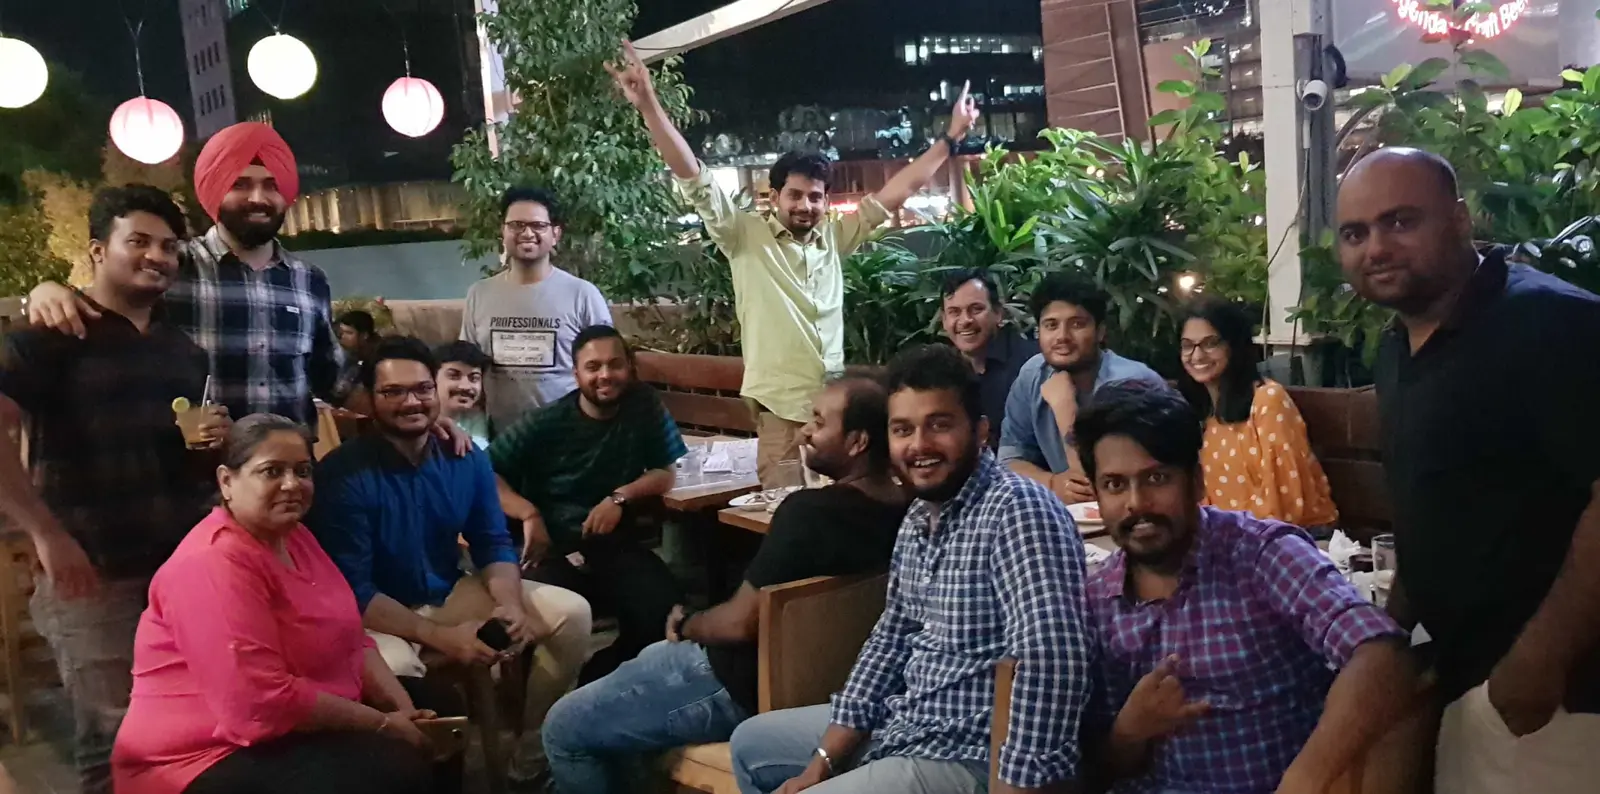
Photos



Company social profiles


Similar jobs (10)
 Machine Learning (ML)PythonData Science
Sr.Data Scientist,Python, AI ML
We are looking for a skilled Data Scientist to analyze complex datasets, develop predictive models, and generate actionable insights that support business decisions. The ideal candidate should have strong statistical, analytical, and programming skills, along with hands-on experience in machine learning.
 PythonData Science
Hiring for Data Scientist / Senior Data Scientist
Exp : 4 - 12 yrs
Edu : BE/B.tech/MCA
Work Location : Pune
Notice Period : Immediate - 15 days
Skills :
4+ years of experience in data engineering, data science, or related domains.
Hands-on experience with SQL, Python, and distributed data systems.
Knowledge of machine learning techniques and statistical analysis.
Experience with cloud data platforms (Azure Data Factory, AWS Glue, GCP BigQuery).
Familiarity with DevOps practices and CI/CD for data pipelines.
Platforms & Operations Experience (Preferred)
- Experience working with Azure, AWS, or Google Cloud data tools.
Operational experience with data orchestration tools (Airflow, ADF, Glue).
Understanding of Kubernetes, Docker, or containerized environments.
Hands-on experience with data warehousing platforms (Snowflake, Redshift, BigQuery).
Experience in monitoring, logging, and alerting operations for data workflows.

Job Summary:
We are looking for a skilled Data Scientist with strong expertise in demand forecasting, predictive analytics, and emerging Generative AI technologies. The ideal candidate should have hands-on experience in machine learning, deep learning, NLP, and LLM-based solutions, along with proficiency in Python, SQL, Power BI, and advanced Excel. This role involves building scalable forecasting models and leveraging AI/GenAI to deliver actionable business insights.
Key Responsibilities:
- Develop and deploy demand forecasting models using machine learning and deep learning techniques.
- Analyze historical data to identify trends, seasonality, and demand patterns.
- Build predictive models to improve supply chain and inventory planning.
- Work with large datasets using Python and SQL for data extraction, transformation, and analysis.
- Design dashboards and reports using Power BI for business stakeholders.
- Utilize advanced Excel techniques (Pivot Tables, Power Query, formulas) for analysis and reporting.
- Build and integrate NLP-based solutions for text data analysis and insights.
- Develop and implement LLM-based applications using Generative AI frameworks.
- Design and deploy RAG (Retrieval-Augmented Generation) pipelines for intelligent data retrieval and response generation.
- Collaborate with cross-functional teams (operations, finance, product) to align forecasting and AI solutions.
- Continuously improve model accuracy and performance through experimentation and optimization.
Required Skills:
- Strong proficiency in Python (Pandas, NumPy, Scikit-learn, TensorFlow/PyTorch).
- Solid understanding of machine learning & deep learning algorithms.
- Experience in demand forecasting / time-series analysis (ARIMA, Prophet, LSTM, etc.).
- Hands-on experience with NLP techniques and libraries (NLTK, SpaCy, Transformers).
- Experience working with LLMs and Generative AI frameworks (OpenAI, Hugging Face, LangChain, etc.).
- Strong understanding of RAG architectures and vector databases (FAISS, Pinecone, etc.).
- Advanced knowledge of SQL for data manipulation.
- Hands-on experience with Power BI for visualization and reporting.
- Expertise in advanced Excel (Power Query, dashboards, data modeling).
- Strong analytical and problem-solving skills.
Preferred Qualifications:
- Experience in supply chain, logistics, or e-commerce forecasting.
- Knowledge of cloud platforms (AWS, Azure, or GCP).
- Familiarity with data pipelines and ETL processes.
- Understanding of business metrics and KPIs related to demand planning.
 Machine Learning (ML)
Key Responsibilities
Strong understanding of Machine Learning algorithms (supervised and unsupervised)
Hands-on experience with Deep Learning frameworks (TensorFlow, PyTorch, or similar)
Experience in NLP techniques and libraries (NLTK, spaCy, Hugging Face, etc.)
Solid knowledge of Statistics, probability, and data analysis methods
Proficiency in SQL for querying relational databases
Strong programming skills in Python (or similar languages)
Excellent communication skills with the ability to explain complex concepts simply
Required Qualifications
3+ years of hands-on experience as a Data Scientist or in a similar role.
Strong expertise in classical machine learning and regression modeling.
Solid understanding of statistics, including probability, distributions, hypothesis testing,
and correlation analysis.
Proficiency in Python with libraries such as: scikit-learn pandas NumPy
Experience working with structured/tabular data.
Strong problem-solving and analytical thinking skills.
Ability to clearly explain models and results to non-technical stakeholders.
Data SciencePythonRole Overview
As a Data Scientist, you will work with business stakeholders, AI engineers, and domain experts to transform data into actionable insights and intelligent solutions. You will develop machine learning models, perform statistical analysis, and contribute to AI-driven products that create measurable business impact.
Key Responsibilities
Data Science & Machine Learning
- Analyze structured and unstructured data to identify patterns, trends, and business opportunities.
- Perform exploratory data analysis (EDA), feature engineering, and data preparation.
- Develop, evaluate, and optimize machine learning models for prediction, classification, clustering, and forecasting.
- Apply statistical techniques to solve business problems and validate model performance.
- Design and execute experiments to improve model accuracy and business outcomes.
AI Solution Development
- Collaborate with AI Engineers, Data Engineers, and domain experts to build AI-powered solutions.
- Translate business requirements into scalable data science approaches.
- Contribute to Generative AI and advanced analytics initiatives where applicable.
- Document methodologies, model performance, and key findings.
Required Technical Skills
- Strong programming skills in Python and SQL for data analysis, feature engineering, and machine learning.
- Strong understanding of Statistics, Probability, Linear Algebra, and Calculus as applied to machine learning and data science.
- Experience with Exploratory Data Analysis (EDA), data preprocessing, feature engineering, feature selection, and handling missing or imbalanced data.
- Good understanding of Supervised, Unsupervised, and Ensemble Machine Learning algorithms, including their assumptions, strengths, limitations, and appropriate use cases.
- Strong knowledge of Regression, Classification, Clustering, Time Series Forecasting, Dimensionality Reduction, Recommendation Systems, and Anomaly Detection techniques.
- Experience with Model Evaluation, Cross-Validation, Hyperparameter Optimization, Bias-Variance Trade-off, Feature Importance, Explainable AI (XAI), and Performance Metrics.
- Understanding of Statistical Inference, Hypothesis Testing, Probability Distributions, Sampling Techniques, Confidence Intervals, and A/B Testing.
- Experience translating business problems into analytical approaches and developing scalable, data-driven solutions.
- Working knowledge of Generative AI, Large Language Models (LLMs), Prompt Engineering, and Retrieval-Augmented Generation (RAG) is preferred.
Preferred Qualifications
- Bachelor's or master's degree in computer science, Artificial Intelligence, Data Science, Statistics, Mathematics, Engineering, or a related field.
- 2–4 years of experience developing machine learning or data science solutions.
- Experience working on end-to-end data science projects in a business environment.
Nice to Have
- Exposure to Generative AI, LLMs, RAG, or Agentic AI.
- Experience with Computer Vision or Natural Language Processing (NLP).
- Familiarity with cloud-based AI platforms.
- Knowledge of construction, engineering, manufacturing, or industrial domains.
- Participation in hackathons, research, Kaggle competitions, or open-source projects.
Soft Skills
Strong analytical and problem-solving skills, effective communication and collaboration, ownership mindset, adaptability, continuous learning, and a passion for innovation.
 PythonMachine Learning (ML)
Description
We’re seeking a highly skilled, execution-focused Senior Data Scientist with a minimum of 5 years of experience. This role demands hands-on expertise in building, deploying, and optimizing machine learning models at scale, while working with big data technologies and modern cloud platforms. You will be responsible for driving data-driven solutions from experimentation to production, leveraging advanced tools and frameworks across Python, SQL, Spark, and AWS. The role requires strong technical depth, problem-solving ability, and ownership in delivering business impact through data science.
Responsibilities
- Design, build, and deploy scalable machine learning models into production systems.
- Develop advanced analytics and predictive models using Python, SQL, and popular ML/DL frameworks (Pandas, Scikit-learn, TensorFlow, PyTorch).
- Leverage Databricks, Apache Spark, and Hadoop for large-scale data processing and model training.
- Implement workflows and pipelines using Airflow and AWS EMR for automation and orchestration.
- Collaborate with engineering teams to integrate models into cloud-based applications on AWS.
- Optimize query performance, storage usage, and data pipelines for efficiency.
- Conduct end-to-end experiments, including data preprocessing, feature engineering, model training, validation, and deployment.
- Drive initiatives independently with high ownership and accountability.
- Stay up to date with industry best practices in machine learning, big data, and cloud-native deployments.
Requirements
- Minimum 5 years of experience in Data Science or Applied Machine Learning.
- Strong proficiency in Python, SQL, and ML libraries (Pandas, Scikit-learn, TensorFlow, PyTorch).
- Proven expertise in deploying ML models into production systems.
- Experience with big data platforms (Hadoop, Spark) and distributed data processing.
- Hands-on experience with Databricks, Airflow, and AWS EMR.
- Strong knowledge of AWS cloud services (S3, Lambda, SageMaker, EC2, etc.).
- Solid understanding of query optimization, storage systems, and data pipelines.
- Excellent problem-solving skills, with the ability to design scalable solutions.
- Strong communication and collaboration skills to work in cross-functional teams.
Benefits
- Best-in-class salary: We hire strong talent and compensate accordingly.
- Proximity Talks: Meet and learn from designers, engineers, product leaders, and AI practitioners.
- Continuous learning: Work with a world-class team and stay close to the latest in AI, engineering, and product development.
- High-impact work: Build AI-first systems and products used at scale by global clients.
About Us
Proximity is the trusted technology, design, and consulting partner for some of the biggest Sports, Media, and Entertainment companies in the world. We’re headquartered in San Francisco and have offices in Palo Alto, Dubai, Mumbai, and Bangalore.
Since 2019, Proximity has built high-impact, scalable products used by millions of users every day. Today, we are a global team of engineers, designers, product managers, and experts solving complex problems and building cutting-edge technology at scale.

 Machine Learning (ML)Data Science
Job Description – Data Scientist (Machine Learning & Forecasting)
About the Role
We are looking for a highly skilled Data Scientist with strong expertise in Machine Learning, Traditional Statistical Modelling, Forecasting, and Predictive Analytics. The ideal candidate will have hands-on experience building and deploying end-to-end ML solutions, working with large datasets, and translating business problems into scalable data science solutions.
The role requires a strong foundation in statistics, predictive modelling, feature engineering, model evaluation, and time-series forecasting, along with the ability to collaborate with cross-functional teams to deliver business impact.
Key Responsibilities
- Design, develop, and deploy Machine Learning models for business-critical use cases.
- Build and optimize traditional ML models such as:
- Linear Regression
- Logistic Regression
- Decision Trees
- Random Forest
- Gradient Boosting (XGBoost, LightGBM, CatBoost)
- Support Vector Machines
- Clustering Algorithms
- Develop forecasting solutions using:
- ARIMA / SARIMA
- Prophet
- Exponential Smoothing
- Time-Series Regression Models
- Perform exploratory data analysis (EDA), feature engineering, and data validation.
- Evaluate model performance using appropriate statistical and business metrics.
- Work with structured and semi-structured datasets from multiple sources.
- Collaborate with business stakeholders to understand requirements and translate them into analytical solutions.
- Build scalable data pipelines and support model deployment in production environments.
- Monitor model performance, identify data drift, and implement model retraining strategies.
- Present insights and recommendations to technical and non-technical stakeholders.
Required Skills & Qualifications
- Bachelor's or Master's degree in Computer Science, Statistics, Mathematics, Data Science, Engineering, or a related quantitative field.
- 5+ years of hands-on experience in Data Science, Machine Learning, and Forecasting.
Technical Skills
Machine Learning
- Strong understanding of supervised and unsupervised learning algorithms.
- Experience with ensemble methods and advanced ML techniques.
- Expertise in model selection, hyperparameter tuning, and performance optimization.
Forecasting & Statistics
- Strong understanding of:
- Time-Series Analysis
- Forecasting Techniques
- Statistical Inference
- Hypothesis Testing
- Probability Distributions
- A/B Testing
Programming
- Advanced proficiency in Python.
- Experience with:
- Pandas
- NumPy
- Scikit-learn
- Statsmodels
- XGBoost / LightGBM
- Prophet
Data & SQL
- Strong SQL skills with experience in complex queries and performance optimization.
- Experience working with large-scale datasets.
Visualization
- Experience with Power BI, Tableau, Matplotlib, Seaborn, or Plotly.
- Cloud & MLOps (Preferred)
- Exposure to AWS, Azure, or GCP.
- Understanding of Docker, Kubernetes, CI/CD, and ML model deployment practices.
Key Competencies
- Strong analytical and problem-solving skills.
- Excellent communication and stakeholder management abilities.
- Ability to work independently in a fast-paced environment.
- Strong business acumen and data-driven decision-making mindset.


The recruiter has not been active on this job recently. You may apply but please expect a delayed response.
We are looking for a talented and driven Data Scientist to join our growing Analytics team in India. In this role, you will work at the intersection of advanced machine learning, scalable MLOps infrastructure, and domain-specific healthcare analytics. You will collaborate closely with cross-functional teams to build, deploy, and maintain production-grade ML models that drive real-world impact in clinical trials and healthcare operations.
KEY RESPONSIBILITIES
End-to-End ML Development
• Design, build, and optimize predictive models across the full ML lifecycle—from data ingestion to model serving.
• Conduct rigorous Exploratory Data Analysis (EDA) to surface insights and drive feature engineering decisions.
• Validate model performance using appropriate statistical techniques and domain knowledge.
MLOps & Production Deployment
• Deploy, monitor, and maintain production-grade ML models using Databricks MLFlow endpoints and Unity Catalog.
• Implement CI/CD pipelines for model versioning, experiment tracking, and automated retraining.
• Ensure model reliability, observability, and performance in live production environments.
Language Models & LLM Applications
• Apply transformer-based models (BERT, ClinicalBERT, Trial2Vec) for NLP tasks including classification, NER, and information extraction.
• Build and maintain vector similarity search pipelines for semantic retrieval and recommendation use cases.
• Fine-tune pre-trained models for domain-specific applications in clinical and healthcare contexts.
• Support exploratory work around LLM integration and prompt engineering for internal tooling.
Domain-Driven Analytics
• Apply advanced analytics within complex healthcare and clinical trial datasets—including patient records, trial protocols, and adverse event data.
• Translate ambiguous business problems into structured analytical frameworks with measurable outcomes.
• Partner with domain experts, product managers, and engineering teams to deliver data-driven solutions.
REQUIRED QUALIFICATIONS
Education
• Bachelor’s or Master’s degree in Computer Science, Statistics, Mathematics, Bioinformatics, or a closely related field.
Experience
• 2–4 years of hands-on experience in a data science or machine learning role.
• Demonstrable experience deploying ML models in production environments (not just prototyping).
Technical Skills
• Strong proficiency in Python (pandas, NumPy, scikit-learn, PyTorch / TensorFlow).
• Experience with Databricks, MLFlow (experiment tracking, model registry, endpoints), and Unity Catalog.
• Hands-on experience with BERT-family models and Hugging Face Transformers library.
• Familiarity with vector databases (e.g., FAISS, Pinecone, Weaviate) and embedding-based retrieval.
• Solid understanding of SQL and working with large structured/unstructured datasets.
• Exposure to cloud platforms (AWS / GCP / Azure) and distributed computing frameworks (Spark).
GOOD TO HAVE
• Prior experience with clinical trial data standards (CDISC, CDASH, SDTM) or healthcare ontologies (SNOMED, ICD-10).
• Familiarity with Trial2Vec or similar trial-to-vector embedding approaches.
• Experience with LLM fine-tuning, RAG pipelines, or prompt engineering in a production setting.
• Knowledge of regulatory and compliance considerations in healthcare AI (e.g., FDA guidelines, HIPAA).
• Contributions to open-source ML projects or published research.
THIS ROLE IS NOT FOR YOU IF…
• You have strong SQL/BI skills but limited hands-on ML modelling experience — or you’ve built models only in notebooks without ever deploying them to production.
• Your LLM exposure is limited to API calls and prompt engineering — with no experience fine-tuning models, working with embeddings, or building vector search pipelines.
 Data Science
Job Description:
As a Data Science Intern, you will collaborate with our data science and analytics teams to work on meaningful projects involving data analysis, predictive modeling, and statistical modeling. You will have the opportunity to apply your academic knowledge in a practical, fast-paced environment, contribute to key data-driven projects, and gain valuable experience with industry-leading tools and technologies.
Responsibilities:
- Assist in collecting, cleaning, and preprocessing data from various sources.
- Perform exploratory data analysis to identify trends, patterns, and anomalies.
- Develop and implement machine learning models and algorithms.
- Create data visualizations and reports to communicate findings to stakeholders.
- Collaborate with team members on data-driven projects and research.
- Participate in meetings and contribute to discussions on project progress and strategy.
- Work with large datasets to clean, preprocess, and analyze data.
- Build and deploy statistical and machine learning models to generate actionable insights.
- Conduct exploratory data analysis (EDA) to uncover trends, patterns, and correlations.
- Assist in the creation of data visualizations and dashboards for reporting insights.
- Support the development and improvement of data pipelines and algorithms.
- Collaborate with cross-functional teams to understand data needs and translate them into actionable analytics solutions.
- Contribute to the documentation and presentation of results, findings, and recommendations.
- Participate in team meetings, brainstorming sessions, and project discussions.
Duration: 03 Months (with the possibility of extending up to 6 months)
MODE: Work From Home (Online)
Requirements:
- Any Graduate / PassOuts / Freasher can apply.
- Currently pursuing a Bachelor's or Master’s degree in Data Science, Computer Science, Mathematics, Statistics, or a related field.
- Proficiency in programming languages such as Python, R, or SQL.
- Strong foundation in statistics, probability, and data analysis techniques.
Benefits
Internship Certificate
Letter of recommendation
Stipend Performance Based
Part time work from home (2-3 Hrs per day)
5 days a week, Fully Flexible Shift
Data SciencePython🚀 We’re Hiring | Data Scientist 🧠📊
Ready to turn data into real-world intelligence? Join us and work on exciting AI/ML & data-driven solutions!
🔹 Experience: 8+ Years
🔹 Must-Have Skills:
🐍 Python | 🤖 Machine Learning | ☁️ Cloud | 🧠 NLP | 📊 Data Visualization
📍 Location: Pune
💼 Work Mode: Work from Office
If you're passionate about Data Science, AI & solving complex business problems, we’d love to hear from you!
📩 Interested? Kindly text
#Hiring #DataScientist #DataScience #MachineLearning #Python #NLP #AI #Cloud #DataVisualization #TechJobs #HiringNow













 Follow Cutshort
Shubham Vishwakarma
Full Stack Developer - Averlon