
Data Engineer- GCP at Kloud9 Technologies · Bengaluru (Bangalore) · 3 - 6 years · ₹18L - ₹27L / yr · Profitable · Posted 20 Mar 2023

 GitHub
About Kloud9:
Kloud9 exists with the sole purpose of providing cloud expertise to the retail industry. Our team of cloud architects, engineers and developers help retailers launch a successful cloud initiative so you can quickly realise the benefits of cloud technology. Our standardised, proven cloud adoption methodologies reduce the cloud adoption time and effort so you can directly benefit from lower migration costs.
Kloud9 was founded with the vision of bridging the gap between E-commerce and cloud. The E-commerce of any industry is limiting and poses a huge challenge in terms of the finances spent on physical data structures.
At Kloud9, we know migrating to the cloud is the single most significant technology shift your company faces today. We are your trusted advisors in transformation and are determined to build a deep partnership along the way. Our cloud and retail experts will ease your transition to the cloud.
Our sole focus is to provide cloud expertise to retail industry giving our clients the empowerment that will take their business to the next level. Our team of proficient architects, engineers and developers have been designing, building and implementing solutions for retailers for an average of more than 20 years.
We are a cloud vendor that is both platform and technology independent. Our vendor independence not just provides us with a unique perspective into the cloud market but also ensures that we deliver the cloud solutions available that best meet our clients' requirements.
What we are looking for:
● 3+ years’ experience developing Big Data & Analytic solutions
● Experience building data lake solutions leveraging Google Data Products (e.g. Dataproc, AI Building Blocks, Looker, Cloud Data Fusion, Dataprep, etc.), Hive, Spark
● Experience with relational SQL/No SQL
● Experience with Spark (Scala/Python/Java) and Kafka
● Work experience with using Databricks (Data Engineering and Delta Lake components)
● Experience with source control tools such as GitHub and related dev process
● Experience with workflow scheduling tools such as Airflow
● In-depth knowledge of any scalable cloud vendor(GCP preferred)
● Has a passion for data solutions
● Strong understanding of data structures and algorithms
● Strong understanding of solution and technical design
● Has a strong problem solving and analytical mindset
● Experience working with Agile Teams.
● Able to influence and communicate effectively, both verbally and written, with team members and business stakeholders
● Able to quickly pick up new programming languages, technologies, and frameworks
● Bachelor’s Degree in computer science
Why Explore a Career at Kloud9:
With job opportunities in prime locations of US, London, Poland and Bengaluru, we help build your career paths in cutting edge technologies of AI, Machine Learning and Data Science. Be part of an inclusive and diverse workforce that's changing the face of retail technology with their creativity and innovative solutions. Our vested interest in our employees translates to deliver the best products and solutions to our customers!


Shubham Vishwakarma
Full Stack Developer - Averlon


About Kloud9 Technologies
About
Kloud9 was founded with the vision of enabling our customers to transform into an intelligent enterprise with our “AI-First” approach. We help our customers in their data transformation and insights transformation journeys and enable them to make smart business decisions.
At Kloud9, we know AI & ML is one of the key technologies that can help organizations to significantly improve their customer experiences and transform their business operations to enable them to survive & thrive in this global competitive market.
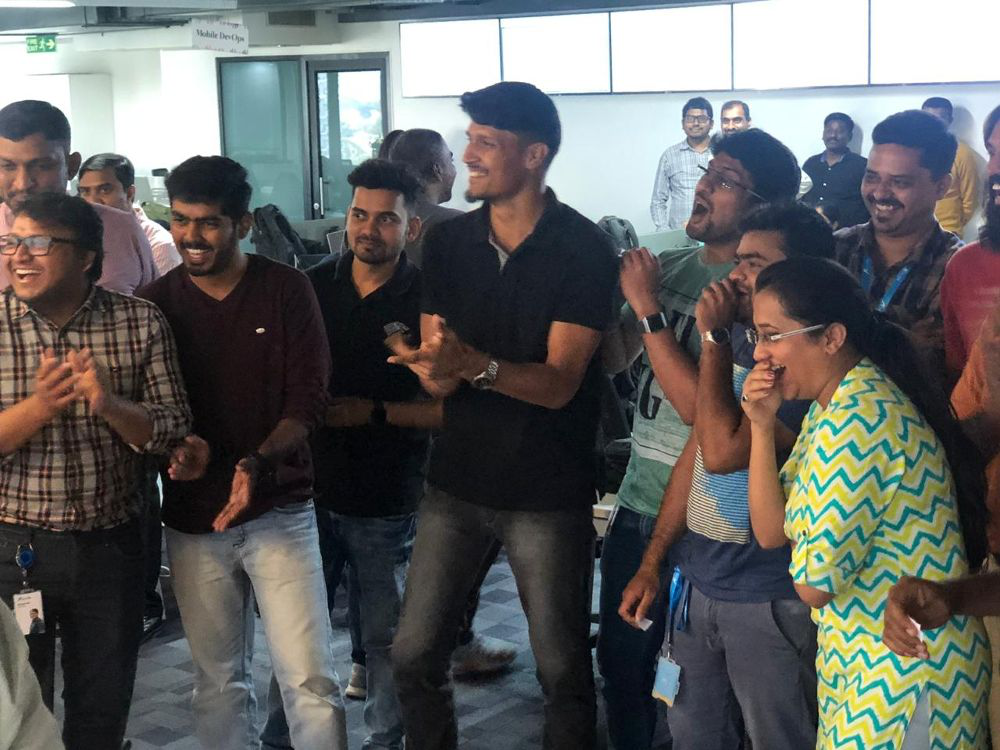
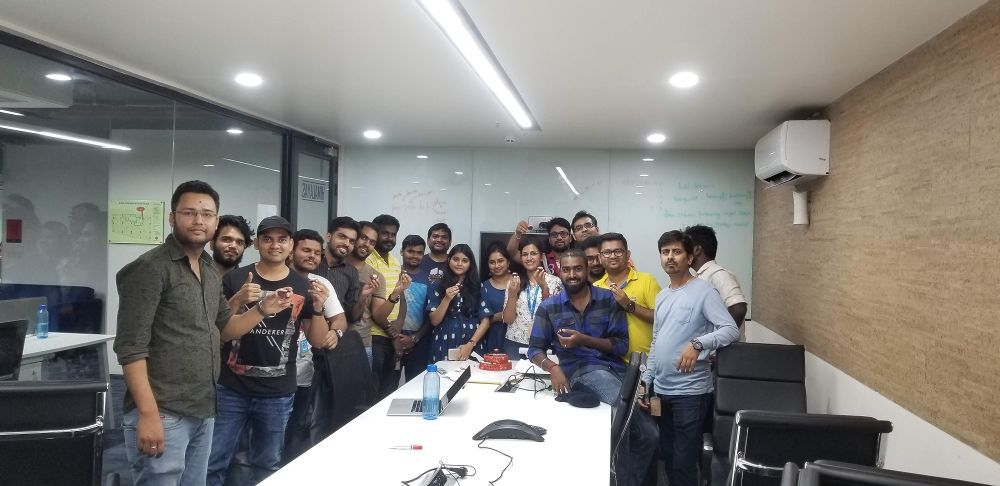
Photos
Company social profiles


Similar jobs (10)
 Kubernetes
 Scala
Description
We are looking for Senior Data Engineers to join our AdTech team and build scalable, high-performance data platforms that power advertising insights and analytics. The ideal candidate will have strong experience in distributed data processing, ETL pipelines, and Big Data technologies, with hands-on expertise in Spark and Scala.
You will work on designing, developing, and optimizing large-scale data pipelines while collaborating closely with cross-functional engineering teams to build reliable, production-grade data solutions.
Key Responsibilities
- Design, develop, and maintain scalable ETL pipelines for large-scale data processing.
- Build and optimize distributed data applications using Spark and Scala.
- Develop reliable, high-performance data pipelines for batch and streaming workloads.
- Work with large datasets to ensure data quality, consistency, and performance.
- Collaborate with engineering, product, and analytics teams to deliver robust data solutions.
- Optimize data workflows for scalability, reliability, and cost efficiency.
- Deploy and manage data workloads in cloud and containerized environments.
- Troubleshoot production issues and continuously improve platform performance.
Requirements
Candidates who demonstrate:
- 5+ years of experience in Data Engineering or Big Data Engineering.
- Strong hands-on experience with Apache Spark and Scala.
- Experience building and maintaining ETL pipelines.
- Familiarity with Google Cloud Storage (GCS).
- Experience with Kubernetes (K8s).
- Strong SQL skills and understanding of distributed data processing.
- Excellent debugging, problem-solving, and performance optimization skills.
- Strong communication and collaboration skills.
Good to Have
- Experience with AWS and cloud-native data services.
- Familiarity with streaming technologies such as Kafka.
- Experience working on large-scale data platforms or AdTech systems.
- Exposure to orchestration tools such as Airflow.
Benefits
- Best-in-class salary: We hire strong talent and compensate accordingly.
- Proximity Talks: Meet and learn from designers, engineers, product leaders, and AI practitioners.
- Continuous learning: Work with a world-class team and stay close to the latest in AI, engineering, and product development.
- High-impact work: Build AI-first systems and products used at scale by global clients.
About Us
Proximity is the trusted technology, design, and consulting partner for some of the biggest Sports, Media, and Entertainment companies in the world. We’re headquartered in San Francisco and have offices in Palo Alto, Dubai, Mumbai, and Bangalore.
Since 2019, Proximity has built high-impact, scalable products used by millions of users every day. Today, we are a global team of engineers, designers, product managers, and experts solving complex problems and building cutting-edge technology at scale.

 Java
Company Name – Wissen Technology
Group of companies in India – Wissen Technology & Wissen Infotech
Work Location – Whitefield, Bangalore
Website and Company profile:
www.wissen.com
LinkedIn Page:
https://www.linkedin.com/company/wissen-technology/
While you may already know about Wissen and the company history, here is a quick rundown for you.
About Wissen Technology:
· The Wissen Group was founded in the year 2000. Wissen Technology, a part of Wissen Group, was established in the year 2015.
· Wissen Technology is a specialized technology company that delivers high-end consulting for organizations in the Banking & Finance, Telecom, and Healthcare domains. We help clients build world class products.
· Our workforce has highly skilled professionals, with leadership and senior management executives who have graduated from Ivy League Universities like Wharton, MIT, IITs, IIMs, and NITs and with rich work experience in some of the biggest companies in the world.
· Wissen Technology has grown its revenues by 400% in these five years without any external funding or investments.
· Globally present with offices US, India, UK, Australia, Mexico, and Canada.
· We offer an array of services including Application Development, Artificial Intelligence & Machine Learning, Big Data & Analytics, Visualization & Business Intelligence, Robotic Process Automation, Cloud, Mobility, Agile & DevOps, Quality Assurance & Test Automation.
· Wissen Technology has been certified as a Great Place to Work®.
· Wissen Technology has been voted as the Top 20 AI/ML vendor by CIO Insider in 2020.
· Over the years, Wissen Group has successfully delivered $650 million worth of projects for more than 20 of the Fortune 500 companies.
· We have served client across sectors like Banking, Telecom, Healthcare, Manufacturing, and Energy. They include likes of Morgan Stanley, Goldman Sachs, MSCI, StateStreet, Flipkart, Swiggy, Trafigura, GE to name a few.
About Role :
Key Responsibilities
- Build and maintain data transformation pipelines using java Spark
- Develop and optimize large-scale/CPU intensive data processing using Apache Spark
- Orchestrate workflows using Airflow
- Implement data quality checks, testing, and monitoring for pipeline. Good to have exposer into managing metadata, cataloguing, and lineage
- Support schema evolution, backfills, and incremental processing
- Ensure pipelines meet SLAs for freshness, reliability, and performance
- Expertise/working knowledge in Spark and HBase(semantic layer, virtual datasets, Reflections)
Required Skills & Qualifications
- Strong hands-on experience with
- HBase
- Apache Spark
- Experience with HBase or similar lakehouse query engines
- Airflow
- Understanding of data catalogs and lineage (e.g., OpenLineage, DataHub, Apache Polaris , openlineage)
- Proficiency in Java
- Experience with Git-based development and CI/CD
Nice-to-Have Skills
- OpenTable format/Iceberg ,Apache Arrow
- CDC-based analytics pipelines
- Cloud platforms (AWS)
- Kubernetes-based data platforms


 Python
1st virtual , 2nd round F2F
Python pyspark, SQL, data engineer
5+yrs
9+yrs
Bangalore/Hyderabad
immediate to 15days.
PythonScalaDescription
We are looking for Senior Data Engineers to join our Data Platform team and build scalable, high-performance data platforms that power data processing, analytics, and downstream applications.
The ideal candidate will have strong experience in distributed data processing, ETL pipelines, and Big Data technologies, with hands-on expertise in Apache Spark and Python Scala.
You will be responsible for designing, developing, and optimizing large-scale data pipelines while collaborating closely with cross-functional engineering teams to build reliable, production-grade data solutions.
Key Responsibilities
- Design, develop, and maintain scalable ETL and data processing pipelines for large-scale datasets.
- Build and optimize distributed data applications using Apache Spark and Python Scala.
- Develop reliable, high-performance data pipelines for batch and streaming workloads.
- Design and manage data workflows using Apache Airflow.
- Build and operate data workloads on AWS, with strong usage of Amazon S3 for large-scale data storage.
- Work with large datasets to ensure data quality, consistency, reliability, and performance.
- Collaborate with engineering, product, analytics, and other platform teams to deliver robust data solutions.
- Optimize data workflows for scalability, reliability, performance, and cost efficiency.
- Troubleshoot production issues, identify bottlenecks, and continuously improve platform performance.
Requirements
Candidates who demonstrate:
- 5+ years of experience in Data Engineering, Big Data Engineering, or a similar role.
- Strong hands-on experience with Apache Spark and Scala.
- Experience designing, building, and maintaining large-scale ETL pipelines.
- Strong hands-on experience with AWS, particularly Amazon S3.
- Hands-on experience with Apache Airflow for workflow orchestration and scheduling.
- Strong SQL skills and a solid understanding of distributed data processing concepts.
- Experience working with batch and/or streaming data pipelines.
- Excellent debugging, problem-solving, and performance optimization skills.
- Strong communication and collaboration skills.
Good to Have
- Experience with Databricks and the broader Databricks data platform.
- Familiarity with streaming technologies such as Apache Kafka.
- Experience working on large-scale data platforms handling high-volume data workloads.
- Exposure to additional AWS data services and cloud-native data architectures.

Senior Data Engineer – Ab Initio | GCP | Spark | Agentic AI
Location: Bangalore
Experience: 5+ Years
Role: Senior Data Engineer
Work Mode: Bangalore
Job Summary
We are looking for an experienced Senior Data Engineer with strong expertise in Ab Initio, GCP, Apache Spark, and Agentic AI. The ideal candidate will have hands-on experience designing and developing scalable data engineering solutions, building data pipelines, and working with modern cloud and AI technologies.
The candidate should be comfortable working across traditional enterprise data platforms and emerging Generative AI / Agentic AI solutions.
Key Responsibilities
- Design, develop, and maintain scalable and high-performance data pipelines using Ab Initio, Spark, and GCP services.
- Develop and optimize complex ETL/ELT workflows using Ab Initio.
- Build and maintain data processing solutions using Apache Spark / PySpark.
- Develop cloud-based data solutions on Google Cloud Platform (GCP).
- Work with GCP data services such as BigQuery, Cloud Storage, Dataflow, Dataproc, Pub/Sub, or equivalent services.
- Perform data integration, transformation, cleansing, and validation.
- Optimize data pipelines for performance, scalability, reliability, and cost.
- Collaborate with data architects,
 Python
Role Overview
We are looking for a GCP Data Engineer with 10+ years of experience to design, develop, and optimize scalable cloud-based data solutions. The ideal candidate will have strong hands-on expertise in GCP, BigQuery, and advanced SQL, with experience building data pipelines and working with large-scale datasets.
Key Responsibilities
- Design and develop scalable data pipelines and ETL/ELT processes on GCP.
- Build, optimize, and maintain data solutions using Google BigQuery.
- Develop complex SQL queries for data transformation, aggregation, and analysis.
- Design efficient data models and optimize pipelines for performance, scalability, and cost.
- Integrate data from multiple sources and ensure data quality, reliability, and availability.
- Troubleshoot pipeline and data issues and drive continuous improvement.
- Collaborate with data architects, analysts, application teams, and business stakeholders.
- Follow best practices for cloud security, data governance, testing, and documentation.
Required Skills
- 8+ years of Data Engineering experience
- Strong hands-on experience with GCP, Django, and MongoDB
- Extensive experience with BigQuery
- Advanced SQL skills
- Strong understanding of ETL/ELT and data pipeline development
- Data modeling and data warehousing experience
- Experience handling large-scale datasets and performance optimization
- Strong problem-solving and communication skills
Good to Have
- GCP services such as Cloud Storage, Dataflow, Pub/Sub, Cloud Composer, or Cloud Functions
- Python or other data engineering languages
- Experience with data governance and security
- Agile development experience
PythonAbout the Role
We are looking for a Senior Data Engineer with strong hands-on expertise in Databricks, Python, PySpark, and SQL to build scalable, high-performance data engineering solutions. You’ll architect and develop large scale, high-performance data pipelines capable of handling massive real-time and batch data volumes across multiple business systems. Databricks is the core enterprise data and processing platform for this role. You will also use Apache Airflow for workflow orchestration and dbt for ELT transformations, and will contribute to designing reliable, secure, and governed data platforms that enable analytics, reporting, and AI-driven use cases.
Key Responsibilities
- Design and implement large-scale data pipelines using Python/PySpark, Databricks, and Microsoft Fabric.
- Develop and optimize data processing workloads in Databricks using PySpark and Spark SQL, with a strong focus on scalability, reliability, performance, and maintainability.
- Develop and maintain dbt models including layered architecture, incremental models, snapshots, macros, testing, and documentation.
- Design, develop, and maintain Apache Airflow DAGs for orchestrating reliable, scalable, and observable data pipelines.
- Design and implement data quality, observability, and governance frameworks, including automated testing, monitoring, lineage, access control, and data privacy standards.
- Partner with analytics, product, and business stakeholders to turn requirements into trustworthy datasets, and raise the engineering bar through design discussions, code reviews, and mentoring junior engineers.
Required Skills
- Strong expertise in Python for developing scalable, modular, and production-ready data engineering applications.
- Strong expertise in PySpark, including DataFrame API, Spark SQL, Structured Streaming, partitioning strategies, joins, caching, handling data skew, and Spark performance optimization.
- Strong hands-on experience with Databricks for data ingestion, transformation, processing, and optimization, including Delta Lake, Unity Catalog, Databricks Workflows, notebooks, jobs, and Databricks-native data engineering capabilities.
- Strong experience in Databricks/Spark performance tuning, including query and job optimization, partitioning, file sizing, caching, join optimization, handling data skew, and efficient use of compute resources.
- Hands-on experience with Delta Lake, including transactional data processing, schema management, incremental data processing, and reliable batch and streaming data pipelines.
- Hands-on experience in developing dbt projects using layered architecture, incremental models, snapshots, macros/Jinja, testing, documentation, and deployment best practices.
- Expertise in advanced SQL and data modelling — dimensional modeling, slowly changing dimensions, schema evolution, and query optimization.
- Hands-on experience in developing and managing Apache Airflow DAGs, scheduling workflows, dependency management, retries, backfills, and operational monitoring.
- Hands-on experience with at least one major cloud platform (AWS, Azure or GCP).
- Strong problem-solving skills and the ability to work independently with business and analytics stakeholders.
Nice to Have
- Hands-on exposure to Microsoft Fabric for data integration and analytics.
- Experience using AI coding assistants (e.g. Claude Code, GitHub Copilot) as part of a development workflow.
- Familiarity with modern DevOps practices, including CI/CD pipelines, Infrastructure as Code (IaC), and containerization (Docker/Kubernetes).
- Domain expertise in financial services.
Job Description:
We are seeking a skilled Senior Data Engineer with expertise in Databricks to join our dynamic data team. The ideal candidate will design, build, and maintain scalable data pipelines and architectures to support our organization's data-driven initiatives and leverage Databricks to process large-scale datasets, optimize data workflows, enable advanced analytics and machine learning, and integrate Power BI for data visualization and reporting.
Key Responsibilities
· 5-8 years of professional work experience in a relevant field
· Proficient in Microsoft Fabric platform, Azure Databricks, ADF, Delta Lake, SQL Data Warehouse, Unity Catalog.
· Good Experience on Microsoft Dynamics 365
· Experience/ prior knowledge on semi structure data and Structured Streaming, Azure synapse, data lake, data warehouse.
· Proficient in creating Azure Data Factory pipelines for ETL/ELT processing; copy activity, custom Azure development etc.
· Good knowledge of SQL and Python for data manipulation, transformation, and analysis
· Understand business requirements to set functional specifications for reporting applications
- Data Pipeline Development: Design, develop, and maintain robust, scalable data pipelines using Databricks, Apache Spark, and other cloud-based technologies.
- Data Integration: Ingest, transform, and integrate data from diverse sources, including APIs, databases, streaming platforms, and third-party systems, into Databricks for analytics and reporting.
- Power BI Integration: Develop and optimize data models and datasets in Databricks for use in Power BI, ensuring efficient data connections and high-quality visualizations.
- Performance Optimization: Optimize data workflows, API calls, and queries on Databricks and Power BI for performance, cost-efficiency, and scalability.
- Data Modeling: Build and maintain data models to support business requirements, ensuring data quality, consistency, and accessibility for analytics and reporting.
- Cloud Integration: Implement data solutions on cloud platforms (e.g., AWS, Azure, GCP) integrated with Databricks, Power BI, and API ecosystems.
- Security & Compliance: Implement data governance, security, and compliance best practices within Databricks, Power BI, and API environments.
- Technical Skills:
- Proficiency in Databricks, including Delta Lake, Spark SQL.
- Strong programming skills in Python, Scala, or Java.
- Experience with Apache Spark for big data processing.
- Knowledge of SQL for querying and transforming data.
- Proficiency in Power BI for creating data models, DAX queries, and interactive dashboards.
Preferred Qualifications
- Databricks certification (e.g., Databricks Certified Data Engineer Associate/Professional).
Experience with real-time data processing and streaming
 Python
Job Summary: GCP Data Engineering Lead
Experience: 9+ Years
Location: Bangalore / Hyderabad
Notice Period: Immediate to 15 Days
Key Skills:
- Strong experience in GCP Data Engineering
- Proven Technical Lead / Lead experience
- Strong programming skills in Python
- Hands-on experience with PySpark
- Strong expertise in SQL / PL-SQL
- Good understanding of GCP data services and data engineering concepts
- Experience in designing and developing scalable data pipelines
- Strong problem-solving and technical leadership skills
Roles & Responsibilities:
- Lead the design and development of scalable GCP data engineering solutions.
- Develop and optimize data pipelines using Python, PySpark and SQL/PL-SQL.
- Design data processing solutions and ensure performance and scalability.
- Provide technical leadership, conduct code reviews, and mentor team members.
- Collaborate with business and technical teams to understand requirements and deliver data solutions.
- Troubleshoot issues and ensure quality across the data engineering lifecycle.

 Python
Experience: 5+ Years
Employment Type: Full-Time
Role Overview
We are looking for an experienced GCP Data Engineer with 5+ years of experience in data engineering and strong hands-on expertise in Google BigQuery, Google Cloud Storage (GCS), Airflow/Cloud Composer, Python, and Vertex AI. The candidate should be capable of designing, developing, and maintaining scalable data pipelines and cloud-based data solutions on Google Cloud Platform.
Key Skills – Mandatory
- BigQuery – Strong hands-on experience in data warehousing, SQL, optimization, and performance tuning.
- Google Cloud Storage (GCS) – Experience with data storage, file management, and integration with data pipelines.
- Airflow / Cloud Composer – Experience in developing, scheduling, monitoring, and managing data workflows.
- Python – Strong programming skills for data engineering, ETL/ELT development, automation, and pipeline implementation.
- Vertex AI – Experience working with ML/AI workflows, model integration, or data pipelines supporting AI/ML solutions.
Good to Have / Added Advantage
- Dataproc – Experience with distributed data processing and Spark-based workloads.
- Cloud Data Fusion – Experience in building and managing data integration pipelines.
- Cloud Run – Understanding of deploying and running containerized applications/services on GCP.
- Experience with ETL/ELT processes and data pipeline development.
- Knowledge of GCP data architecture and cloud-native services.
- Experience in data quality, validation, monitoring, and troubleshooting.
Responsibilities
- Design, develop, and maintain scalable GCP-based data pipelines.
- Build and optimize data solutions using BigQuery and Cloud Storage.
- Develop and manage workflows using Airflow / Cloud Composer.
- Write efficient and reusable Python code for data processing and automation.
- Support Vertex AI integrations and AI/ML data workflows.
- Monitor pipeline performance and troubleshoot data processing issues.
- Work with cross-functional teams to understand data requirements and deliver reliable solutions.
- Implement best practices for data security, quality, scalability, and performance.
You must have :
- 5+ years of overall experience in Data Engineering.
- Strong hands-on experience with BigQuery, GCS, Airflow/Cloud Composer, Python, and Vertex AI.
- Strong understanding of data engineering concepts, ETL/ELT, data pipelines, and cloud technologies.
- Dataproc, Data Fusion, and Cloud Run experience will be an added advantage.













 Follow Cutshort
Shubham Vishwakarma
Full Stack Developer - Averlon