
Bigdata Lead Architecture at DataMetica · Pune, Hyderabad · 7 - 12 years · ₹12L - ₹33L / yr · Profitable · Posted 25 Aug 2021
 Python
Job description
Role : Lead Architecture (Spark, Scala, Big Data/Hadoop, Java)
Primary Location : India-Pune, Hyderabad
Experience : 7 - 12 Years
Management Level: 7
Joining Time: Immediate Joiners are preferred
- Attend requirements gathering workshops, estimation discussions, design meetings and status review meetings
- Experience of Solution Design and Solution Architecture for the data engineer model to build and implement Big Data Projects on-premises and on cloud.
- Align architecture with business requirements and stabilizing the developed solution
- Ability to build prototypes to demonstrate the technical feasibility of your vision
- Professional experience facilitating and leading solution design, architecture and delivery planning activities for data intensive and high throughput platforms and applications
- To be able to benchmark systems, analyses system bottlenecks and propose solutions to eliminate them
- Able to help programmers and project managers in the design, planning and governance of implementing projects of any kind.
- Develop, construct, test and maintain architectures and run Sprints for development and rollout of functionalities
- Data Analysis, Code development experience, ideally in Big Data Spark, Hive, Hadoop, Java, Python, PySpark,
- Execute projects of various types i.e. Design, development, Implementation and migration of functional analytics Models/Business logic across architecture approaches
- Work closely with Business Analysts to understand the core business problems and deliver efficient IT solutions of the product
- Deployment sophisticated analytics program of code using any of cloud application.
Perks and Benefits we Provide!
- Working with Highly Technical and Passionate, mission-driven people
- Subsidized Meals & Snacks
- Flexible Schedule
- Approachable leadership
- Access to various learning tools and programs
- Pet Friendly
- Certification Reimbursement Policy
- Check out more about us on our website below!
www.datametica.com


Shubham Vishwakarma
Full Stack Developer - Averlon


About DataMetica
About
Company video

Photos
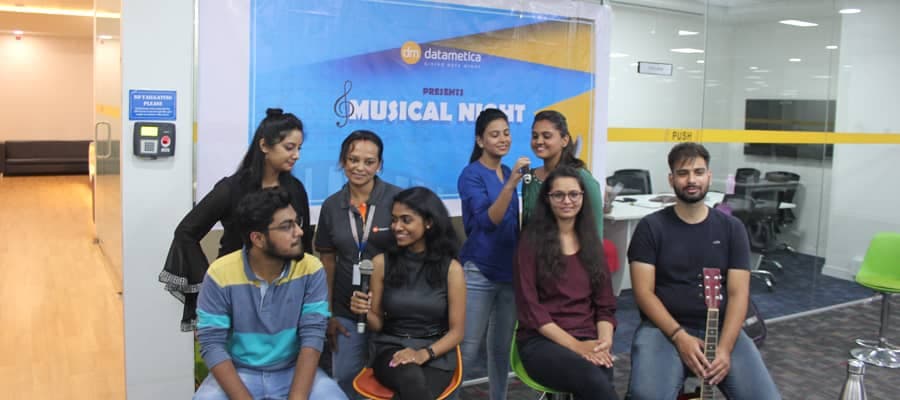
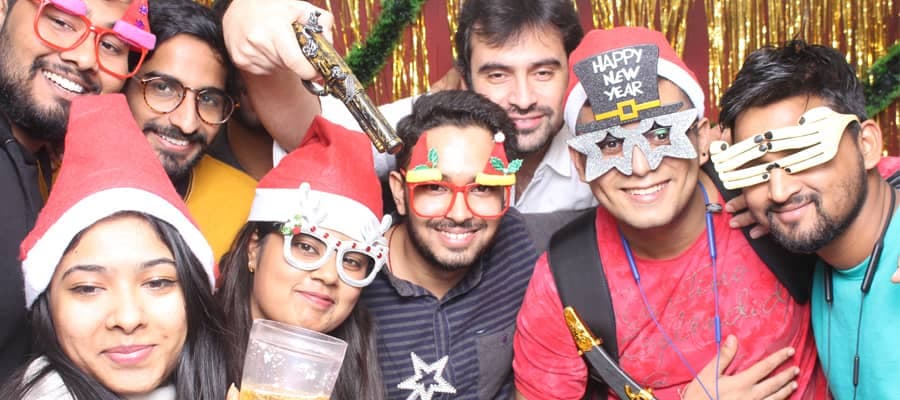


Company social profiles


Similar jobs (10)

 Python
Job Title : Senior Data Engineer – Databricks
Experience : 14 to 20 Years
Location : HSR Layout, Bangalore
Work Mode : Hybrid – 3 Days WFO
Shift : 11:30 AM – 07:30 PM IST
Positions : 2
Notice Period : Immediate Joiners Only
Interview : 1 Technical Round + 2 Client Rounds
Role Overview :
We are looking for a Senior Data Engineer to build and lead enterprise-scale data platforms for a Switzerland-based commodity client.
The role requires a strong hands-on Data Engineering professional with expertise in Databricks, PySpark, Python, SQL, and AWS, along with technical leadership and stakeholder management experience.
Must-Have Skills :
- 14 to 20 years of Data Engineering experience
- Databricks & Apache Spark / PySpark
- Python & SQL
- AWS Cloud
- Lakehouse Architecture
- ETL / ELT & Distributed Data Processing
- Batch & Streaming Pipelines
- Data Pipeline Optimization & Data Modeling
- CDC & Incremental Processing
- Git, CI/CD & Testing
- Data Quality, Monitoring & Observability
- Technical Leadership & Stakeholder Management
Key Responsibilities :
- Design and build scalable data pipelines using Databricks, PySpark, Python, SQL, and AWS.
- Own data products from design through production.
- Develop batch / streaming pipelines and reusable ETL / ELT frameworks.
- Optimize pipelines for performance, scalability, reliability, and cost.
- Design scalable data architectures and data models.
- Implement data quality, monitoring, lineage, and CI/CD practices.
- Lead technical discussions and mentor engineering teams.
- Collaborate with business stakeholders, architects, product owners, and engineering teams.
- Remain hands-on while providing technical leadership.
Ideal Candidate :
A 14 to 20 years experienced, hands-on Data Engineering leader with strong Databricks + PySpark + AWS expertise, excellent communication, stakeholder management, and experience delivering enterprise-scale data platforms.
🔴 Super Urgent : Only Bangalore-based immediate joiners.

Job Description:
We are seeking a skilled Senior Data Engineer with expertise in Databricks to join our dynamic data team. The ideal candidate will design, build, and maintain scalable data pipelines and architectures to support our organization's data-driven initiatives and leverage Databricks to process large-scale datasets, optimize data workflows, enable advanced analytics and machine learning, and integrate Power BI for data visualization and reporting.
Key Responsibilities
· 5-8 years of professional work experience in a relevant field
· Proficient in Microsoft Fabric platform, Azure Databricks, ADF, Delta Lake, SQL Data Warehouse, Unity Catalog.
· Good Experience on Microsoft Dynamics 365
· Experience/ prior knowledge on semi structure data and Structured Streaming, Azure synapse, data lake, data warehouse.
· Proficient in creating Azure Data Factory pipelines for ETL/ELT processing; copy activity, custom Azure development etc.
· Good knowledge of SQL and Python for data manipulation, transformation, and analysis
· Understand business requirements to set functional specifications for reporting applications
- Data Pipeline Development: Design, develop, and maintain robust, scalable data pipelines using Databricks, Apache Spark, and other cloud-based technologies.
- Data Integration: Ingest, transform, and integrate data from diverse sources, including APIs, databases, streaming platforms, and third-party systems, into Databricks for analytics and reporting.
- Power BI Integration: Develop and optimize data models and datasets in Databricks for use in Power BI, ensuring efficient data connections and high-quality visualizations.
- Performance Optimization: Optimize data workflows, API calls, and queries on Databricks and Power BI for performance, cost-efficiency, and scalability.
- Data Modeling: Build and maintain data models to support business requirements, ensuring data quality, consistency, and accessibility for analytics and reporting.
- Cloud Integration: Implement data solutions on cloud platforms (e.g., AWS, Azure, GCP) integrated with Databricks, Power BI, and API ecosystems.
- Security & Compliance: Implement data governance, security, and compliance best practices within Databricks, Power BI, and API environments.
- Technical Skills:
- Proficiency in Databricks, including Delta Lake, Spark SQL.
- Strong programming skills in Python, Scala, or Java.
- Experience with Apache Spark for big data processing.
- Knowledge of SQL for querying and transforming data.
- Proficiency in Power BI for creating data models, DAX queries, and interactive dashboards.
Preferred Qualifications
- Databricks certification (e.g., Databricks Certified Data Engineer Associate/Professional).
Experience with real-time data processing and streaming


 Java
 Scala
4 - 10 years of experience in designing and buildingarchitecting highly resilient data platforms
∙Strong knowledge of data engineering, architecture and data modeling
∙Experience in platforms like Databricks and Snowflake
∙Experience on building applications on cloud (AWS or Azure or Google Cloud)
∙Strong analytical and problem-solving skills
∙Prior experience in developing data or computation intensive (e.g. grid based) backend applications is an
advantage
∙OOP design skills with an understanding or at least personal interest towards the concepts of Functional
Programming
∙Willingness to understand and enhance other people’s code, being able to work in an environment where
developers will oversee and work on wider components also dealing with older “legacy” code
∙Strong programming skills (Java/ Scala / Python) skills with the willingness to pick up the other language if not
already mastered at a sufficient level is important
∙Spring knowledge is an advantage, but in general willingness to learn, work with and even enhance in-house
developed frameworks is a must
∙Prior experience in working with Git, Bitbucket, Jenkins, working with PR-s, using JIRA, following the Scrum Agile
methodology is an advantage
∙Prior knowledge of financial products is an advantage
∙Bachelors or Masters in any relevant field of IT/Engineering area is an advantage
PythonKey Skills:
Python & System Design: Strong expertise in Python and system design, with proven experience architecting scalable, production-grade systems.
LLM & Agentic AI: Proven experience building LLM-based and agentic systems from the ground up and evaluating them based on reproducibility, calibration, and cost.
Cloud & Data Architecture: Deep understanding of data and cloud architecture across AWS and Azure, including multi-store data design, distributed systems, streaming, security, and cost optimization.
Azure Databricks: Hands-on production experience with Azure Databricks architecture, including Unity Catalog, Delta Lake, cluster policy design, job orchestration, and Terraform provisioning.
Supply Chain & Inventory Management: Strong domain knowledge of supply chain and inventory operations, including demand planning, MRP logic, inventory parameters, and translating business planning decisions into data requirements.
System Architecture & Technical Decision-Making: Ability to make sound architectural decisions based on first principles, evaluate technical trade-offs, and avoid unnecessary complexity and abstraction.
LLM & Agentic AI: Proven experience building LLM-based and agentic systems from the ground up and evaluating them based on reproducibility, calibration, and cost.
Technical Leadership: Ability to influence teams without direct authority, establish technical standards, prepare technical specifications and documentation, and mentor team members.
Experience in pharmaceutical or regulated industries is highly valued.

 Python
Technical Stack
- PySpark
- Databricks
- Microsoft Azure
- SQL
- Kubernetes
Key Responsibilities & Expectations
- Must be self-driven, proactive, and capable of independently delivering high-quality solutions.
- Demonstrate strong ownership and accountability for assigned tasks and deliverables.
- Ability to work with minimal supervision while consistently meeting project objectives and quality standards.
 Python
1st virtual , 2nd round F2F
Python pyspark, SQL, data engineer
5+yrs
9+yrs
Bangalore/Hyderabad
immediate to 15days.
JavaPythonWe are hiring for a Data Engineer & Java scala for a full-time opportunity in Bangalore.
Experience: 4–10 Years
Must-Have Skills:
Java / Scala / Python, Data Engineering, Databricks / Snowflake, and Cloud (AWS / Azure / GCP).
We are looking for strong software engineers with hands-on experience in data platform development, scalable backend programming, data integration, and cloud technologies.
Experience in Banking, Capital Markets, Market Risk, or Regulatory Reporting will be an added advantage.
PythonAbout the Role
We are looking for a Senior Data Engineer with strong hands-on expertise in Databricks, Python, PySpark, and SQL to build scalable, high-performance data engineering solutions. You’ll architect and develop large scale, high-performance data pipelines capable of handling massive real-time and batch data volumes across multiple business systems. Databricks is the core enterprise data and processing platform for this role. You will also use Apache Airflow for workflow orchestration and dbt for ELT transformations, and will contribute to designing reliable, secure, and governed data platforms that enable analytics, reporting, and AI-driven use cases.
Key Responsibilities
- Design and implement large-scale data pipelines using Python/PySpark, Databricks, and Microsoft Fabric.
- Develop and optimize data processing workloads in Databricks using PySpark and Spark SQL, with a strong focus on scalability, reliability, performance, and maintainability.
- Develop and maintain dbt models including layered architecture, incremental models, snapshots, macros, testing, and documentation.
- Design, develop, and maintain Apache Airflow DAGs for orchestrating reliable, scalable, and observable data pipelines.
- Design and implement data quality, observability, and governance frameworks, including automated testing, monitoring, lineage, access control, and data privacy standards.
- Partner with analytics, product, and business stakeholders to turn requirements into trustworthy datasets, and raise the engineering bar through design discussions, code reviews, and mentoring junior engineers.
Required Skills
- Strong expertise in Python for developing scalable, modular, and production-ready data engineering applications.
- Strong expertise in PySpark, including DataFrame API, Spark SQL, Structured Streaming, partitioning strategies, joins, caching, handling data skew, and Spark performance optimization.
- Strong hands-on experience with Databricks for data ingestion, transformation, processing, and optimization, including Delta Lake, Unity Catalog, Databricks Workflows, notebooks, jobs, and Databricks-native data engineering capabilities.
- Strong experience in Databricks/Spark performance tuning, including query and job optimization, partitioning, file sizing, caching, join optimization, handling data skew, and efficient use of compute resources.
- Hands-on experience with Delta Lake, including transactional data processing, schema management, incremental data processing, and reliable batch and streaming data pipelines.
- Hands-on experience in developing dbt projects using layered architecture, incremental models, snapshots, macros/Jinja, testing, documentation, and deployment best practices.
- Expertise in advanced SQL and data modelling — dimensional modeling, slowly changing dimensions, schema evolution, and query optimization.
- Hands-on experience in developing and managing Apache Airflow DAGs, scheduling workflows, dependency management, retries, backfills, and operational monitoring.
- Hands-on experience with at least one major cloud platform (AWS, Azure or GCP).
- Strong problem-solving skills and the ability to work independently with business and analytics stakeholders.
Nice to Have
- Hands-on exposure to Microsoft Fabric for data integration and analytics.
- Experience using AI coding assistants (e.g. Claude Code, GitHub Copilot) as part of a development workflow.
- Familiarity with modern DevOps practices, including CI/CD pipelines, Infrastructure as Code (IaC), and containerization (Docker/Kubernetes).
- Domain expertise in financial services.
Responsibilities and JD
Job Description: We are looking for a Senior Developer with strong expertise in PySpark, Databricks, and Snowflake to build scalable data engineering solutions and enterprise data platforms.
Key Responsibilities:
- Design, develop, and maintain ETL/ELT pipelines using PySpark, Databricks, and Snowflake.
- Develop batch and real-time data processing solutions for structured and semi-structured data.
- Build and optimize Databricks notebooks, workflows, and Delta Lake solutions.
- Design and implement Snowflake databases, schemas, views, stored procedures, tasks, and streams.
- Develop scalable data models, data marts, and data warehouse solutions.
- Optimize PySpark jobs, Databricks workloads, and Snowflake queries for performance and cost efficiency.
- Implement data quality, validation, governance, and security controls.
- Collaborate with business stakeholders, architects, and cross-functional teams to deliver data solutions.
- Manage source control and CI/CD deployments using Git and Azure DevOps.
- Troubleshoot production issues, perform root cause analysis, and ensure pipeline reliability.
- Mentor junior team members and participate in code reviews and technical design discussions.
Required Skills: PySpark, Databricks, Snowflake, Python, SQL.
Experience: 5+ years of Data Engineering experience with strong hands-on expertise in PySpark, Databricks, and Snowflake.
 PythonScala
🚨 HIRING | Data Engineer – Amazon EMR 🔥
We are looking for experienced Data Engineers with strong hands-on expertise in Amazon EMR, Python, and Scala.
📌 JOB DETAILS:
💼 Experience: 6+ Years
💰 CTC: Up to 30 LPA
📍 Location: Bangalore
🔑 MANDATORY SKILLS:
• Amazon EMR
• Python
• Scala
• Data Engineering
📋 KEY REQUIREMENTS:
• 6+ years of relevant experience in Data Engineering.
• Strong hands-on experience with Amazon EMR.
• Strong programming skills in Python and Scala.
• Experience with large-scale data processing and data engineering solutions.
• Strong problem-solving and communication skills.
📩 Interested candidates can share their updated resumes:
📧 pavithra.e @vysystems. com
📞 8 9 2 5 8 0 2 4 5 7
🔄 Know someone who would be a good fit? Tag them or share this post!
#Hiring #DataEngineer #DataEngineering #AmazonEMR #Python #Scala #AWSJobs #BangaloreJobs #ITJobs #TechHiring #HiringNow













 Follow Cutshort
Shubham Vishwakarma
Full Stack Developer - Averlon