
Senior DevOps at Numerator · Remote, Pune · 5 - 10 years · ₹10L - ₹30L / yr · Profitable · Remote friendly · Posted 7 Jan 2022
 Kubernetes
 Docker
 Amazon Web Services (AWS)
|
This role requires a balance between hands-on infrastructure-as-code deployments as well as involvement in operational architecture and technology advocacy initiatives across the Numerator portfolio.
Responsibilities
|
|
|
|
Technical Skills
|


Shubham Vishwakarma
Full Stack Developer - Averlon


About Numerator
About
Numerator backed by Vista Equity Partners is a Data-Tech company reinventing Market Research. Headquartered in Chicago, USA, Numerator has more than 1,600 employees worldwide. We blend proprietary data with advanced technology and elite services to create unique insights in a market research industry that has been slow to change. The majority of Fortune 100 companies are Numerator clients.
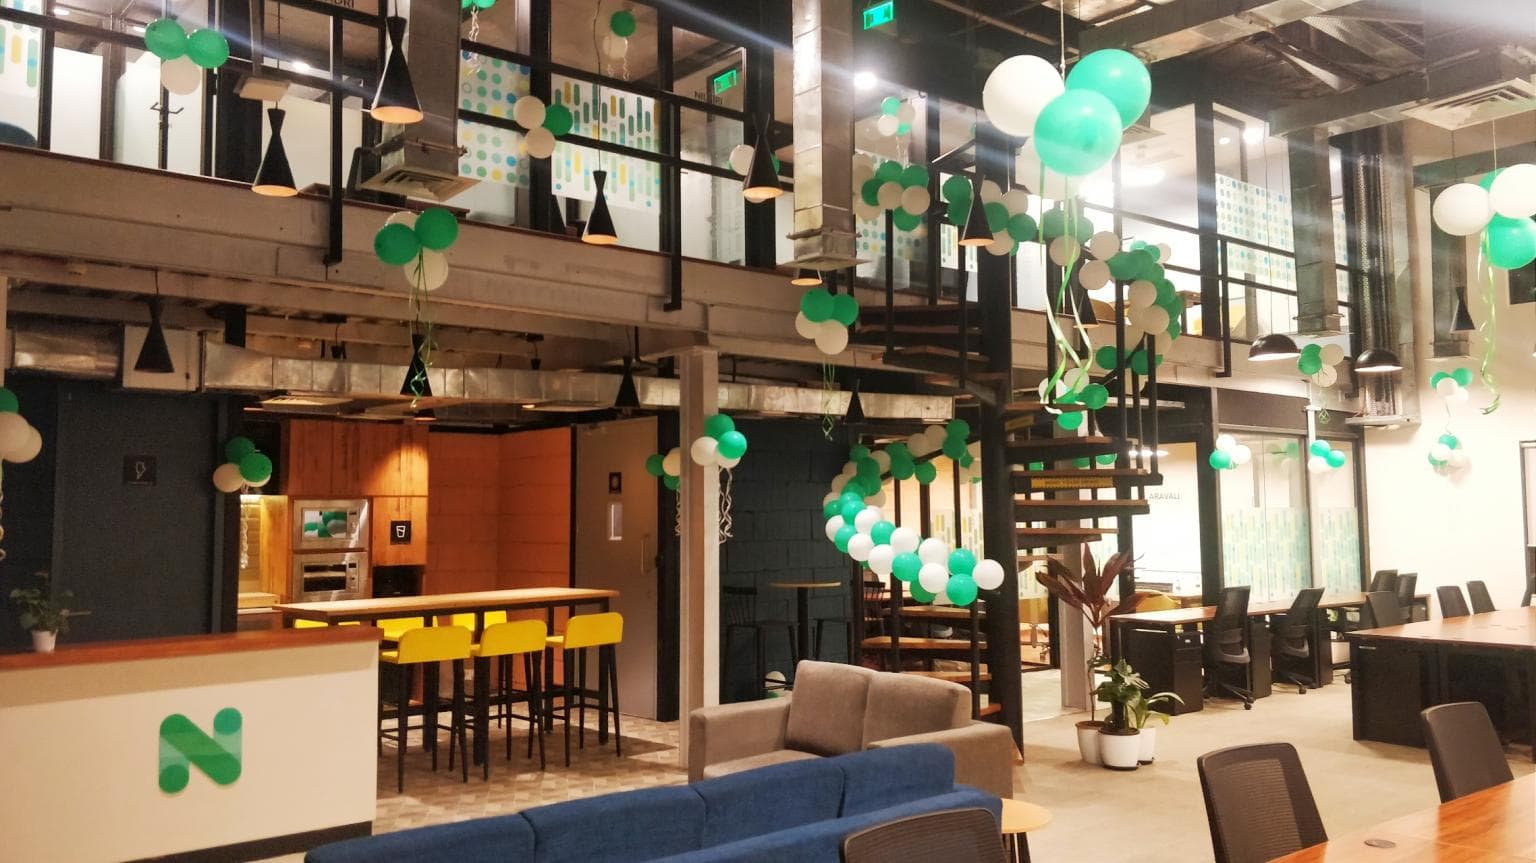
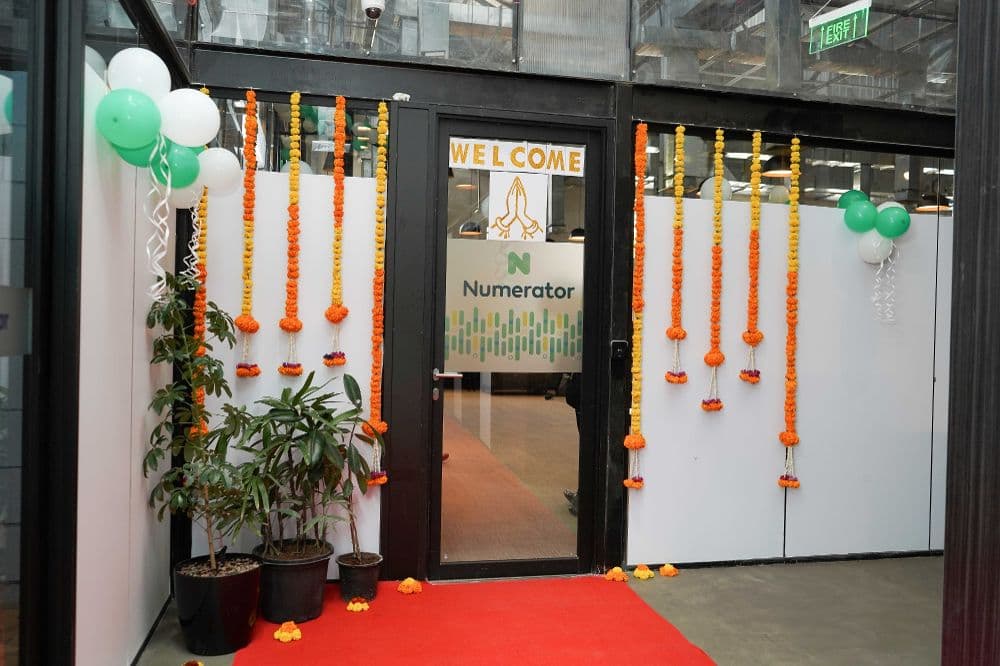
Photos




Company social profiles


Similar jobs (10)

Job Title : DevOps Engineer – Linux, AWS & Infrastructure
Experience : 3+ Years
Location : Sector 48, Gurgaon
Work Mode : 6 Days WFO – Monday to Saturday
Week Off : 01st & 03rd Saturday Off
Employment Type : Full-Time
Job Summary :
We are looking for a DevOps Engineer with strong hands-on experience in Linux, Networking, Server Administration, AWS, CI/CD, Containers, Kubernetes, and Infrastructure Automation. The ideal candidate should have strong troubleshooting skills, production ownership, and the ability to manage and automate infrastructure reliably.
Key Responsibilities :
- Manage and troubleshoot Linux servers, bare-metal infrastructure, and server environments.
- Perform system administration, networking, performance monitoring, and production troubleshooting.
- Design, maintain, and optimize Jenkins-based CI/CD pipelines and deployment workflows.
- Manage Docker containers and Kubernetes environments.
- Work with AWS Cloud services, infrastructure, security, and deployment environments.
- Monitor system health, application performance, logs, and infrastructure using appropriate monitoring and logging tools.
- Implement and maintain Infrastructure as Code (IaC) using tools such as Terraform or CloudFormation.
- Automate repetitive operational tasks using Python, Bash, Shell scripting, or similar technologies.
- Implement infrastructure and application security, access controls, patching, and hardening.
- Investigate production incidents, perform root-cause analysis (RCA), and drive issues to resolution.
- Take end-to-end ownership of infrastructure reliability, availability, and operational issues.
- Collaborate with development and other engineering teams to improve deployment, scalability, and system reliability.
Mandatory Skills :
Linux & Networking | Bare Metal / Server Administration | Jenkins / CI-CD | Docker / Containers | AWS Cloud | Kubernetes | Git | Monitoring & Logging | Security | Infrastructure as Code (IaC) | Automation / Scripting | Production Troubleshooting & Ownership
Preferred Skills :
- Strong understanding of TCP/IP, DNS, HTTP/HTTPS, SSH, load balancing, and networking fundamentals.
- Hands-on experience with Terraform / CloudFormation.
- Experience with Prometheus, Grafana, ELK / EFK, CloudWatch, or similar monitoring / logging tools.
- Good understanding of Linux performance troubleshooting, processes, memory, disk, networking, and file systems.
- Experience handling production incidents, RCA, deployments, and system reliability.
- Exposure to cloud security, IAM, secrets management, and server hardening.
What We’re Looking For :
- 3+ years of hands-on experience in DevOps / SRE / Infrastructure Engineering.
- Strong practical knowledge rather than certification-based/theoretical understanding.
- Good troubleshooting and analytical skills.
- Strong sense of ownership and accountability for production systems.
- Comfortable working in a 6-day work-from-office environment.
KubernetesDockerAmazon Web Services (AWS)• Support software build and release efforts:
• Create, set up, and maintain builds
• Review build results and resolve build problems
• Create and Maintain build servers
• Plan, manage, and control product releases
• Validate, archive, and escrow product releases
• Maintain and administer configuration management tools, including source control, defect management, project management, and other systems.
• Develop scripts and programs to automate process and integrate tools.
• Resolve help desk requests from worldwide product development staff.
• Participate in team and process improvement projects.
• Interact with product development teams to plan and implement tool and build improvements.
• Perform other duties as assigned.
While the job description describes what is anticipated as the requirements of the position, the job requirements are subject to change based upon any changing needs and requirements of the business.
Required Skills
• TFS 2017 vNext Builds or AzureDevOps Builds Process
• Must to have PowerShell 3.0+ Scripting knowledge
• Exposure on Build Tools like MSbuild, NANT, XCode.
• Exposure on Creating and Maintaining vCenter/VMware vSphere 6.5
• Hands On experiences on above Win2k12 OS and basic info on MacOS
• Good to have Shell or Batch Script (optional)
Required Experience
Candidates for this position should hold the following qualifications to be considered as a suitable applicant. Please note that except where specified as “preferred,” or as a “plus,” all points listed below are considered minimum requirements.
• Bachelors Degree in a related discipline is strongly preferred
• 3 or more years experience with Software Configuration Management tools, concepts, and processes.
• Exposure to Source control systems such as TFS, GIT, or Subversion (Optional)
• Familiarity with object-oriented concepts and programming in C# and Power Shell Scripting.
• Experience working on AzureDevOps Builds or vNext Builds or Jenkins Builds
• Experience working with developers to resolve development issues related to source control systems.
 PythonKubernetes
JOB DETAILS:
- Job Title: Senior Devops Engineer 1
- Industry: Ride-hailing
- Experience: 4-6 years
- Working Days: 5 days/week
- Work Mode: ONSITE
- Job Location: Bangalore
- CTC Range: Best in Industry
Required Skills: Cloud & Infrastructure Operations, Kubernetes & Container Orchestration, Monitoring, Reliability & Observability, Proficiency with Terraform, Ansible etc., Strong problem-solving skills with scripting (Python/Go/Shell)
Criteria:
1. Candidate must be from a product-based or scalable app-based startups company with experience handling large-scale production traffic.
2. Candidate must have strong Linux expertise with hands-on production troubleshooting and working knowledge of databases and middleware (Mongo, Redis, Cassandra, Elasticsearch, Kafka).
3. Candidate must have solid experience with Kubernetes.
4. Candidate should have strong knowledge of configuration management tools like Ansible, Terraform, and Chef / Puppet. Add on- Prometheus & Grafana etc.
5. Candidate must be an individual contributor with strong ownership.
6. Candidate must have hands-on experience with DATABASE MIGRATIONS and observability tools such as Prometheus and Grafana.
7. Candidate must have working knowledge of Go/Python and Java.
8. Candidate should have working experience on Cloud platform - AWS
9. Candidate should have Minimum 1.5 years stability per organization, and a clear reason for relocation.
Description
Job Summary:
As a DevOps Engineer at company, you will be working on building and operating infrastructure at scale, designing and implementing a variety of tools to enable product teams to build and deploy their services independently, improving observability across the board, and designing for security, resiliency, availability, and stability. If the prospect of ensuring system reliability at scale and exploring cutting-edge technology to solve problems, excites you, then this is your fit.
Job Responsibilities:
- Own end-to-end infrastructure right from non-prod to prod environment including self-managed DBs.
- Understanding the needs of stakeholders and conveying this to developers.
- Working on ways to automate and improve development and release processes.
- Identifying technical problems and developing software updates and ‘fixes’.
- Working with software developers to ensure that development follows established processes and works as intended.
- Do what it takes to keep the uptime above 99.99%.
- Understand DevOps philosophy and evangelize the principles across the organization.
- Strong communication and collaboration skills to break down the silos
Job Requirements:
- B.Tech. / B.E. degree in Computer Science or equivalent software engineering degree/experience.
- Minimum 4 yrs of experience working as a DevOps/Infrastructure Consultant.
- Strong background in operating systems like Linux.
- Understands the container orchestration tool Kubernetes.
- Proficient Knowledge of configuration management tools like Ansible, Terraform, and Chef / Puppet. Add on- Prometheus & Grafana etc.
- Problem-solving attitude, and ability to write scripts using any scripting language.
- Understanding programming languages like GO/Python, and Java.
- Basic understanding of databases and middlewares like Mongo/Redis/Cassandra/Elasticsearch/Kafka.
- Should be able to take ownership of tasks, and must be responsible. - Good communication skills
 Amazon Web Services (AWS)
 JenkinsKubernetes
Why this role exists
Our infrastructure footprint is growing faster than our headcount, and we believe most of that
gap should be closed by automation and AI agents — not by hiring more humans to do toil. We
need someone early in their career who treats manual work as a bug, ships scripts and agents
instead of tickets, and wants to grow into deeper ownership over the next two years.
You will not be the most senior person on the team. You will be the one who multiplies the team.
What you'll own
In your first 1 months
• Take ownership of one slice of our CI/CD pipeline and make it measurably
faster, more reliable, or cheaper. We expect a number on a dashboard to move.
• Build at least three internal automations that replace manual ops toil —
using AI agents (Claude Code, agentic CLIs, scripted LLM workflows) as your force
multiplier.
• Be the first responder for a defined set of alerts. Write the runbooks. Drive
the alert volume down.
• Support senior engineers on AI/ML infrastructure (GPU nodes, inference
services, model deployment) — observe, document, and gradually take on contained
changes under review.
By 3 months you should be
• The go-to person for at least two production systems.
• Shipping routine infrastructure changes without needing senior review.
• Treating "manual" as a code smell.
Required (we will reject without these)
• 0–3 years hands-on experience with one major cloud (AWS, GCP, or
Azure — one is fine, depth beats breadth).
• Fluent in Linux command line, bash, and at least one scripting language
(Python or Go preferred).
• Have shipped something to production that real users hit. A side project
counts; a graded coursework lab does not.
• Comfortable with Docker — you can explain what an image vs. a
container is and why it matters.
• Working knowledge of networking fundamentals: DNS, HTTP/HTTPS,
TLS, ports, basic subnets — enough to debug "it works on my machine."
• Git fluency: branches, merges, rebases, conflict resolution.
• CI/CD pipelines — you have authored or substantially modified pipelines
in GitHub Actions, GitLab CI, ArgoCD, Jenkins, or similar. Not just "I clicked Re-run."
• Kubernetes basics — kubectl for real work, can read pod logs,
understand deployments and services, can debug a CrashLoopBackOff without
panicking. You do not need to have run a cluster; you do need to have lived inside one.
• Active user of AI coding agents (Claude Code, Cursor, Copilot, agentic
CLIs, etc.). You should be able to walk us through specific tasks where they made you
faster, and specific tasks where they failed you and how you noticed. "I have tried it" is
not enough.
Bonus (real plus, not required)
• Infrastructure as Code: Terraform, Pulumi, or Ansible.
• Observability: Prometheus/Grafana, Datadog, OpenTelemetry, any APM.
• Have built or extended an LLM-based agent — a custom MCP server, a
scripted multi-step workflow, an internal tool that calls models in a loop. Anything beyond
chat-with-Claude.
• Exposure to GPU workloads, model serving (vLLM, Triton, TGI, etc.), or
ML pipelines.
What we don't care about
• Whether your degree is in CS — or whether you have a degree at all.
• Brand-name companies on your resume.
• Certifications. They are fine. They do not substitute for having shipped.
How we work
• We default to automation. If you do something manually twice, the third
time you script it or hand it to an agent.
• AI agents are part of the workflow, not a novelty. Expect interview
questions about exactly how you use them — and where you have caught them being
wrong.
• Small, reversible changes beat big-bang rollouts.
• Postmortems are blameless and written down.
• We push back on each other. If you only execute, you will be unhappy
here.
How to apply
Send:
• Your resume.
• A short note (≤200 words) describing one infra or automation problem you
solved, and how AI agents factored in — or did not, and why. We read these. Generic
notes get rejected.
Internal note — delete before posting externally
• Comp band, location policy, team name, and reporting line marked
[CONFIRM] need to be filled in before this goes external.
• The Required list is intentionally tight: CI/CD and Kubernetes basics
promoted from bonus. Expect this to filter ~80% of typical junior DevOps applicants. The
remaining pool will skew toward people who have actually shipped infra at a startup, not
bootcamp grads or pure cloud-cert holders.
• IaC, observability, agent-building, and GPU/ML serving stay as bonus.
Promoting any of these to required at 0–3 yrs collapses the pool to near-zero or forces
hiring senior people at junior comp. If you want IaC required, re-level this to mid (3–5
yrs) and raise the band.
• Screening implication: the resume screen should explicitly check for
CI/CD pipeline authorship and any K8s-touching production work. If neither is on the
resume, reject at screen. Do not waste interview slots.
• Pipeline watch: if fewer than ~15 qualified resumes after 2 weeks of
active sourcing, the first thing to relax is the AI-agent-fluency bar (move to bonus and
screen for it in interview instead). Do not relax the "shipped to production" requirement
— that is the load-bearing filter.
 DockerKubernetesAmazon Web Services (AWS)Jenkins
DevOps Lead Engineer
We are seeking a skilled DevOps Lead Engineer with 8 to 10 yrs. of experience who handles the entire DevOps lifecycle and is accountable for the implementation of the process. A DevOps Lead Engineer is liable for automating all the manual tasks for developing and deploying code and data to implement continuous deployment and continuous integration frameworks. They are also held responsible for maintaining high availability of production and non-production work environments.
Essential Requirements (must have):
• Bachelor's degree preferable in Engineering.
• Solid 5+ experience with AWS, DevOps, and related technologies
Skills Required:
Cloud Performance Engineering
• Performance scaling in a Micro-Services environment
• Horizontal scaling architecture
• Containerization (such as Dockers) & Deployment
• Container Orchestration (such as Kubernetes) & Scaling
DevOps Automation
• End to end release automation.
• Solid Experience in DevOps tools like GIT, Jenkins, Docker, Kubernetes, Terraform, Ansible, CFN etc.
• Solid experience in Infra Automation (Infrastructure as Code), Deployment, and Implementation.
• Candidates must possess experience in using Linux, Jenkins, and ample experience in Configuring and automating the monitoring tools.
• Strong scripting knowledge
• Strong analytical and problem-solving skills.
• Cloud and On-prem deployments
Infrastructure Design & Provisioning
• Infra provisioning.
• Infrastructure Sizing
• Infra Cost Optimization
• Infra security
• Infra monitoring & site reliability.
Job Responsibilities:
• Responsible for creating software deployment strategies that are essential for the successful
deployment of software in the work environment and provide stable environment for delivery of
quality.
• The DevOps Lead Engineer is accountable for designing, building, configuring, and optimizing
automation systems that help to execute business web and data infrastructure platforms.
• The DevOps Lead Engineer is involved in creating technology infrastructure, automation tools,
and maintaining configuration management.
• The Lead DevOps Engineer oversees and leads the activities of the DevOps team. They are
accountable for conducting training sessions for the juniors in the team, mentoring, career
support. They are also answerable for the architecture and technical leadership of the complete
DevOps infrastructure.
DockerKubernetesAmazon Web Services (AWS)Our client is a call management solutions company, which helps small to mid-sized businesses use its virtual call center to manage customer calls and queries. It is an AI and cloud-based call operating facility that is affordable as well as feature-optimized. The advanced features offered like call recording, IVR, toll-free numbers, call tracking, etc are based on automation and enhances the call handling quality and process, for each client as per their requirements. They service over 6,000 business clients including large accounts like Flipkart and Uber.
- Beng involved in Configuration Management, Web Services Architectures, DevOps Implementation, Build & Release Management, Database management, Backups, and Monitoring.
- Creating and managing CI/ CD pipelines for microservice architectures.
- Creating and managing application configuration.
- Researching and planning architectures and tools for smooth deployments.
- Logging, metrics and alerting management.
What you need to have:
- Proficient in Linux Commands line and troubleshooting.
- Proficient in designing CI/ CD pipelines using jenkins. Experience in deployment using Ansible.
- Experience in microservices architecture deployment, Hands-on experience on Docker, Kubernetes, EKS.
- Knowledge of infrastructure management tools (Infrastructure as cloud) such as terraform, AWS cloudformation etc.
- Proficient in AWS Services. Deployment, Monitoring and troubleshooting applications in AWS.
- Configuration management tools like ansible/chef/puppet.
- Proficient in deployment of applications behind load balancers and proxy servers such as nginx, apache.
- Proficient in bash scripting, python scripting is an advantage.
- Experience with Logging, Monitoring, and Alerting tools like ELK(Elastic-search, Logstash, Kibana), Nagios. Graylog, splunk Prometheus, Grafana is a plus.
- Proficient in Configuration Management.
 KubernetesDockerAmazon Web Services (AWS)
Experience and Education
• Bachelor’s degree in engineering or equivalent.
Work experience
• 4+ years of infrastructure and operations management
Experience at a global scale.
• 4+ years of experience in operations management, including monitoring, configuration management, automation, backup, and recovery.
• Broad experience in the data center, networking, storage, server, Linux, and cloud technologies.
• Broad knowledge of release engineering: build, integration, deployment, and provisioning, including familiarity with different upgrade models.
• Demonstratable experience with executing, or being involved of, a complete end-to-end project lifecycle.
Skills
• Excellent communication and teamwork skills – both oral and written.
• Skilled at collaborating effectively with both Operations and Engineering teams.
• Process and documentation oriented.
• Attention to details. Excellent problem-solving skills.
• Ability to simplify complex situations and lead calmly through periods of crisis.
• Experience implementing and optimizing operational processes.
• Ability to lead small teams: provide technical direction, prioritize tasks to achieve goals, identify dependencies, report on progress.
Technical Skills
• Strong fluency in Linux environments is a must.
• Good SQL skills.
• Demonstratable scripting/programming skills (bash, python, ruby, or go) and the ability to develop custom tool integrations between multiple systems using their published API’s / CLI’s.
• L3, load balancer, routing, and VPN configuration.
• Kubernetes configuration and management.
• Expertise using version control systems such as Git.
• Configuration and maintenance of database technologies such as Cassandra, MariaDB, Elastic.
• Designing and configuration of open-source monitoring systems such as Nagios, Grafana, or Prometheus.
• Designing and configuration of log pipeline technologies such as ELK (Elastic Search Logstash Kibana), FluentD, GROK, rsyslog, Google Stackdriver.
• Using and writing modules for Infrastructure as Code tools such as Ansible, Terraform, helm, customize.
• Strong understanding of virtualization and containerization technologies such as VMware, Docker, and Kubernetes.
• Specific experience with Google Cloud Platform or Amazon EC2 deployments and virtual machines.c
 Amazon Web Services (AWS)
- AWS Cloud, CICD, Serverless setups, Monitoring Setup
- Performance setup, scalability in hands experience, Linux expertise, DevOps Operations
- AWS Cloud, CICD, Serverless setups, Monitoring Setup, Performance setup, scalability in hands experience, Linux expertise, DevOps Operations.
Amazon Web Services (AWS)DockerKubernetesSkills:
- Strong working knowledge of AWS.
- Implements AWS cloud platform.
- Infrastructure as Code, GitLab CI/CD, and DevOps standard methodologies
- scripting in Shell, Python, Ruby or any preferred scripting language
Terraform expertise is a MUST for this role.
a short exercise on terraform to all shortlisted candidates to demonstrate their hands-on skills on terraform before rolling out the offer
Desired Profile
Providing expertise on all matters related to CI, CD and DevOps.
Building and maintaining highly available production systems.
Developing and maintaining release related documents, such as release plan, release notes etc.
Ensuring quality releases and managing release and configuration change conflicts to resolution.
Tracking release and publishing release notes. Investigating and resolving technical issues by deploying updates/ fixes.
Onboard applications to DevOps process.
Setup and configure build jobs.
Create automated deployment scripts.
Configure JIRA workflow, and integrate with Jenkins / Micro-services.
Qualification
Degree/Diploma in Computer Science, Engineering or related field and have previous experience as a DevOps Engineer.
AWS Certification will be a plus.
Experience of automation and provisioning approaches, using tools such as Terraform & Cloud Formation
Skillset Required
Solid experience within release management, infra architecture, CI&CD.
Highly goal driven and work well in fast paced environments.
Proven experience of using Jenkins, Unix Shell Commands, Container technology (Docker, Kubernetes),
Java Programming, Groovy Script, Git, Code Branching Strategy, Maven, Gradle, JIRA, ECS, OpenShift.
Amazon Web Services (AWS)We are looking for an experienced DevOps engineer that will help our team establish DevOps practice. You will work closely with the technical lead to identify and establish DevOps practices in the company. You will also help us build scalable, efficient cloud infrastructure. You’ll implement monitoring for automated system health checks. Lastly, you’ll build our CI pipeline, and train and guide the team in DevOps practices.
Responsibilities
- Deployment, automation, management, and maintenance of production systems.
- Ensuring availability, performance, security, and scalability of production systems.
- Evaluation of new technology alternatives and vendor products.
- System troubleshooting and problem resolution across various application domains and platforms.
- Providing recommendations for architecture and process improvements.
- Definition and deployment of systems for metrics, logging, and monitoring on the AWS
platform.
- Manage the establishment and configuration of SaaS infrastructure in an agile way
by storing infrastructure as code and employing automated configuration management tools with a goal to be able to re-provision environments at any point in time.
- Be accountable for proper backup and disaster recovery procedures.
- Drive operational cost reductions through service optimizations and demand-based
auto-scaling.
- Have on-call responsibilities.
- Perform root cause analysis for production errors
- Uses open source technologies and tools to accomplish specific use cases encountered
within the project.
- Uses coding languages or scripting methodologies to solve a problem with a custom workflow.
Requirements
- Systematic problem-solving approach, coupled with strong communication skills and a sense of ownership and drive.
- Prior experience as a software developer in a couple of high-level programming
languages.
- Extensive experience in any Javascript-based framework since we will be deploying services to NodeJS on AWS Lambda (Serverless)
- Strong Linux system administration background.
- Ability to present and communicate the architecture in a visual form.
- Strong knowledge of AWS (e.g. IAM, EC2, VPC, ELB, ALB, Autoscaling, Lambda, NAT
gateway, DynamoDB)
- Experience maintaining and deploying highly-available, fault-tolerant systems at scale (~
1 Lakh users a day)
- A drive towards automating repetitive tasks (e.g. scripting via Bash, Python, Ruby, etc)
- Expertise with Git
- Experience implementing CI/CD (e.g. Jenkins, TravisCI)
- Strong experience with databases such as MySQL, NoSQL, Elasticsearch, Redis and/or
Mongo.
- Stellar troubleshooting skills with the ability to spot issues before they become problems.
- Current with industry trends, IT ops and industry best practices, and able to identify the
ones we should implement.
- Time and project management skills, with the capability to prioritize and multitask as
needed.













 Follow Cutshort
Shubham Vishwakarma
Full Stack Developer - Averlon