
DEVOPS Engineer at Tecstub · Ahmedabad · 3 - 15 years · ₹7L - ₹12L / yr · Profitable · Posted 23 Aug 2023

 Amazon Web Services (AWS)
 Docker
 Kubernetes
Job Description
Role Overview:
We're looking for a passionate DevOps engineer with a minimum of 10 years’ experience across all levels, who will work closely with the development teams in Agile setup to continuously improve, support, secure, and operate our production and test environments. We believe in automating our infrastructure as much as possible and pursuing challenging problems in a sustainable and repeatable way.
Our Toolchain
- Ansible, Docker, Kubernetes, Terraform, Gitlab, Jenkins, Fastlane, New Relic, Datadog, SonarQube, IaC
- Apache, Nginx, Linux, Ubuntu, Microservices, Python, Shell, Bash, Helm
- Selenium, Jmeter, Slack, Jira, SAST, OSSEC, OWASP
- Node.JS, PHP, Golang, MySQL, MongoDB, Firebase, Redis, Elastic search,
- VPC, API Gateway, Cognito, DocumentDB, ECS, Lambda, Route53, ACM, S3, EC2, IAM
You'll need:
- Production experience with distributed/scalable systems consisting of multiple microservices and/or high-traffic web applications
- Experience with configuration management systems such as Ansible, Chef, Puppet
- Extensive knowledge of the Linux operating system
- Troubleshooting skills that range from diagnosis to solution for Dev team issues
- Knowledge of how the web works and HTTP fundamentals
- Knowledge of IP networking, DNS, load balancing, and firewalling
Bonus points, if you have:
- Experience in agile development and delivery process.
- Good knowledge of at least one programming language. TecStub uses e.g. Nodes, PHP
- Experience in containerizing applications and deployment to production (Docker, Kubernetes)
- Experience in building modern Terraform infrastructures in cloud environments (AWS, GCP, etc...)
- Experience in analysis of application and database performance monitoring tools (Newrelic, datalog, cluster control, etc..)
- Experience with SQL databases like MySQL, NoSQL, Realtime database stores like Redis, or anything in between.
- Experience being part of the engineering team that built the platform.
- Knowledge of good security practices, including network security, system hardening, secure software, and compliance.
- Familiarity with automated build pipeline / continuous integration using Gitlab and Jenkins and Kubernetes/Docker with this setup, we're deploying to production 2 times per day!
Interview Process:
The entire interview process would take approximately 10 Days.
- HR Screening Call (15 minutes)
- Technical Interview Round Level 1 (30 Minutes)
- Technical Interview Round Level 2 (60 minutes)
- Final Interview Round (60 minutes)
- Offer
About Tecstub:
Tecstub is a renowned global provider of comprehensive digital commerce solutions for some of the world's largest enterprises. With offices in North America and Asia-Pacific, our team offers end-to-end solutions such as strategic Solution Consulting, eCommerce website and application development, and support & maintenance services that are tailored to meet our clients' unique business goals. We are dedicated to delivering excellence by working as an extended partner, providing next-generation solutions that are sustainable, scalable, and future-proof. Our passionate and driven team of professionals has over a decade of experience in the industry and is committed to helping our clients stay ahead of the competition.
We value our employees and strive to create a positive work environment that promotes work-life balance and personal growth. As part of our commitment to our team, we offer a range of benefits to ensure our employees are supported and motivated.
- A 5-day work week that promotes work-life balance and allows our employees to take care of personal responsibilities while excelling in their professional roles.
- 30 annual paid leaves that can be utilized for various personal reasons, such as regional holidays, sick leaves, or any other personal needs. We believe that taking time off is essential for overall well-being and productivity.
- Additional special leaves for birthdays, maternity and paternity events to ensure that our employees can prioritize their personal milestones without any added stress.
- Health insurance coverage of 3 lakhs sum insured for our employees, spouse, and children, to provide peace of mind and security for their health needs.
- Vouchers and gifts for important life events such as birthdays and anniversaries, to celebrate our employees' milestones and show appreciation for their contributions to the company.
- A dedicated learning and growth budget for courses and certifications, to support our employees' career aspirations and encourage professional development.
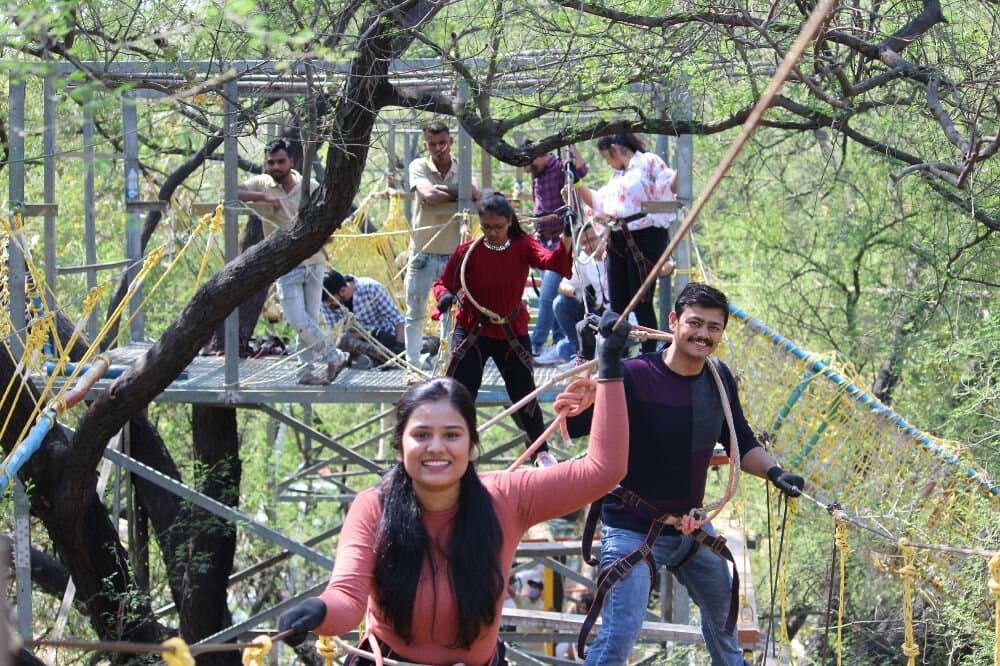
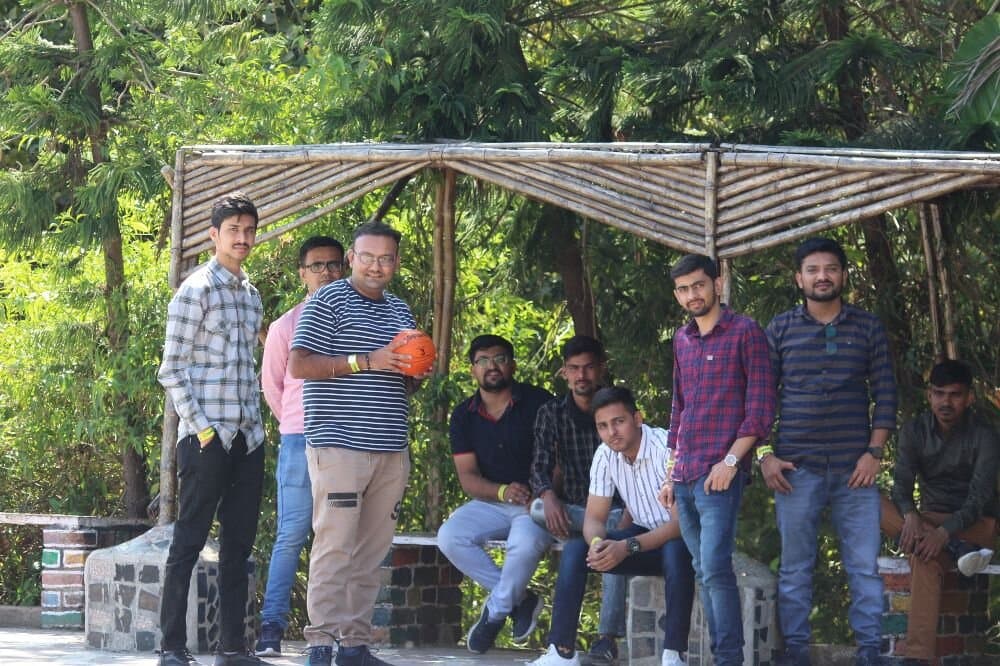
- Company outings to celebrate our successes together and promote a sense of camaraderie among our team members. We believe that celebrating achievements is an important part of building a positive work culture.
Skills
AWS, Terraform, KUBERNETES, GITHUB, APACHE, BASH, DOCKER, ANSIBLE, GIT, Microservices, UBUNTU, GITLAB, CI/CD, APACHE SERVER, NGINX, NODEJS


Shubham Vishwakarma
Full Stack Developer - Averlon


About Tecstub
About
We are an IT consulting firm founded in 2014, providing digital commerce solutions to global enterprises. Our experts leverage their extensive experience and technical expertise to help businesses navigate the ever-evolving digital landscape. From strategy to implementation to post-development support and maintenance, we are dedicated to delivering results that drive success in the digital marketplace.
A team of over 50+ technology enthusiasts with a shared passion for innovation and excellence. We attribute our success to our unique work culture and commitment to incorporating the latest technology stack to meet.
Join us on our journey of reshaping the digital commerce industry.
Photos

Company social profiles


Similar jobs (10)

We are seeking an experienced Senior Systems Operations Engineer with 6+ years of experience in Application Production Support, Systems Operations, and Incident Management. The ideal candidate will be responsible for maintaining the stability, availability, and performance of production applications and infrastructure while ensuring adherence to ITIL processes and operational excellence.
The candidate should possess strong expertise in Linux/Unix administration, SQL/Oracle Database support, Production Issue Analysis, Incident & Change Management, and monitoring tools such as Splunk, Grafana, and AppDynamics. The role requires excellent troubleshooting skills, stakeholder communication, and the ability to lead critical incident resolution activities in a 16X7 production environment.
Key Responsibilities:
• Provide advanced production support for critical business applications, ensuring high availability and performance.
• Lead incident and change management processes, including root cause analysis and resolution of production issues.
• Monitor application health using tools such as SPLUNK, Grafana, and AppDynamics.
• Collaborate with development, infrastructure, and business teams to drive continuous improvement in system operations.
• Maintain and optimize Linux/Unix environments and SQL/Oracle databases.
• Document operational procedures, troubleshooting steps, and best practices.
Required Skills:
• Strong experience with Linux/Unix system administration.
• Advanced proficiency in SQL and Oracle database management.
• Expertise in incident and change management within enterprise environments.
• Proven ability to analyse and resolve production issues efficiently.
• Hands-on experience with monitoring and alerting tools: SPLUNK, Grafana, AppDynamics.
• Excellent communication and collaboration skills.
• Experience with cloud platforms (AWS, Azure, GCP)
Desired Candidate Profile
• 6+ years of experience in Application Production Support and Systems Operations.
• Proven experience managing mission-critical production environments.
• Strong expertise in Linux/Unix, SQL, Oracle Database, and monitoring tools.
• Demonstrated success in incident resolution, RCA preparation, and service improvement initiatives.
• Ability to work effectively in a fast-paced 16x7 production support environment.
• Exposure to AI tools and implementation as well
 Kubernetes
Principal DevOps Engineer
Note - Screening Requirement: Please note that this position requires a minimum of 8+ years of hands-on Architecting DevOps/SRE/Platform Engineering experience specializing in AWS, EKS/Kubernetes, Terraform, Python, Jenkins, and AI workflows (Mandatory skills) from scratch.
We are looking for an absolute builder who has a proven track record of personally architecting, designing and setting up production-grade AWS EKS clusters entirely from scratch. If your experience is primarily limited to managing, maintaining, or optimizing pre-existing environments that were already stood up by another team, this is not the right opportunity for you.
Who are we?
Securin is an AI-driven cybersecurity company focused on proactive, adversarial exposure and vulnerability management. Our mission is to help organizations reduce cyber risk by identifying, prioritising, and remediating the issues that matter most. Powered by a seasoned team of threat researchers and status as a Certified Naming Authority (CNA), Securin combines artificial intelligence / machine learning, threat intelligence, and deep vulnerability research (including the Dark Web) to deliver an adversarial approach to cyber defense. We help enterprises shift from reactive patching to strategic, risk-based exposure and vulnerability management – driving smarter security decisions and faster remediation.
What do we promise?
We are a highly effective tech-enabled cybersecurity solutions provider and promise continual security posture improvement, enhanced attack surface visibility, and proactive prioritized remediation for every one of our client businesses.
What do we provide?
● A chance to be on the leading edge of cybersecurity and AI
● Ability to have direct impact on company growth and revenue strategy
● An opportunity to mentor and be mentored by experts in multiple disciplines
What do we deliver?
Securin helps organizations to identify and remediate the most dangerous exposures, vulnerabilities, and risks in their environment. We deliver predictive and definitive intelligence and facilitate proactive remediation to help organizations stay a step ahead of attackers. By utilising our cybersecurity solutions, our clients can have a proactive and holistic view of their security posture and protect their assets from even the most advanced and dynamic attacks.
Securin has been recognized by national and international organizations for its role in accelerating innovation in offensive and proactive security. Our combination of domain expertise, cutting-edge technology, and advanced tech-enabled cybersecurity solutions has made Securin a leader in the industry.
Core Technology Stack
AWS , EKS / Kubernetes, Jenkins , Python ,Terraform ,CI/CD , AI
Key Responsibilities:
● Architect and manage the end-to-end SaaS platform infrastructure on AWS, including EKS cluster design, VPC networking, IAM, and multi-region availability.
● Build, maintain, and optimize Jenkins-based CI/CD pipelines and develop Python automation scripts for provisioning, deployments, and runbook automation.
● Define and enforce platform SLOs/SLAs; own the observability strategy across logging, metrics, and tracing.
● Manage and participate in the on-call rotation; act as escalation point for P1/P2 incidents and drive post-incident reviews.
● Drive Infrastructure-as-Code (IaC) practices with Terraform/CloudFormation and champions a culture of automation and operational excellence.
● Collaborate cross-functionally with product, security, and engineering teams to align infrastructure roadmap with business goals.
● Identify opportunities to leverage AI to automate operational and DevOps workflows.
● Design and implement AI-assisted solutions for incident triaging, root cause analysis, log analysis, and performance optimization.
● Drive the adoption of AI-powered tools for infrastructure management, deployment automation, monitoring, and troubleshooting.
● Build intelligent workflows that reduce manual effort in release management, capacity planning, and operational support.
● Integrate AI capabilities into CI/CD pipelines to improve code quality, deployment reliability, and operational efficiency.
● Collaborate with engineering teams to automate repetitive tasks and improve developer productivity.
● Define best practices and governance for the safe and effective use of AI across DevOps processes.
● Measure and report on productivity gains, operational improvements, and cost savings achieved through AI adoption.
Requirements:
● 8+ years of experience in DevOps, SRE, or cloud infrastructure engineering roles.
● Deep hands-on expertise with AWS services (EC2, EKS, RDS, S3, IAM, VPC, CloudFront, Route53, Lambda, etc).
● Strong Kubernetes experience: cluster management, Helm, autoscaling (HPA/KEDA).
● Proficiency with Jenkins for complex CI/CD pipeline design and maintenance.
● Solid Python scripting skills for automation, tooling, and infrastructure management tasks.
● Experience with Infrastructure-as-Code using Terraform and/or AWS Cloud Formation.
● Proven track record of architecting and managing end-to-end SaaS products in a cloud-native environment.
● Strong understanding of networking fundamentals, security best practices, and compliance frameworks (SOC 2, ISO 27001 a plus).
● Hands-on experience with on-call processes and incident management frameworks.
Preferred Qualifications:
● AWS certifications: Solutions Architect Professional, DevOps Engineer Professional, or equivalent.
● Familiarity with service mesh, secrets management (Vault, AWS Secrets Manager), and zero-trust security models.
● Experience with multi-tenant SaaS architectures and tenant isolation strategies.
● Knowledge of FinOps principles and AWS cost management tooling.
● Experience with database DevOps: RDS, Aurora schema migrations, and backup strategies.
Core Competencies:
● Strategic Thinking – ability to translate business goals into scalable technical architecture.
● Operational Excellence – strong bias for reliability, automation, and continuous improvement.
● Communication – ability to clearly articulate complex technical topics to non-technical stakeholders.
● Ownership Mindset – proactively identifies and resolves risks without waiting to be asked.
● Resilience Under Pressure – calm and decisive during incidents; leads by example in high-stress situations.
Why should we connect?
We are a bunch of passionate cybersecurity professionals who are building a culture of security. Today, cybersecurity is no more a luxury but a necessity with a global market value of $150 billion.
At Securin, we live by a people-first approach. We firmly believe that our employees should enjoy what they do. For our employees, we provide a hybrid work environment with competitive best-in-industry pay, while providing them with an environment to learn, thrive, and grow. Our hybrid working environment allows employees to work from the comfort of their homes or the office if they choose to. For the right candidate, this will feel like your second home.
If you are passionate about cybersecurity just as we are, we would love to connect and share ideas
 Amazon Web Services (AWS)
Location: Bangalore
Experience: 2–5 years
Type: Full-time | On-site
Start: Immediate
Why this role exists
Most systems don’t fail because of one big outage.
They fail because reliability is treated as an afterthought.
Right now, uptime depends too much on individual heroics.
That doesn’t scale.
This role exists to build a reliability system where:
- Uptime is predictable
- Failures are contained
- Escalations don’t depend on leadership
What you’ll do
You will not just monitor systems.
You will own reliability as a product.
1. Drive uptime to production-grade reliability
- Improve system uptime to 99.9% customer-facing SLA within 4 months
- Define and track:
- SLAs / SLOs / error budgets
- Ensure reliability is measured from the customer’s perspective, not internal metrics
2. Build incident response as a system
- Set up a 24/7 incident response rotation across 3 engineers
- Eliminate dependency on leadership (no single escalation point)
- Define:
- Incident severity levels
- Response playbooks
- Escalation protocols
- Ensure fast detection → containment → resolution
3. Contain and fix erratic system behavior
- Identify and resolve:
- Latency spikes
- Downtime incidents
- Integration failures
- Build guardrails to prevent recurrence
- Focus on root cause elimination, not temporary fixes
4. Create continuous reliability feedback loops
- Work closely with engineering teams to:
- Surface recurring failure patterns
- Improve build quality
- Reduce production bugs
- Ensure learnings from incidents directly improve future releases
5. Improve observability and monitoring
- Build dashboards and alerts for:
- System health
- Performance metrics
- Failure signals
- Ensure issues are detected before customers report them
6. Reduce operational fragility
- Remove single points of failure (people, systems, workflows)
- Improve system resilience across:
- Deployments
- Integrations
- Runtime environments
What success looks like
- Uptime reaches 99.9%+ reliably
- Incidents are:
- Detected early
- Contained quickly
- Resolved permanently
- No dependency on a single individual for escalation
- System behavior becomes predictable and stable
- Engineering teams ship with higher reliability confidence
Who you are
- You have 2-5 years of experience in SRE / DevOps / backend systems
- You have worked on production systems with real uptime expectations
- You think in:
- Systems
- Failure modes
- Trade-offs
- You are comfortable debugging live, high-pressure environments
What will make you stand out
- Experience with:
- Distributed systems
- Cloud infrastructure (AWS / Azure / GCP)
- Monitoring & alerting tools
- Have built or improved:
- Incident response systems
- Reliability frameworks
- Strong debugging skills across:
- Infra
- Application
- Integrations
Compensation
₹60,000/month (fixed)
(Aligned with role scope and impact expectations)
Why join
- You will define reliability standards for a production AI platform
- Your work directly impacts:
- Customer trust
- Product performance
- Enterprise readiness
- You will move the system from reactive → predictable
What this role is not
- Not just monitoring dashboards
- Not limited to handling tickets
- Not dependent on escalation to leadership
What this role is
- A builder of reliability systems
- A guardian of uptime and performance
- A multiplier of engineering quality
One question to self-evaluate
Can you build a system where downtime is rare, predictable, and never dependent on a single person?
 Amazon Web Services (AWS)DockerKubernetes
- At least 5 year of experience in Cloud technologies-AWS and Azure and developing.
- Experience in implementing DevOps practices and DevOps-tools in areas like CI/CD using Jenkins environment automation, and release automation, virtualization, infra as a code or metrics tracking.
- Hands on experience in DevOps tools configuration in different environments.
- Strong knowledge of working with DevOps design patterns, processes and best practices
- Hand-on experience in Setting up Build pipelines.
- Prior working experience in system administration or architecture in Windows or Linux.
- Must have experience in GIT (BitBucket, GitHub, GitLab)
- Hands-on experience on Jenkins pipeline scripting.
- Hands-on knowledge in one scripting language (Nant, Perl, Python, Shell or PowerShell)
- Configuration level skills in tools like SonarQube (or similar tools) and Artifactory.
- Expertise on Virtual Infrastructure (VMWare or VirtualBox or QEMU or KVM or Vagrant) and environment automation/provisioning using SaltStack/Ansible/Puppet/Chef
- Deploying, automating, maintaining and managing Azure cloud based production systems including monitoring capacity.
- Good to have experience in migrating code repositories from one source control to another.
- Hands-on experience in Docker container and orchestration based deployments like Kubernetes, Service Fabric, Docker swarm.
- Must have good communication skills and problem solving skills
 DockerKubernetes
 Python
We are looking for people with programming skills in Python, SQL, Cloud Computing. Candidate should have experience in at least one of the major cloud-computing platforms - AWS/Azure/GCP. He should professioanl experience in handling applications and databases in the cloud using VMs and Docker images. He should have ability to design and develop applications for the cloud.
You will be responsible for
- Leading the DevOps strategy and development of SAAS Product Deployments
- Leading and mentoring other computer programmers.
- Evaluating student work and providing guidance in the online courses in programming and cloud computing.
Desired experience/skills
Qualifications: Graduate degree in Computer Science or related field, or equivalent experience.
Skills:
- Strong programming skills in Python, SQL,
- Cloud Computing
Experience:
2+ years of programming experience including Python, SQL, and Cloud Computing. Familiarity with command line working environment.
Note: A strong programming background, in any language and cloud computing platform is required. We are flexible about the degree of familiarity needed for the specific environments Python, SQL. If you have extensive experience in one of the cloud computing platforms and less in others you should still, consider applying.
Soft Skills:
- Good interpersonal, written, and verbal communication skills; including the ability to explain the concepts to others.
- A strong understanding of algorithms and data structures, and their performance characteristics.
- Awareness of and sensitivity to the educational goals of a multicultural population would also be desirable.
- Detail oriented and well organized.
 DockerAmazon Web Services (AWS)
- Proven experience in handling large infrastructure and distributed systems like Kafka, Yarn, Elastic Search, etc..
- Familiarity with Python-related technologies and frameworks like Django or Pyramid.
- Experience with Unix/Linux operating systems internals and administration (e.g. filesystems, inodes, system calls, etc) or networking (e.g. TCP/IP, routing, network topologies, and hardware, SDN, etc)
- Familiarity with at least one of the cloud computing infrastructures - GCP / Azure / AWS
- Familiarity with task queue frameworks like Celery or Pika is a plus.
- Source code management and Implementation of security best practices.
- Experienced in building monitoring/metrics & alerting tool (APM tool), a custom dashboard for each Application stack against the supported environment
- Good understanding & implementation experience using 12-factor App principles
- Awareness of Cloud Security concepts
- Awareness of Information Security concepts and Best Practices
 Amazon Web Services (AWS)
Technical Experience/Knowledge Needed :
- Cloud-hosted services environment.
- Proven ability to work in a Cloud-based environment.
- Ability to manage and maintain Cloud Infrastructure on AWS
- Must have strong experience in technologies such as Dockers, Kubernetes, Functions, etc.
- Knowledge in orchestration tools Ansible
- Experience with ELK Stack
- Strong knowledge in Micro Services, Container-based architecture and the corresponding deployment tools and techniques.
- Hands-on knowledge of implementing multi-staged CI / CD with tools like Jenkins and Git.
- Sound knowledge on tools like Kibana, Kafka, Grafana, Instana and so on.
- Proficient in bash Scripting Languages.
- Must have in-depth knowledge of Clustering, Load Balancing, High Availability and Disaster Recovery, Auto Scaling, etc.
-
AWS Certified Solutions Architect or/and Linux System Administrator
- Strong ability to work independently on complex issues
- Collaborate efficiently with internal experts to resolve customer issues quickly
- No objection to working night shifts as the production support team works on 24*7 basis. Hence, rotational shifts will be assigned to the candidates weekly to get equal opportunity to work in a day and night shifts. But if you get candidates willing to work the night shift on a need basis, discuss with us.
- Early Joining
- Willingness to work in Delhi NCR
DockerKubernetesAmazon Web Services (AWS)- 2+ years of demonstrable experience leading site reliability and performance in large-scale, high-traffic environments
- 2+ years of hands-on experience as a DevOps engineer
- Strong leadership, communication and interpersonal skills geared to getting things done
- Developing themselves and the talent within their charge – fostering and creating opportunity for the team
- Strong understanding of SRE concepts and the DevOps culture. Set the direction and strategy for your team, and help shape the overall SRE program for the company
- Be able to lead complicated technical issues and communicating status updates/RCA with management and customers.
- Own site stability, performance, capacity planning, DevOps recruitment.
 KubernetesDockerAmazon Web Services (AWS)
 Jenkins
- Solve complex Cloud Infrastructure problems.
- Drive DevOps culture in the organization by working with engineering and product teams.
- Be a trusted technical advisor to developers and help them architect scalable, robust, and highly-available systems.
- Frequently collaborate with developers to help them learn how to run and maintain systems in production.
- Drive a culture of CI/CD. Find bottlenecks in the software delivery pipeline. Fix bottlenecks with developers to help them deliver working software faster. Develop and maintain infrastructure solutions for automation, alerting, monitoring, and agility.
- Evaluate cutting edge technologies and build PoCs, feasibility reports, and implementation strategies.
- Work with engineering teams to identify and remove infrastructure bottlenecks enabling them to move fast. (In simple words you'll be a bridge between tech, operations & product)
Skills required:
Must have:
- Deep understanding of open source DevOps tools.
- Scripting experience in one or more among Python, Shell, Go, etc.
- Strong experience with AWS (EC2, S3, VPC, Security, Lambda, Cloud Formation, SQS, etc)
- Knowledge of distributed system deployment.
- Deployed and Orchestrated applications with Kubernetes.
- Implemented CI/CD for multiple applications.
- Setup monitoring and alert systems for services using ELK stack or similar.
- Knowledge of Ansible, Jenkins, Nginx.
- Worked with Queue based systems.
- Implemented batch jobs and automated recurring tasks.
- Implemented caching infrastructure and policies.
- Implemented central logging.
Good to have:
- Experience dealing with PI information security.
- Experience conducting internal Audits and assisting External Audits.
- Experience implementing solutions on-premise.
- Experience with blockchain.
- Experience with Private Cloud setup.
Required Experience:
- B.Tech. / B.E. degree in Computer Science or equivalent software engineering degree/experience.
- You need to have 2-4 years of DevOps & Automation experience.
- Need to have a deep understanding of AWS.
- Need to be an expert with Git or similar version control systems.
- Deep understanding of at least one open-source distributed systems (Kafka, Redis, etc)
- Ownership attitude is a must.
We offer a suite of memberships and subscriptions to spice up your lifestyle. We believe in practicing an ultimate work life balance and satisfaction. Working hard doesn’t mean clocking in extra hours, it means having a zeal to contribute the best of your talents. Our people culture helps us inculcate measures and benefits which help you feel confident and happy each and every day. Whether you’d like to skill up, go off the grid, attend your favourite events or be an epitome of fitness. We have you covered round and about.
- Health Memberships
- Sports Subscriptions
- Entertainment Subscriptions
- Key Conferences and Event Passes
- Learning Stipend
- Team Lunches and Parties
- Travel Reimbursements
- ESOPs
Thats what we think would bloom up your personal life, as a gesture for helping us with your talents.
Join us to be a part of our Exciting journey to Build one Digital Identity Platform!!!
Amazon Web Services (AWS)JenkinsRequirements
- Design, write and build tools to improve the reliability, latency, availability and scalability of HealthifyMe application.
- Communicate, collaborate and work effectively across distributed teams in a global environment
- Optimize performance and solve issues across the entire stack: hardware, software, application, and network.
- Experienced in building infrastructure with terraform / cloudformation or equivalent.
- Experience with ansible or equivalent is beneficial
- Ability to use a wide variety of Open Source Tools
- Experience with AWS is a must.
- Minimum 5 years of running services in a large scale environment.
- Expert level understanding of Linux servers, specifically RHEL/CentOS.
- Practical, proven knowledge of shell scripting and at least one higher-level language (eg. Python, Ruby, GoLang).
- Experience with source code and binary repositories, build tools, and CI/CD (Git, Artifactory, Jenkins, etc)
- Demonstrable knowledge of TCP/IP, HTTP, web application security, and experience supporting multi-tier web application architectures.
Look forward to
- Working with a world-class team.
- Fun & work at the same place with an amazing work culture and flexible timings.
- Get ready to transform yourself into a health junkie
Join HealthifyMe and make history!













 Follow Cutshort
Shubham Vishwakarma
Full Stack Developer - Averlon