
AI Engineer at Unico Connect Private Limited · Remote, Mumbai · 2 - 4 years · Profitable · Remote friendly · Posted 15 Sep 2026
 Python
AI Engineer
LLMs, Agents & AI Services
📍 Mumbai (On-site) | Full-time | 2-4 years
About the Role:
Unico Connect is an AI-first technology partner that builds custom mobile, web, and AI products for clients across multiple geographies.
AI is core to how we design, deliver, and scale software for our customers.
We are hiring an AI Engineer for a dedicated client engagement building a complex production AI platform, working on the AI capabilities and agentic features at the core of the product.
The mandatory requirement for this role is at least one AI feature personally shipped to production for real users, with operational ownership.
The role suits someone who thinks quickly on solutioning, can take an ambiguous problem to a working prototype in days, and has the discipline to carry it through to production with predictable economics.
You will work alongside the Senior AI Engineer and the wider pod, with ownership of parts of the AI surface area of the product.
Responsibilities:
Solutioning and POCs
Translate ambiguous customer problems into working POCs at speed.
Pick the right model, framework, and architecture, and demonstrate value early before scaling investment.
LLM Application Development
Build AI features and services using LLM APIs from OpenAI, Anthropic, Google, and self-hosted open-weight models (Llama, Qwen, Mistral).
Choose the right model per use case based on cost, latency, capability, and context-window trade-offs.
Agentic System Design
Design and implement agentic workflows using LangGraph, CrewAI, AutoGen, LlamaIndex Agents, or custom orchestration.
Cover tool use, planning, memory, and multi-step reasoning appropriate to the problem.
API and Service Development
Build production AI services and APIs using Python and FastAPI.
Handle streaming responses, async processing, structured outputs, retries, and graceful degradation when models or tools fail.
Retrieval and Tool Integration
Implement RAG pipelines with vector databases (Pinecone, Weaviate, Qdrant, pgvector, Chroma), embeddings, chunking strategies, hybrid search, and reranking.
Integrate external tools, internal APIs, and document sources through tool-calling and MCP-style patterns.
Cost Analysis and Unit Economics
Model the per-request and per-user cost of every AI feature before it ships.
Track token usage, prompt caching, batching, and model-routing strategies.
Drive measurable improvements in unit economics.
Production Hardening
Add observability and tracing (LangSmith, Langfuse, OpenTelemetry), guardrails, content safety checks, prompt injection defences, and fallback behaviour.
Prompt Engineering and Evaluation
Design, test, and iterate prompts with measured outcomes.
Build evaluation harnesses for accuracy, hallucination, latency, and cost.
Run benchmarks across models and prompt variants before locking in a design.
Requirements:
AI Feature Shipped to Production (Mandatory)
Must have personally built and shipped at least one AI feature that runs in production for real users, with operational ownership.
POCs, internal demos, and one-off scripts do not qualify.
2 to 4 Years of Professional Software or AI Engineering Experience
With at least one production AI feature owned end to end.
Strong Python Proficiency and API Development with FastAPI
Comfort with type hints, async, packaging, testing, streaming responses, and authentication.
Production-grade Python, not notebook-only code.
Hands-on Depth Across the LLM and Agent Stack
Working experience with at least two of OpenAI, Anthropic Claude, Google Gemini, or self-hosted open-weight models (vLLM, Ollama, Together, Replicate).
Working familiarity with at least one agent framework (LangGraph, CrewAI, AutoGen, LlamaIndex Agents) or hand-rolled equivalent.
Working knowledge of RAG, embeddings, and vector databases (Pinecone, Weaviate, Qdrant, pgvector, Chroma).
Solutioning Speed and POC Velocity
Demonstrated ability to move from a fuzzy problem to a working prototype in days.
Strong instinct for what to build first, what to defer, and what to throw away.
Cost Discipline for Production AI
Ability to calculate, monitor, and optimise the cost of LLM APIs, tokens, embeddings, vector store usage, and infrastructure.
Treats unit economics as a first-class concern.
AWS Familiarity
Working knowledge of EC2, S3, IAM, and at least one of Bedrock, SageMaker, or equivalent.
Comfortable in a Fast-Moving Environment
Self-directed, comfortable with ambiguity, takes ownership without being asked, and ships under shifting priorities.
Strong Written and Spoken English Communication
Able to explain trade-offs to non-AI engineers, designers, product managers, and clients in plain language.
Nice to Have
- fine-tuning or LoRA, QLoRA, PEFT exposure
- MCP server authoring
- eval framework experience (LangSmith, Promptfoo, Ragas, DeepEval)
- open-source AI contributions
- multi-modal models (vision, audio)


Shubham Vishwakarma
Full Stack Developer - Averlon


About Unico Connect Private Limited
About
Building quality products are a challenge !
Taking up challenges is our way of upscaling our performance.
Unico Connect is a digital product development company based in Mumbai, India, that comprises of a team of young enthusiastic nerds who thrive on great ideas and exciting projects that look to bring innovative changes in the world. We ideate, create and execute exceptional digital products that revolutionizes the face of modern business.
Photos
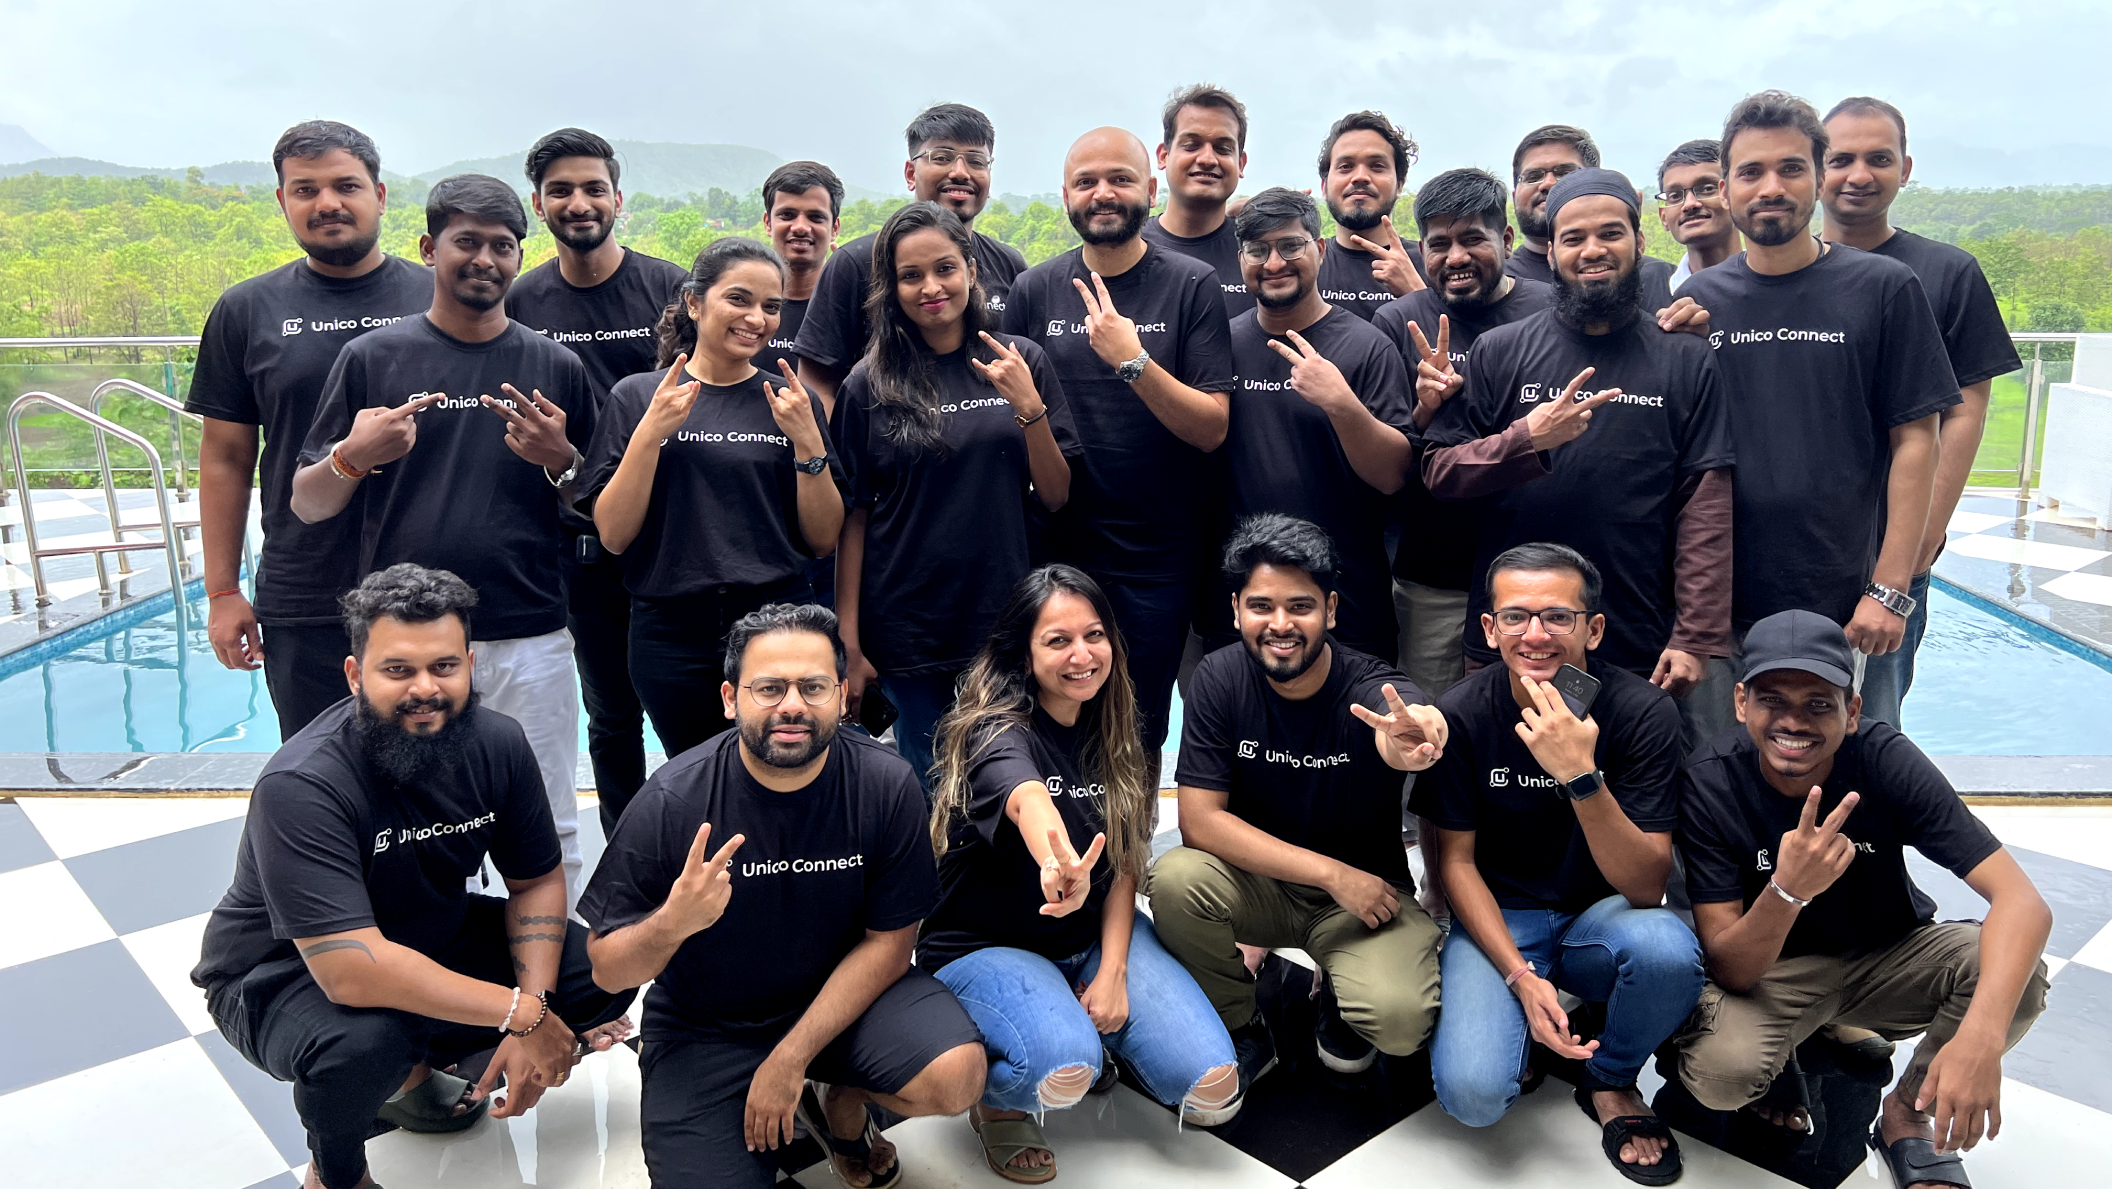
Company social profiles


Similar jobs (10)
 Python
Senior AI Engineer
Code Generation, Agent Architecture & LLM Systems
📍 Mumbai (On-site) | Full-time | 5+ years
About the Role:
Unico Connect is an AI-first technology partner that builds custom mobile, web, and AI products for clients across multiple geographies.
We are hiring a Senior AI Engineer for a dedicated client engagement focused on building an AI-powered application builder platform - a product where users describe software in plain English and the system generates, previews, and iteratively refines working code.
The mandatory requirement for this role is hands-on production experience shipping LLM-powered systems with agent architectures, with experience in code generation or developer tooling contexts a strong advantage.
The role is product-focused and deeply hands-on. You will own everything between the user's prompt and correct code landing in the project: the agentic loop, code generation pipeline, context management, evaluation suite, and model cost strategy.
You will work alongside the Senior MLOps Engineer who operationalises the infrastructure around your system, and collaborate closely with backend, frontend, and DevOps engineers.
Responsibilities:
Agent Architecture
Design and own the agentic loop for the platform - request interpretation, planning, tool-calling sequence (read file, edit file, run build, search code, install package), and stop conditions.
Make and revisit architectural decisions on single-agent vs. multi-agent designs, including planner/executor splits and dedicated build-repair sub-agents.
Code Generation Pipeline
Own the end-to-end generation flow: task classification, context gathering, planning, targeted edits, verification, and commit.
Implement diff/search-replace-based file editing with fuzzy matching and fallback strategies.
Enforce scope discipline so the agent makes minimal diffs and does not modify code it was not asked to touch.
Self-Repair Loop
Build and tune the automated repair loop that pipes compiler, lint, build, and runtime errors back to the model with retry budgets and model escalation.
This loop is the primary quality lever - the difference between 60-70% and 90%+ build success rates.
Context Management
Build file-relevance retrieval so the agent sees the right files, not the whole codebase: dependency graphs, AST/tree-sitter-based chunking, embeddings, recency signals, and hybrid retrieval.
Implement conversation summarisation and memory for long sessions, and address long-project degradation through codebase summaries and periodic consistency passes.
Own token budgeting and prompt caching strategy.
Prompt Engineering as a Discipline
Own the system prompt and per-task prompt variants (new feature, bug fix, styling change).
Maintain few-shot examples and enforce coding conventions, stack rules, and prohibited behaviours such as no hardcoded secrets and no whole-file rewrites.
Version prompts like code with changelogs and rollback capability.
Evaluation and Quality Measurement
Design and own the evaluation suite: representative test prompts run on every prompt and model change, scored on build success rate, instruction adherence, and output quality including LLM-as-judge and visual/screenshot checks where relevant.
Define regression gates that block quality-degrading changes from shipping.
Treat evals the way engineers treat automated testing: versioned, automated, and tracked over time.
This responsibility is non-negotiable at this level.
Model Strategy and Cost
Design model routing - cheap and fast models for classification and small edits, frontier models for complex generation.
Drive cost optimisation through prompt caching, diff-based edits over full-file rewrites, and tighter context selection.
Track cost per agent run and tokens per task; evaluate new model releases against the eval suite and lead migrations when results justify it.
Safety and Reliability of Agent Behaviour
Defend against prompt injection from user content and fetched web content.
Ensure secrets never appear in generated client code.
Define what the agent's tools may and may not do in collaboration with the platform team.
Contribute to output moderation and abuse-pattern awareness.
Mentorship and Engineering Standards
Run code reviews, define engineering conventions for AI work, and raise the engineering bar across the AI team.
Work closely with the Senior MLOps Engineer on handoff of eval design, prompt configurations, and model routing logic.
Requirements:
Hands-on Production Ownership of LLM-Powered Systems with Agent Architectures (Mandatory)
Must have personally shipped and operated at least one complex production AI system - agentic, multi-step, or code generation - with end-to-end ownership of architecture, evaluation, and cost.
POCs, internal demos, and tutorial-grade work do not qualify.
5+ Years of Professional Software or AI Engineering Experience
With at least 3 years focused on LLM applications, AI engineering, or production AI systems.
Candidates with strong backend backgrounds and a clear, substantive pivot into LLM systems qualify.
Strong Python Proficiency and Service Development
Production-grade Python with FastAPI or equivalent: type hints, async patterns, streaming responses, testing, and packaging.
Not notebook-only.
Depth Across LLM APIs and Agent Systems
Production experience with at least two of OpenAI, Anthropic Claude, Google Gemini, or open-weight models (vLLM, Ollama, Together).
Production experience with at least one agent framework (LangGraph, CrewAI, AutoGen, LlamaIndex Agents) or hand-rolled equivalent.
Hands-on with tool calling, structured outputs, and multi-step reasoning.
Demonstrated, Systematic Evaluation Practice - Non-Negotiable
Must have built evaluation harnesses that gate production releases, not ad-hoc testing.
Hands-on with at least one of LangSmith, Langfuse, Promptfoo, Ragas, or DeepEval.
Candidates with no systematic answer to evaluation should not be considered at senior level regardless of other strengths.
Cost Discipline for Production AI
Track record of measurable cost optimisation on production AI features.
Able to speak in specifics: cost per request, savings achieved through caching or model routing, context reduction decisions.
AWS Working Knowledge
Hands-on with EC2, S3, IAM, and Docker.
Comfort with CI/CD workflows and deploying AI services.
Awareness of LLM Security Failure Modes
Familiar with prompt injection patterns, understands that system prompt rules alone are insufficient, and has experience with output validation and content safety in production.
Nice to Have
- Experience with AST/tree-sitter tooling, diff-based editing systems, or compiler-adjacent work
- MCP server authoring
- Open-source AI contributions
- Published technical writing on LLM systems
- Multi-modal model experience
- Fine-tuning exposure (LoRA, QLoRA, PEFT)


Job Description – AI Engineer (End-to-End Development & Deployment)
Role Summary
We are looking for an AI Engineer with hands-on experience in designing, developing, deploying, and maintaining Generative/Agentic AI solutions in production. The ideal candidate should have end-to-end ownership of AI applications, from development to deployment, monitoring, and optimization.
Key Responsibilities
● Design, build, and deploy Generative/Agentic AI solutions.
● Develop applications using LLMs, RAG, AI agents, and vector databases.
● Build scalable APIs and integrate AI solutions with enterprise applications.
● Implement CI/CD pipelines, containerization, and MLOps best practices.
● Monitor, optimize, and maintain production AI systems.
● Collaborate with cross-functional teams to deliver business-driven AI solutions.
Required Skills
● Strong programming skills in Python.
● Experience with vector databases (e.g., Pinecone, FAISS, ChromaDB) and graph memory systems
● Knowledge of atleast one agent development framework: Google ADK (preferred), LangChain/LangGraph/LlamaIndex, CrewAI
● Experience with LLMs, RAG, GenAI, AgenticAI Agents
● Hands-on experience with FastAPI, and REST APIs.
● Knowledge of Docker, Kubernetes, Git, CI/CD.
● Experience with AWS, Azure, or GCP.
● Experience with security compliance, monitoring and observability tools such as AWS CloudWatch, Azure Monitor, Google Cloud Monitoring.


 Data SciencePython
Support with design and build to prove out agentic AI solution flow by working with other data
scientists and engineers to build, train Large Language Model (LLM) architectures, RAG
systems, and autonomous agentic workflows
Key qualifications:
>> AI solution design & Development: Design Agentic AI solutions using RAG (Retrieval-
Augmented Generation) and orchestration frameworks like LangGraph or LangChain.
>> Model Fine-Tuning: Solid understanding and experience with Pre-train, fine-tune, and
optimize open-source like BERT, LLama, and other proprietary foundation models for domain-
specific tasks
>> Solid Stats and ML foundations and (vibe) coding skills with Python, PySpark
>> Implement validation frameworks and tracing practices (using tools like Arize) to monitor
agent behavior, guard against model drift, and ensure compliance
>> Collaborate with Engineering to deploy models securely on cloud and on-prem ecosystems
 Python
Product Engineer — Role Summary
We are looking for a Product Engineer to build user-facing products that combine AI capabilities with practical applications. You will work at the intersection of software engineering and AI, developing autonomous, agent-driven systems that solve complex educational and research problems.
Key Responsibilities:
- Product Development: Design, build, and deploy production-ready applications powered by LLMs and AI agents.
- Data Engineering: Build scalable ETL/ELT pipelines to process structured and unstructured data, including text and audio, for RAG and model fine-tuning.
- Agentic Workflows: Develop multi-step AI agents with tool calling, APIs, databases, search, reasoning, and memory.
- Rapid Prototyping: Turn ideas and research concepts into interactive, production-ready applications.
- AI Integration: Use frameworks such as LangChain, LlamaIndex, AutoGen, or custom orchestrators to integrate AI into scalable systems.
- User Experience: Transform raw AI outputs into reliable, intuitive, and responsive user experiences.
- Collaboration: Work closely with ML researchers and data engineers to integrate custom and fine-tuned models.
- Observability: Monitor agent behavior, manage edge cases, reduce hallucinations, and improve reliability in production.
The ideal candidate combines strong software engineering, AI/LLM expertise, data engineering, and product thinking, with the ability to take an AI concept from prototype to production.
Python Machine Learning (ML)
The Role
You own AI systems end to end. From the speech-to-text models that turn audio into text, to the diarization that separates and identifies speakers, to the agentic layer that turns conversation into memory and action, to the observability and evaluation that keep all of it honest in production. This is a wide role by design. You will own model selection, serving, and production reliability. If you want to tune one model and ignore the system around it, this is not the role.
What You Will Own
• Speech-to-text. Evaluate, integrate, and optimize STT models across cloud and self-hosted. Drive accuracy and cost trade-offs with ground-truth metrics.
• Speaker diarization and identification. Push accuracy on hard, real-world, multi-speaker audio.
• Agentic AI. Build the memory and retrieval pipeline, LLM orchestration, and the agent workflows that sit on top of captured conversation.
• Model serving and infrastructure. Stand up and optimize self-hosted serving (vLLM, Triton class). Own latency, throughput, and cost per user.
Observability
An always-on wearable means models run in production every second, on messy real-world audio. You own the visibility into that.
• Instrument the full audio-to-memory pipeline: STT, diarization, retrieval, and LLM calls.
• Define and track model-quality SLOs in production: transcription drift, diarization error over time, retrieval relevance, latency, throughput, and cost per user.
• Build dashboards and alerting so model degradation is caught before users feel it.
• Trace failures across a distributed, always-on system using metrics, logs, and traces.
• Close the loop. Production signals feed back into evaluation and model selection.
Evaluation
We do not ship what we cannot measure. You own the systems that prove a model is actually better, not just newer.
• Build and own ground-truth evaluation harnesses for every model in the stack.
• Measure with real metrics: WER for transcription, DER for diarization, Recall and F1 for retrieval and speaker identification.
• Build and maintain labeled benchmark datasets that reflect real, messy, multi-speaker audio.
• Run regression and A/B evaluations on every model swap, prompt change, or pipeline update. Nothing ships on a vibe.
• Reject anecdotal proxies, single confidence scores, and cherry-picked examples as evidence of quality.
What We Are Looking For
• 3 to 5 years as an AI/ML engineer with production systems behind you. Engineering and production experience is non-negotiable.
• Depth across the modern AI stack: LLMs, speech models, vector retrieval, model serving.
• Strong software engineering. You write code that ships and survives contact with real users.
• Fluency in Python and the production ML ecosystem.
• Comfort with cloud infrastructure (GCP a plus) and containerized deployment on Kubernetes.
• A working command of observability and evaluation. You measure first and trust metrics over intuition.
• First-principles reasoning and metric discipline.
Nice to Have
• Research background or publications. A strong signal, not a substitute for production work.
• Audio and speech ML experience (STT, diarization, voice).
• Experience self-hosting and optimizing open models.
• Experience with LLM gateway and agent orchestration patterns.
• Experience building eval harnesses or production model-monitoring systems.
Requirements
Agentic work is must. Audio is good to have
. Self hosting models is a must
Experience with LLM gateway and agent orchestration is a must have
 Python
 Javascript
Location: Hyderabad, India (home base), deployed at client sites in India. Occasional Middle East exposure possible.
About the Role
You will work as a senior AI engineer who embeds inside a customer's business. Your job is to learn how the business makes money, find the highest value problem, and build a working system that solves it.
Four behaviors define this role:
- Go where the work happens. You work onsite with the customer, in the room where decisions are made.
- Show working software early. You build a prototype in days, not a document in weeks.
- One person owns the outcome. You are the single point of accountability for the result.
- Stay after go-live. You keep running and improving the system after launch.
You are the single point of accountability. You are not a solo builder. A full KnackLabs engineering team in Hyderabad builds and runs the production systems behind you.
This role involves extended onsite deployments at client locations in other cities, sometimes up to six months at a stretch. Please apply only if you are ready for this way of working.
What you'll own
- Discovery - Learn how the customer makes money. Find the highest value problem to solve first.
- The prototype - Build a working prototype fast, using real or sample data, to prove the idea.
- The roadmap - Decide what to build, in what order, and set clear success measures tied to business outcomes.
- The build - Design and ship the production system with the Hyderabad engineering team. This includes data integration, agents, retrieval, and evaluations.
- The client relationship - Be the trusted technical contact for the customer, from engineers to senior leaders.
- Go live and after - Deploy the system, watch how it performs, fix problems, and improve it over time.
- Feedback to the product - Share what you learn in the field so the vendor's product and our internal tools get better.
What we are looking for
- Around 4 or more years of software engineering experience, including customer-facing or client delivery work.
- Strong programming skills in Python. Working knowledge of TypeScript or JavaScript.
- A full-stack development experience with strength in backend technologies.
- Production experience with large language models, including prompt engineering and agent development.
- You build with AI coding tools like Claude Code or Codex as your default way of working, and you have shipped real apps or agents this way.
- Experience building retrieval-augmented generation (RAG) systems: chunking, embeddings, vector databases, retrieval, and reranking.
- Experience building and deploying AI systems.
- Experience integrating with APIs and enterprise systems.
- Experience with at least one cloud platform (AWS, Azure, or GCP).
- Clear communication. You can explain a technical choice to an engineer and to a business leader.
- High ownership and comfort with ambiguity. You can take an unclear problem and turn it into a plan.
- Willingness to work onsite at client locations in India for extended periods, and to travel as the work needs.
Nice to have
- Experience with on-premises or private cloud (VPC) deployments.
- Experience with observability and tracing tools such as LangSmith or Braintrust.
- Experience with data engineering and pipelines.
- A history of side projects, open source contributions, or products you shipped end-to-end.
- Experience in embedded or forward-deployed roles before.
- Experience working at a consulting or professional services firm in a client-facing delivery role.
Stack and tools
- Languages: Python and TypeScript.
- Models: Claude and other frontier or open-source models, chosen to fit the customer.
- AI patterns: RAG, agents, prompt engineering, and evaluations.
- Vector and retrieval: vector databases and retrieval pipelines.
- Cloud: AWS, Azure, or GCP, on public or private cloud.
- Integration: REST APIs and enterprise system connectors.
 Python
Role Overview
We are looking for a Python Developer with strong experience in Generative AI and LLM-based applications. The candidate should have hands-on experience building AI solutions using Python, RAG, LangChain/LangGraph, and related GenAI technologies.
Mandatory Skills
Python, GenAI/LLM, RAG, LangChain/LangGraph, Agentic AI, FastAPI, REST API, Vector Database, Prompt Engineering, Microservices
Key Responsibilities
- Develop and maintain applications using Python and modern frameworks.
- Build GenAI/LLM-based applications and solutions.
- Develop RAG pipelines using vector databases.
- Work with LangChain/LangGraph for LLM and agent-based applications.
- Develop and integrate REST APIs using FastAPI.
- Implement Agentic AI workflows and AI-powered features.
- Integrate LLMs with existing applications and microservices.
- Apply prompt engineering techniques to improve AI application performance.

Role Overview
We are looking for an AI Engineer to design, build, and ship production AI systems, including agentic AI applications, for enterprise clients. This is a hands-on engineering role: you will write production code, build and evaluate models and agents, and work closely with architects and product teams to take solutions from prototype to scale.
Key Responsibilities
Design and build agentic AI systems: agent workflows, tool/function-calling, memory, and human-in-the-loop patterns. Build and productionise RAG pipelines, prompt-based applications, and LLM integrations across providers. Develop and maintain data and ML pipelines: feature engineering, model training, evaluation, and monitoring. Integrate AI systems with enterprise applications (CRMs, ERPs, ITSM tools) via APIs, events, and MCP-based tool servers. Implement guardrails, prompt-injection defences, and evaluation frameworks to keep AI systems safe and reliable in production.
Write clean, tested, production-grade code and participate actively in code and design reviews.
Collaborate with architects, product managers, and delivery teams to translate requirements into working AI solutions. Troubleshoot and optimise AI systems for accuracy, latency, and cost in production.
Required Qualifications
8–12 years of hands-on software engineering experience, with a strong, unbroken technical track record. Hands-on experience building and shipping AI/ML systems in production, not just POCs.
Practical experience with agentic AI systems and at least one major agent framework (LangGraph, CrewAI, AutoGen, OpenAI Agents SDK, Bedrock Agents/Strands, or Semantic Kernel).
Experience with LLM/GenAI systems: RAG pipelines, prompt engineering, structured outputs, and tool calling across providers.
Strong Python skills (TypeScript/Node.js a plus), with production-grade testing, CI/CD, and API design practices. Working knowledge of ML fundamentals: model evaluation, feature engineering, and experimentation. Cloud-native experience on AWS and/or Azure: containers, serverless, event backbones, and vector databases. Understanding of LLM safety and reliability practices: guardrails, prompt-injection defences, and observability.
PythonJob Summary
We are looking for a skilled Python Developer with experience in Generative AI and Agentic AI to develop AI-powered applications and scalable backend services.
Mandatory Skills
- Python
- Generative AI (GenAI) / Large Language Models (LLMs)
- Retrieval-Augmented Generation (RAG)
- LangChain / LangGraph
- Agentic AI
- FastAPI
- REST API development
- Vector Databases
- Prompt Engineering
- Microservices
Key Responsibilities
- Develop and maintain Python-based applications and backend services.
- Build GenAI/LLM-powered applications and AI solutions.
- Implement RAG pipelines for document processing and information retrieval.
- Develop AI agents using LangChain/LangGraph and Agentic AI frameworks.
- Build and integrate REST APIs using FastAPI.
- Work with vector databases for embeddings, semantic search, and retrieval.
- Design and optimize prompts to improve LLM response quality.
- Develop scalable microservices and integrate AI models into applications.
- Collaborate with cross-functional teams to deliver AI-based solutions.
- Troubleshoot, test, and optimize application performance.
Required Qualifications
- 4–6 years of experience in Python development.
- Hands-on experience with GenAI/LLMs, RAG, and Agentic AI.
- Practical experience with LangChain/LangGraph, FastAPI, and REST APIs.
- Knowledge of vector databases, prompt engineering, and microservices.
- Strong problem-solving and debugging skills.
- Ability to develop and deploy production-ready AI applications.
About LeadSquared
LeadSquared is a leading sales execution and marketing automation platform trusted by 2,000+ businesses globally, including healthcare, education, financial services, and real estate. Headquartered in Bengaluru with offices across the US, UK, UAE, and Southeast Asia, we empower sales teams to close faster, smarter, and at scale.
Our AI team is at the forefront of integrating cutting-edge large language model capabilities into enterprise workflows — building intelligent agents, copilots, and automation systems that redefine how businesses operate.
Role Overview
We are looking for a Senior AI Engineer with hands-on experience building LLM-powered agents and agentic AI systems. You will design, develop, and deploy autonomous AI pipelines that solve complex, multi-step business problems — from lead qualification and follow-up automation to intelligent CRM workflows and beyond.
This role is ideal for someone who is deeply excited about the frontier of AI, can move fast, and wants their work to directly impact millions of sales professionals worldwide.
Key Responsibilities
•
Design and build LLM-powered agentic systems using frameworks such as LangChain, LlamaIndex, AutoGen, or CrewAI to automate complex, multi-step workflows.
•
Develop and maintain Retrieval-Augmented Generation (RAG) pipelines with vector databases (Pinecone, Weaviate, Chroma, pgvector) for domain-specific knowledge grounding.
•
Build and integrate tool-use and function-calling capabilities into AI agents, enabling dynamic interaction with internal APIs, databases, and third-party services.
•
Implement prompt engineering strategies including chain-of-thought, few-shot prompting, and structured output parsing to ensure reliable agent behavior.
•
Design evaluation frameworks and observability pipelines (LangSmith, Helicone, custom metrics) to monitor agent performance, accuracy, and cost.
•
Collaborate with product, sales, and domain teams to translate business requirements into AI-driven solutions and features.
•
Optimize LLM inference for latency and cost using techniques like caching, model distillation, quantization, and batching.
•
Stay current with the rapidly evolving LLM ecosystem and proactively propose improvements and new approaches.
•
Contribute to internal best practices, documentation, and knowledge-sharing across the engineering org.
Required Qualifications
Experience
•
2–4 years of professional software engineering experience, with at least 1–2 years focused on LLM/AI systems.
•
Proven experience shipping LLM-based products or agentic AI systems into production environments.
Technical Skills
•
Strong proficiency in Python and familiarity with async programming patterns for AI pipelines.
•
Hands-on experience with LLM APIs: OpenAI (GPT-4o), Anthropic (Claude), Google (Gemini), or open-source models (Llama, Mistral).
•
Experience with agentic frameworks: LangChain, LangGraph, LlamaIndex, AutoGen, CrewAI, or similar.
•
Solid understanding of RAG architectures, embedding models, and semantic search.
•
Experience with vector databases and similarity search infrastructure.
•
Knowledge of REST APIs, microservices architecture, and containerization (Docker/Kubernetes).
Problem-Solving & Mindset
•
Strong ability to decompose ambiguous, open-ended problems into structured AI system designs.
•
Experience with prompt debugging, LLM evaluation, and iterative refinement workflows.
•
Ability to balance research exploration with engineering pragmatism to ship reliable systems.
Preferred Qualifications
•
Experience with multi-agent orchestration and agent memory systems (short-term and long-term).
•
Familiarity with fine-tuning or RLHF workflows for domain adaptation.
•
Background in NLP, information retrieval, or conversational AI.
•
Prior experience in B2B SaaS or CRM domain is a plus.
•
Contributions to open-source AI/ML projects or published research/blogs.
•
Experience with cloud platforms: AWS, GCP, or Azure — particularly AI/ML services













 Follow Cutshort
Shubham Vishwakarma
Full Stack Developer - Averlon